---
title: "How do I check my AI's answers with a small test set?"
description: "Keep about 20 questions with known answers and run all of them after every change. A fix for one answer can break others that the score alone hides."
topic: "AI systems"
chapter: "trust-the-answers"
order: 13
minutes: { plain: 6, deep: 15 }
prerequisites: ["Reading short Python functions", "Percentages and simple fractions"]
seo_title: "How do I check AI answers with a small test set?"
date: 2026-10-19
---
# How do I check my AI's answers with a small test set?
A toy assistant (it follows fixed rules and is not a real model) answers 20 questions about a made-up bike shop's help page, and 12 of them pass. Turn on one instruction, “Say I don't know”, and it fixes 3 questions, such as “Do you deliver bikes?”, which it first answered with a sentence about warranties. The score rises to 13 of 20. The same change also breaks 2 questions that passed before. Looking at the 3 fixes alone, you would never know.
## In one minute
Keep a fixed list of about 20 questions with known answers, run all of them after every change, and compare the results question by question. A fix for the case you were looking at can break others you were not looking at. It is like a cook who, after changing a recipe, tastes the same short list of dishes, not only the one a customer complained about. The assistant in the demo is a toy, not a language model (the kind of program behind a chatbot), so its numbers are exact and you can follow every one.
## Explore the numbers
[Open the widget](https://spicyshark.co/learn/check-ai-answers-with-a-test-set/widget.html). It opens with one instruction on. Tap a square to see that question, its right answer and the check. Then turn the instructions on and off in turn and watch which squares turn green (fixed) or orange (broke), not only the score. Open More settings to make the toy vary from run to run.
## How it works
### A fixed list of questions
A test set is a fixed list of questions, each with the right answer written down before you change anything; it is the list you rerun after each change. Here there are 20, numbered Q1 to Q20. Most ask for a fact the page gives, such as “What does a full overhaul cost?”. Four ask something the page never says, where the right answer is “I don't know” (see [Why does AI make things up?](https://spicyshark.co/learn/why-ai-makes-things-up/)).
A grader is a small check that reads one answer and says pass or fail. The pass rate is the share of questions that pass: 12 of 20 is 60%. The instructions are the text that tells the assistant how to behave. The toy has three instruction switches: Page only, Say “I don't know” and One sentence. The starting instructions have all three off.
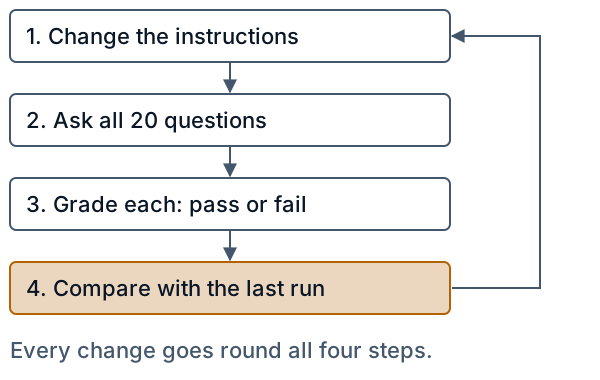
*Figure 1. The loop to run after every change.*
### Compare question by question
After each change, line the new results up against the old ones and give each question one of four labels: fixed (failed before, passes now), broke (passed before, fails now), still passes and still fails. This is the compare step.
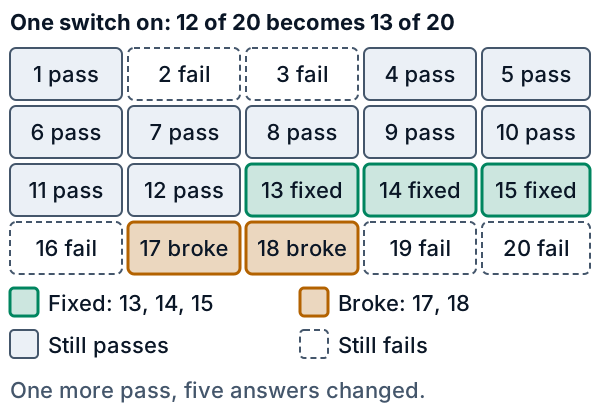
*Figure 2. One switch on: three questions fixed, two broke, and the score moves from 12 to 13.*
Say “I don't know” makes the toy refuse when its best match with the page is weak. That fixes Q13, Q14 and Q15, where refusing is right. It breaks Q17, “Can I leave my bicycle by the door?”, and Q18, “What do I pay for a whole week?”. The page does answer both, but in other words, so the match looks weak and the toy refuses. The score rose by one while five answers changed.
The One sentence switch does something else: it fixes 2 questions and breaks 2, so the score stays at 12 of 20. A flat score can hide a swap.
### How much one run tells you
With 20 questions, one question is 5 points. Is 13 of 20 really better than 12 of 20? A range helps. The Wilson score interval is a standard formula for the range a pass rate could plausibly sit in. Its 95% range for 12 of 20 is 39% to 78%, and for 13 of 20 it is 43% to 82%. A 95% range means that if you built ranges this way again and again, about 95 in 100 would hold the true rate (the rate on a huge set of similar questions).
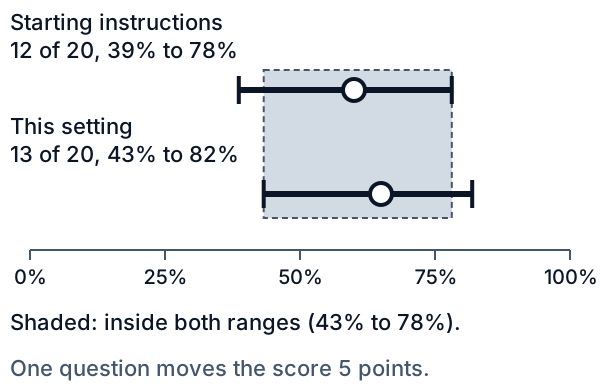
*Figure 3. The 95% ranges for 12 of 20 and 13 of 20 overlap from 43% to 78%.*
The ranges overlap almost completely, so a gap of one question could be chance. More questions narrow the range. At a rate near 65%, 20 questions give 43% to 82%, 100 give 55% to 74% and 400 give 60% to 70%.
Run-to-run variation adds more noise, meaning differences that come from chance and not from your change. A real model can answer the same question differently on two runs; the lesson [Why does the same question give different answers?](https://spicyshark.co/learn/why-the-same-question-gives-different-answers/) covers why. In More settings the toy does the same: each result flips with a 1 in 10 chance, from a fixed table. Over 5 runs the starting instructions score 10 to 14 of 20, and in run 5 the change that won the first four runs scores 13 against 14. One run of each is not enough to call a winner.
### The toy is a toy
The toy follows fixed rules, so the same switches always give the same answers and every number here can be checked. A real model answers by probability, and real answers are free text, which is harder to grade. Go deeper lists what the toy leaves out.
## What this means when you build
- **Start with about 20 questions from real use.** Write the right answer for each before you change anything, or you will grade to whatever the assistant said.
- **Run the whole list on every change** to the prompt or the model, including a new version of the same model.
- **Read the fixed and broken lists, not only the rate.** A flat or rising score can hide a swap.
- **Add every bug a user finds as a new question.** The list then follows the failures you really see.
- **Keep the checks simple and test them.** A check that passes a wrong answer is a bug. Try each one on a few right and wrong answers.
- **Treat a one-question gap as weak evidence** until more questions or more runs agree.
- **Keep a few questions back.** If you tune the instructions until the list passes, the list stops telling you anything new. Questions you never tuned on show whether a gain is real.
## Go deeper
*Optional, for readers who write Python. The code is in the `code/` folder: `toy.py` is the assistant, `evalset.py` holds the questions, graders, compare step and interval, and `test_evalset.py` and `test_widget.py` are the tests. `python3 show_numbers.py` prints every number above, and `python3 -m pytest -q` runs the tests.*
### The help page and the 20 questions
The page is 15 one-fact sentences (`PAGE` in `toy.py`), for example “A basic tune-up costs $60.” and “Used parts cannot be returned.” Each row below is one entry of `QUESTIONS`: the question, its right answer in bold, and the kind of check.
| # | Question | Check |
|---|---|---|
| 1 | What time do you open on weekdays? **9am to 6pm** | words |
| 2 | What are the opening hours on Saturday? **10am to 4pm** | words |
| 3 | How many days does a basic tune-up take? **2 days** | number |
| 4 | What does a full overhaul cost? **$140** | words |
| 5 | How much is the deposit on a rental? **$100** | number |
| 6 | What does a city bike cost to rent for a week? **$60 a week** | words |
| 7 | How long is the warranty on repairs? **90 days** | number |
| 8 | When are the riding lessons? **Saturdays at 11am** | words |
| 9 | Is the shop open on Sunday? **No, closed** | exact |
| 10 | What are your hours on Saturday and Sunday? **10am to 4pm; closed Sunday** | words |
| 11 | What is the warranty on repairs and on a bike bought here? **90 days; 2 years** | words |
| 12 | How many months is the warranty on a bike bought here? **24 months** | words |
| 13 | Do you deliver bikes? **page does not say** | unknown |
| 14 | Do you sell helmets? **page does not say** | unknown |
| 15 | Are you open on public holidays? **page does not say** | unknown |
| 16 | Is there a student discount on a basic tune-up? **page does not say** | unknown |
| 17 | Can I leave my bicycle by the door? **Yes, free parking at the front door** | words |
| 18 | What do I pay for a whole week? **$60 a week** | words |
| 19 | Can I return a part after 40 days? **No, only within 30 days** | words |
| 20 | What does a bicycle rental cost for one day? **$15 a day** | words |
Q10, Q11 and Q12 need two sentences, or a change of units, put together. Q17 to Q20 ask in other words than the page uses. Q16 looks like a question the page answers, because it shares words with the tune-up lines, but the page has no discount.
### The toy's rules
The toy drops small words (`STOP`) and word endings (`stem`), so “bikes” matches “bike”. It then counts the words each page sentence shares with the question and ranks the sentences, keeping page order on a tie. `answer` turns that ranking into a reply:
```python
def answer(question, d):
"""What the toy says to one question under the instructions d."""
(best, i), (next_best, j) = ranked(question)[:2]
if best == 0:
return DONT_KNOW if d.page_only or d.dont_know else GUESS
if d.dont_know and best < MIN_SHARED:
return DONT_KNOW
said = [PAGE[i]]
if next_best >= ALSO_SHARED and not d.one_sentence:
said.append(PAGE[j])
text = " ".join(said)
if not d.page_only and "month" in words(question):
text = re.sub(r"(\d+) year", lambda m: f"{int(m.group(1)) * 12} month", text)
return text
```
With no switch on, a question that shares no word gets the guess “Yes, we do.” “Do you deliver bikes?” shares one word, “bike”, with four sentences, and the first on the page is the warranty one, so that is the reply. Each switch is one line of this function:
- **Page only** (`page_only`): no guess when nothing matches, and no unit change. It fixes Q14 and breaks Q12, which needs the change from 2 years to 24 months.
- **Say “I don't know”** (`dont_know`): refuse when the best sentence shares fewer than `MIN_SHARED` = 2 words. It fixes Q13, Q14 and Q15 and breaks Q17 and Q18, which share one word each.
- **One sentence** (`one_sentence`): never add the second sentence. It fixes Q2 and Q3, where the extra sentence added the weekday hours or a price, and breaks Q10 and Q11, which need two.
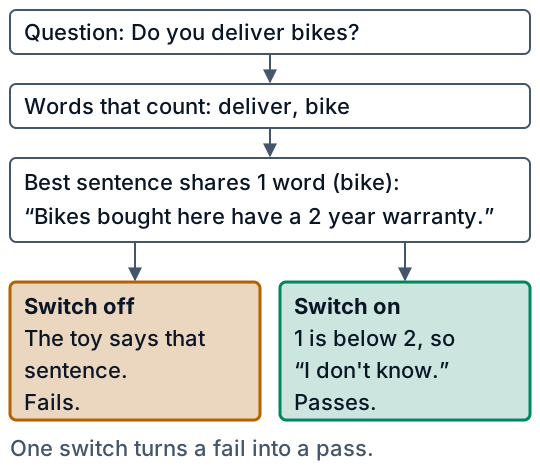
*Figure 4. Q13 under the Say “I don't know” switch, off and on.*
All 8 settings, compared with the starting instructions (12 of 20). A setting's score is 12 plus Fixed minus Broke, so only `know` and `know + one` rise, both to 13. In the first column, `one` is One sentence, `know` is Say “I don't know” and `page` is Page only.
| Switches on | Fixed | Broke |
|---|---|---|
| none | 0 | 0 |
| one | 2 | 2 |
| know | 3 | 2 |
| know + one | 5 | 4 |
| page | 1 | 1 |
| page + one | 3 | 3 |
| page + know | 3 | 3 |
| all three | 5 | 5 |
Q1, Q4, Q5, Q6, Q7, Q8 and Q9 pass under all 8 settings. Q16, Q19 and Q20 fail under all 8, so no switch fixes them: Q16 shares 3 words with the tune-up lines, so the refusal never fires; Q19 would need to compare 40 with 30, and the toy never says “no”; and Q20 shares only “day” with the sentence that holds the answer, no better than the tune-up and overhaul lines, so the toy says the first tied line (the tune-up price) or, with Say “I don't know” on, refuses. Questions like these are what the list is for. They show what a change cannot do.
### The graders and their tests
`passes` runs one of four graders. **words** needs every phrase to appear as whole words and none from the avoid list (Q2 must not contain “9am”). **number** compares the whole numbers in the answer with the expected set. **unknown** looks for a phrase such as “does not say” or “I don't know”. **exact** compares the text with one sentence (for Q9, “Opening hours on Sunday: closed.”), ignoring capitals and punctuation.
```python
def has(text, phrase):
"""True when phrase appears in text as whole words: "no" is not found in "I do not know"."""
return f" {norm(phrase)} " in f" {norm(text)} "
```
A looser check fails quietly, so the tests try answers it would let through. Each of these must fail in `test_evalset.py`:
- Q7, “Repairs have a 190 day warranty.”: the text “90” is inside “190”, which a plain substring check accepts.
- Q19, “I do not know.”: “no” is inside “not” and “know”, which `has` rules out by matching whole words.
- Q3, “A basic tune-up takes 2 days. A full overhaul takes 5 days.”: the right number is there with a wrong one beside it, so the number grader wants the set to be exactly {2}.
- Q2, a reply that holds the weekday hours and the Saturday hours: it has “10am to 4pm” and also “9am”.
- Q13, “Yes, we do.”: neither a fact nor a refusal.
The test file also holds a good answer for each of the 20 questions, so a grader that rejects a right answer is caught as well. Both mistakes distort the pass rate, and the pass rate is the thing you trust.
### The compare step
```python
def compare(before, after):
"""Per question: "fixed", "broke", "pass" (still passing) or "fail" (still failing)."""
return [("fixed" if not b else "pass") if a else ("broke" if b else "fail") for b, a in zip(before, after)]
```
`before` and `after` are lists of True and False, one per question. The widget colours its squares from this list and prints the counts.
### The interval, with one worked example
```python
def wilson(passed, n, z=Z):
"""Wilson score interval for a proportion: (low, high) as fractions."""
p = passed / n
centre = p + z * z / (2 * n)
spread = z * math.sqrt(p * (1 - p) / n + z * z / (4 * n * n))
shrink = 1 + z * z / n
return (centre - spread) / shrink, (centre + spread) / shrink
```
For 13 of 20, p = 0.65, and z = 1.96 is the multiplier for a 95% range. Then centre = 0.65 + 1.96² / 40 = 0.7460, spread = 1.96 × √(0.65 × 0.35 / 20 + 1.96² / 1600) = 0.2300, and shrink = 1 + 1.96² / 20 = 1.1921. The range is (0.7460 − 0.2300) / 1.1921 = 0.4329 to (0.7460 + 0.2300) / 1.1921 = 0.8188, which is 43% to 82%.
The NIST/SEMATECH e-Handbook of Statistical Methods, section 7.2.4.1 (read 2026-10-19), gives this formula and works one example: 26 out of 200 (13%), with a one-sided 95% limit (z = 1.645), for which it gives a lower limit of 0.09577. A test calls `wilson(26, 200, z=1.645)` and checks that the lower limit rounds to the same value. The method goes back to E. B. Wilson (1927), as the Wikipedia page on binomial proportion confidence intervals (read 2026-10-19) records.
Overlap is a rough guide, not a test: both runs use the same 20 questions, so a paired comparison can see a difference that two separate ranges do not. Here 3 fixed against 2 broke is itself a small difference.
### Run-to-run variation
`wobble` builds a table of 5 runs by 20 questions with `random.Random(5)`. Where an entry is True, that question's result comes out the other way, with a 1 in 10 chance. The table is the same for every setting and is embedded in the widget, which therefore needs no random numbers of its own. Because every setting uses the same row, the noise cancels in part when you compare two settings; real re-runs would flip each setting separately, so the real spread is wider. One row per run, runs 1 to 5 from the top. Start is the score of the starting instructions out of 20, and Know is the score with the Say “I don't know” switch on, with Fixed and Broke counted against Start:
| Start | Know | Fixed | Broke |
|---|---|---|---|
| 10 | 13 | 4 | 1 |
| 11 | 12 | 3 | 2 |
| 10 | 13 | 4 | 1 |
| 11 | 12 | 3 | 2 |
| 14 | 13 | 2 | 3 |
Run 5, the last row, reads “fixed 2, broke 3: 70% to 65%”: the better change looks worse. Seed 5 shows a spread of 4 questions, a little above typical: across 2,000 seeds the median spread of the starting instructions over 5 runs is 3, and it is 4 or more in 32% of seeds. In the toy, in 10,000 single runs, the switch scored below the starting instructions 22% of the time even though, without variation, it scores one higher.
### Proof it works
```bash
cd lessons/check-ai-answers-with-a-test-set/code
python3 -m pytest -q
```
The tests guard what a reader would see go wrong. Every grader accepts a right answer and rejects the tempting wrong ones above. The starting instructions pass 12 of 20, and each switch's exact fixed and broken lists are checked, so a rule edit that moves them fails. The interval equals the NIST value. The lesson's code blocks are verbatim excerpts of the source. `test_widget.py` runs the widget's JavaScript in Node.js (a way to run JavaScript outside a browser) for all 8 settings and 5 runs and checks that every answer, result and range equals the Python one. It also runs the page script against a stand-in page and reads back the headline and the squares, and checks that the widget asks for nothing online and holds no form.
### What the toy leaves out
- **Free text is harder to grade.** Real answers are sentences. A simple check misses right answers in other words and passes wrong ones. A person can grade them, or a second model can act as the judge. Zheng and colleagues (arXiv 2306.05685, read 2026-10-19) report that, when asked which of two answers is better and ties are left out, strong model judges agreed with human preferences over 80% of the time, about as often as humans agree with each other, and they also describe biases such as favouring the first answer shown or a longer one.
- **The judge can be wrong too.** Check a judge on answers you have graded by hand.
- **The 20 questions are not a sample of real use.** The range shows how far the score could move if you had picked different but similar questions. It does not say you chose the right questions.
- **It has no held-back questions.** Keeping some aside is practice, not a result measured here: tuning on the list is the way it stops telling you anything new.
- **One page, one assistant.** A real list covers many tasks, and a real model answers differently on each run.
### Where this is used in practice
OpenAI's guide “Working with evals” (read 2026-10-19) describes an eval as a test of whether model outputs meet criteria you specify. It lists three steps: describe the task, run it with test inputs, then analyse the results and iterate on the prompt. Its test data holds a correct label from a human for each input, its graders are called testing criteria, and its worked example uses an exact-match check on a small sample. It adds that you will often have to run more criteria, different prompts and different data sets. The page also says OpenAI is deprecating the Evals platform: Evals becomes read-only for existing users on October 31, 2026, and the platform is scheduled to shut down on November 30, 2026. The method does not depend on that product.
Anthropic's documentation on defining success criteria and building evaluations (read 2026-10-19) says to design evals that mirror your real task and to include edge cases. It names string-match, code-graded and model-graded options, says to automate when possible, and says more automatically graded questions with slightly weaker signal beat fewer hand-graded ones. A comment in its code notes that it is generally best to use a different model to grade than the one that wrote the output. Both pages cover test questions and grading methods in far more detail than this lesson.
## Skills this lesson builds
- Writing a test set: questions from real use, with the right answer written before the change.
- Writing graders and testing them on right answers and tempting wrong ones.
- Comparing two runs question by question instead of by pass rate alone.
- Reading a small pass rate with a range, and knowing a one-question gap can be noise.
- Keeping questions back so the list does not turn into something the instructions were tuned to.
**Portfolio project:** pick a small public help page or README. Write 20 questions about it with the answers written first, 4 of which the page does not answer. Write 4 graders in Python and test each on right and wrong answers. Build two versions of an assistant, which can be simple rules like the toy's, run both, and publish a table of fixed and broken questions with the Wilson range for each, plus 3 questions you kept back.
## Check yourself
1. In the toy, one switch fixes 3 questions and breaks 2, and the score goes from 12 to 13 of 20. What do you learn from the fixed and broken lists that the score does not show?
Answer
Five answers changed, not one. Two questions that used to pass, Q17 and Q18, now fail, so you can look at why a weak match makes the toy refuse a question the page does answer.
Answer
No. It swapped four answers: different questions pass now. The score hides a swap, which is why you compare question by question.
Answer
A gap of one question could be chance. Add more questions, or run more times, before calling one version better, and read the broken questions meanwhile.
Answer
Q19 needs the word “no” and “30 days”. `has` matches whole words after punctuation is removed, so “no” is not found in “not” or “know”. A plain substring check would pass it.
Answer
The instructions were shaped to this list, so passing it says little about new questions. Keep some questions back that you never tuned on, and add each new bug as a question.