---
title: "How can a small model speed up a big one?"
description: "A small AI model guesses the next few tokens and the big one checks them all at once, so the same reply arrives sooner. Here is how much, and when it fails."
topic: "AI systems"
chapter: "serving-many-chats"
order: 25
minutes: { plain: 6, deep: 20 }
prerequisites: ["Prefill and decode", "Division and ratios", "Reading short Python functions"]
seo_title: "How can a small AI model speed up a big one?"
date: 2026-10-19
---
# How can a small model speed up a big one?
A chatbot writes one token (a small piece of text, often a whole word) at a time, and each token costs one pass, a single run of the model. Take an AI model with 8 billion numbers inside, called weights, on one A100 chip built for AI work, helped by a smaller model that guesses ahead. In the best case it needs 7.88 milliseconds (ms, thousandths of a second) per token alone, and about 3.8 ms with four guesses at a time and 80% of them kept: 2.1 times as fast, with the same words. Real services are slower than these best cases, and this lesson says why.
## In one minute
A small model speeds up a big one by guessing the next few tokens, which the big model then checks all at once; the method is called speculative decoding. Picture a junior who writes the next few words of a letter and a senior who reads all of them at a glance. The senior keeps the words up to the first one they would have written differently and writes that word themselves. Reading a few words takes the senior about as long as writing one, so good guesses save time, poor ones save none, and the letter is always the one the senior would have written alone.
## Explore the numbers
[Open the widget](https://spicyshark.co/learn/how-a-small-model-speeds-up-a-big-one/widget.html) and drag the chance that a guess is kept. It shows best-case times from a model at the chip's peak speed, the most it can do, not measurements. At the opening setting the plain lane needs 17 big passes for a reply and the draft lane 5, with the same words. In this toy a token is a whole word.
## How it works
### Guess ahead, then check
Plain decoding makes one token per pass, as [Why do answers appear word by word?](https://spicyshark.co/learn/why-answers-appear-word-by-word/) shows. Speculative decoding adds a much smaller model, the draft model, which writes a few tokens first; each is only a guess. The big model then reads the text so far and all the guesses in one pass, and says what it would write at each place, including the place after the last guess. It keeps the guesses up to the first one that differs from its own choice, writes its own token there, and throws the rest away. If every guess matches, its token after them comes free. So one round, four guesses and one big pass, gives 1 to 5 tokens.
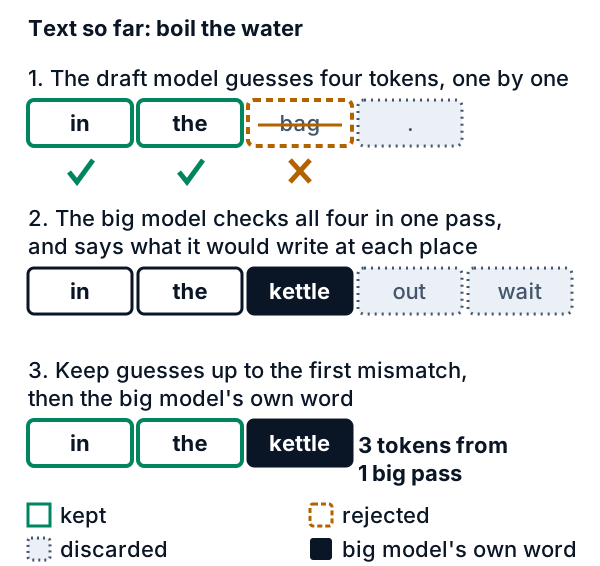
*Figure 1. One round after "boil the water". Green borders mark kept guesses, orange strikethrough the rejected one, dotted grey what is thrown away, black the big model's own token.*
### Why a check costs about one token
A pass has two jobs: fetch every weight from memory, and do the arithmetic, the sums, on them. It takes the longer of the two. [The lesson on the first-word wait](https://spicyshark.co/learn/why-ai-waits-before-the-first-word/) shows that for a short input, fetching is longer: the big model's 16 gigabytes (GB) of weights take 7.88 ms to fetch, whether the pass reads 1 token or 153. Checking four guesses reads 5 tokens, so the check still takes 7.88 ms; the chip had arithmetic to spare. From 154 tokens up, arithmetic takes longer and each added token costs time.
The draft model has the same two jobs with only 2.5 GB of weights, so one pass takes 1.21 ms, about 15% of a big pass. A round of four guesses costs four draft passes and one big pass: about 12.7 ms. At 80% kept a round brings 3.36 tokens on average, so each token costs 3.79 ms instead of 7.88.
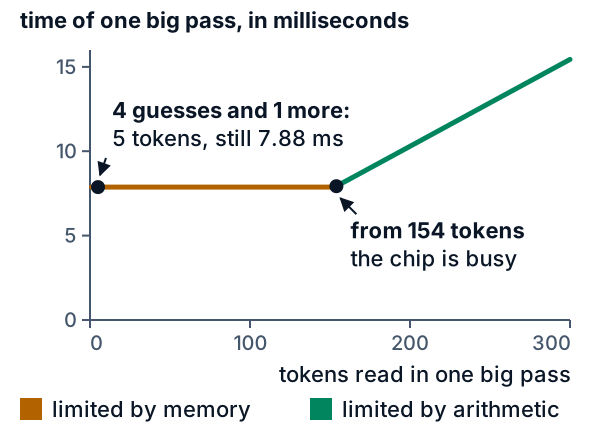
*Figure 2. Best-case time of one big pass against the tokens it reads. Orange is limited by memory, green by arithmetic. The dot is four guesses and one more token.*
### Why the words do not change
A guess is kept only where the big model would have written the same token; elsewhere the big model's own token is used. So when the model always picks its most likely token, the reply is word for word the one plain decoding writes, and Go deeper runs that check on a toy pair. When the model [picks tokens at random](https://spicyshark.co/learn/why-the-same-question-gives-different-answers/), a different keep rule leaves the big model's odds for every token exactly as they were. A poor draft model only costs time.
### When guessing pays
Every round pays for its draft passes whether or not the guesses are kept. With four guesses, the pair is faster than plain decoding only when more than about 39% of guesses are kept; at 60% it is 1.43 times as fast, at 80% 2.08 times and at 90% 2.53 times. More guesses help only while they are kept: the best number is 2 at 60% kept and 8 at 90%.
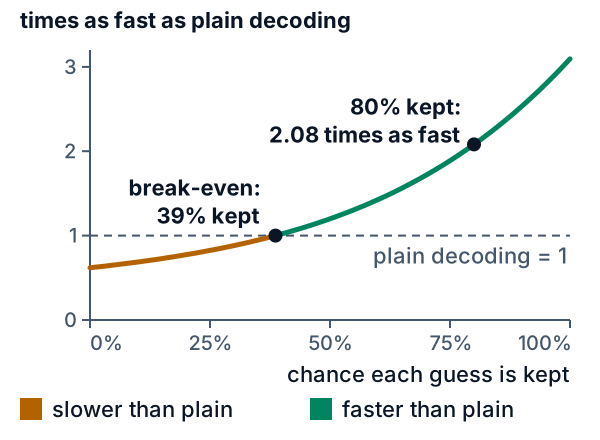
*Figure 3. Best-case speed-up with four guesses per round and a draft pass of 15% of a big pass. Orange is slower than plain decoding, green faster; the dot is the widget's opening setting.*
### What this toy leaves out
These are best cases at the chip's peak speed. How often guesses are kept depends on the text and the pair of models, and the formula behind these numbers treats guesses as independent chances, which they are not. A real small model runs further below peak than a big one, so its cost is a larger share than 15%. The draft model needs its own memory and notes about earlier tokens, and software adds time. With many users sharing the chip, the spare arithmetic runs out, as Go deeper shows.
## What this means when you build
- **Expect the same text, sooner.** Picking the most likely token gives the same words, and picking at random keeps the same odds. If a draft changes your answers beyond rounding, suspect the implementation.
- **Choose a draft model that is cheap and often right.** It must share the big model's tokens. Here a draft pass twice as slow needs 58% kept to match plain decoding, not 39%.
- **Measure how often guesses are kept on your own text.** The rate depends on the text; set the number of guesses from it.
- **Expect less gain on a busy server.** A crowd sharing the chip uses up the spare arithmetic.
## Go deeper
*Optional. This part is for readers who write Python. The code is in the `code/` folder next to this lesson. From inside that folder, `python3 show_numbers.py` prints every number below, and `python3 -B -m pytest -q -p no:cacheprovider` runs the tests.*
### The round in code
In a real system the big model's k + 1 choices come from one pass; in this toy each choice is a function call, and a round counts as one big pass. This is the real function with its comments cut:
```python
def speculative_greedy(prompt, count, k, draft=small_choice, target=big_choice):
text, rounds = list(prompt), []
while len(text) - len(prompt) < count:
guesses = []
for _ in range(k):
guesses.append(draft(text + guesses))
own = [target(text + guesses[:i]) for i in range(k + 1)]
kept = 0
while kept < k and guesses[kept] == own[kept]:
kept += 1
new = guesses[:kept] + [own[kept]]
rounds.append(Round(guesses, own, kept, new))
text += new
return text[len(prompt):len(prompt) + count], rounds
```
`own` is the big model's choice at all k + 1 places: after the text, after one guess, and so on to after all k. `kept` counts matches from the start. The line `new = guesses[:kept] + [own[kept]]` is the whole rule: the kept guesses, then the big model's token, which is the free extra one when `kept` equals k.
### The toy pair
Both toy models are word tables built from one 41-token sentence of tea-making steps, treated as a ring so the last words lead back to the first. The big toy looks back two words and picks the word that most often followed them. The small toy looks back one. They pick the same word at 28 of the 41 places, 68.3%.
### Proof that the text is unchanged
`test_speculative_text_equals_the_big_models_own_text` runs plain greedy decoding with the big toy for 50 words from each of the 41 starts, then speculative decoding with the pair for k of 1, 2, 3, 4, 6 and 8, and asserts the same 50 words. It checks each round's shape, and that a run stopped early ended at a real disagreement. A draft that is always wrong must still give the same text, with one word per round. Dropping the big model's own word, or keeping a guess past a mismatch, changes the text and fails it.
### The rule for sampled text
Let p be the big model's chance for a token and q the draft model's. Leviathan, Kalman and Matias use these letters; Chen and colleagues swap them. The rule: draw a guess x from q and keep it with probability min(1, p(x) / q(x)). After a rejection, draw instead from max(0, p(x) − q(x)), scaled to add up to 1.
```python
def keep_chance(p_x, q_x):
return min(Fraction(1), p_x / q_x) if q_x else Fraction(1)
def residual(p, q):
left = {x: max(Fraction(0), p[x] - q[x]) for x in p}
total = sum(left.values())
return {x: left[x] / total for x in left}
```
Take three tokens with p of 1/2, 3/10 and 1/5 for A, B and C, and q of 1/5, 3/10 and 1/2. A is drawn with chance 1/5 and kept for sure, since p is above q. B is drawn with 3/10 and kept for sure. C is drawn with 1/2 and kept with chance (1/5) / (1/2) = 2/5, so 1/5 gets through. In all 7/10 of guesses are kept. The other 3/10 are rejected, and the leftover is 3/10 for A and nothing for B and C, so every rejection becomes A. In the table, Kept is the chance a token is guessed and kept, and Redrawn the chance it is written after a rejection.
| Token | Kept | Redrawn | Total |
|---|---|---|---|
| A | 1/5 | 3/10 | 1/2 |
| B | 3/10 | 0 | 3/10 |
| C | 1/5 | 0 | 1/5 |
The totals are p exactly. `test_sampling_rule_gives_the_big_models_odds_exactly` asserts that in exact fractions for this example and for 30 invented pairs of 2 to 6 tokens.
### Tokens per big pass
If each guess is kept with chance a, independently, the token at place j is reached when the first j guesses were all kept, a chance of a^j. So the expected tokens per big pass is 1 + a + a² + … + a^k, which is (1 − a^(k+1)) / (1 − a), or k + 1 when a is 1. Leviathan and colleagues call the independence a simplifying assumption. `simulate_tokens_per_pass` draws 100,000 seeded rounds, and a test holds its average to the formula within 1.5% for six pairs of a and k. At k of 4, a of 0.3, 0.6, 0.8 and 0.9 give 1.43, 2.31, 3.36 and 4.10 tokens per pass.
The toy pair tests the assumption. It keeps a guess 68.3% of the time; the formula at that chance is compared with the toy's measured words per big pass over a start at every place:
| Guesses | Measured | Formula |
|---|---|---|
| 1 | 1.71 | 1.68 |
| 2 | 2.41 | 2.15 |
| 4 | 2.92 | 2.69 |
| 8 | 3.14 | 3.05 |
The measured value is higher at every k, so the toy's guesses are not independent chances. For another pair the gap will differ.
### Time, with a worked example
The draft model is Llama 3.2 1B, which has the big model's vocabulary of 128,256 tokens, so the big model can check its tokens one for one. The code counts its weights from a third-party copy of its configuration: 16 layers, width 2,048, feed-forward width 8,192, 32 attention heads of which 8 keep keys and values, and one table shared by input and output. The count is 1,235,814,400 weights, the total listed for its files, or 2.47 GB at 2 bytes each; Meta's model card agrees on 1.23 billion parameters and shared embeddings. A separate output table would give 1.50 billion weights and a draft pass 21% too slow; a test guards that. By [lesson 23](https://spicyshark.co/learn/why-ai-waits-before-the-first-word/)'s model a draft pass takes 2.47 GB over 2,039 GB a second: 1.212 ms, 15.4% of the big model's 7.877 ms.
A round costs k draft passes plus one big pass over k + 1 tokens. The speed-up is the tokens per round times the plain time, over the round time.
```python
def round_seconds(k, draft_seconds=None, users=1):
each = draft_pass(users).seconds if draft_seconds is None else draft_seconds
return k * each + big.prefill(users * (k + 1)).seconds
def speedup(a, k, draft_seconds=None, users=1):
return expected_tokens(a, k) * plain_seconds(users) / round_seconds(k, draft_seconds, users)
```
Here `big.prefill` is [lesson 23](https://spicyshark.co/learn/why-ai-waits-before-the-first-word/)'s pass over n tokens; a test asserts that it takes exactly the time of one token for every n from 1 to 153. With c the draft pass as a share of a big pass, 0.154, the speed-up is (1 − a^(k+1)) / ((1 − a)(1 + kc)), which is Leviathan and colleagues' Theorem 3.8. At the opening setting:
| Step | Value |
|---|---|
| Four draft passes | 4.848 ms |
| Big pass, 5 tokens | 7.877 ms |
| One round | 12.725 ms |
| Tokens per round | 3.36 |
| Time per token | 3.79 ms |
| Speed-up | 2.08 |
### Break-even and the best number of guesses
`break_even` finds by bisection the lowest keep chance with a speed-up of at least 1: 15.4% for one guess, 24.7% for two, 38.6% for four and 55.4% for eight. More guesses cost more draft passes, so they need more luck to pay. `best_k` tries every k from 1 to 32. At a of 0.6 the best is 2 guesses, 1.50 times as fast; at 0.8 it is 5, 2.08 times; at 0.9 it is 8, 2.75 times; at 0.95 it is 12, 3.42 times. At 0.6 the curve falls below 1 at 10 guesses.
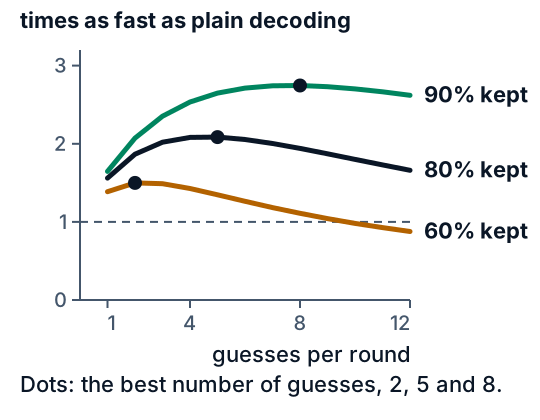
*Figure 4. Best-case speed-up against guesses per round. Dots mark the best number for each chance.*
### Many users at once
With B users in one step, the plain step reads B tokens and the check reads B(k + 1), so the check stops being free sooner (lesson 24's per-user cache reads are left out here too). `users_when_checking_stops_being_free` finds the first B with B(k + 1) at or above 154: 52 users at k of 2, 31 at 4, 22 at 6 (22 × 7 is exactly 154, and a tie counts as arithmetic) and 18 at 8. At 80% kept and four guesses the speed-up is 2.08 up to 30 users, 2.02 at 32 and 1.24 at 64, and falls below 1 at 85. From 154 users every pass is limited by arithmetic and it stays at 0.60: a round does 5.6 times a plain step's arithmetic for 3.36 tokens. This is the toy's time model, not a measurement of any server; [lesson 24](https://spicyshark.co/learn/how-an-ai-server-answers-many-people-at-once/) covers how a server shares a step.
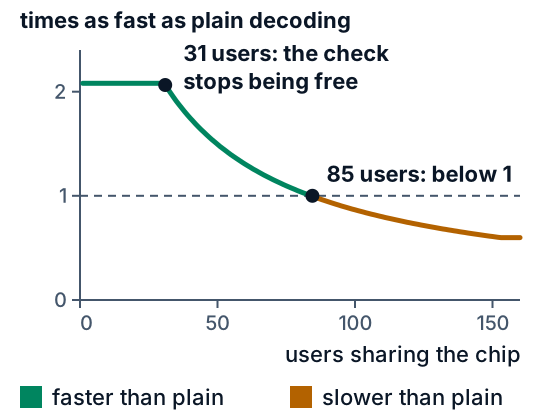
*Figure 5. Best-case speed-up against users sharing the chip. The dashed line is plain decoding.*
### What the model leaves out
The time model counts weights only, like [lesson 23](https://spicyshark.co/learn/why-ai-waits-before-the-first-word/)'s short formulas. It leaves out the attention cache of both models, the memory the draft model takes on the same chip, and the time software spends moving between the two models. Real chips fall short of their peak, and a small model falls shorter. The widget's More settings slow the draft pass: at 2.4 ms, twice the 1.2 ms, the speed-up at 80% kept and four guesses is 1.52, not 2.08, and break-even rises to 58%; at 7.9 ms, as slow as the big model, it is 0.67. Other ways to guess exist: Medusa (Cai and colleagues, 2024) adds extra output heads to the big model so that no second model is needed, and its abstract says it builds and checks several candidate continuations at once. This lesson does not model it.
### Proof it works
`test_speculative_sim.py` pins the numbers above: [lesson 23](https://spicyshark.co/learn/why-ai-waits-before-the-first-word/)'s constants and the 153/154 flip, the draft model's weight count, the text identity, the sampling rule in exact fractions, the formula against the simulation, and the time figures. `test_widget.py` runs the widget's JavaScript in Node against the Python on a grid of settings with the same seeded random numbers, and drives the page through a small stand-in for the browser. The 32 tests run in under a second.
### Where this is used in practice
Two papers describe the method, and both were read for this lesson on 2026-10-19. Leviathan, Kalman and Matias (2023) describe a smaller model proposing tokens that the large model checks in parallel, with identical outputs, and report a 2X-3X acceleration on T5-XXL against the standard T5X implementation. Chen and colleagues (2023) describe speculative sampling, with a modified rejection scheme that keeps the large model's distribution, and report a 2-2.5x speedup on the 70-billion-parameter Chinchilla in a distributed setup. Those are the authors' numbers for their own models and setups, not this toy's.
## Skills this lesson builds
- Explain how a draft model's guesses are checked in one big pass, and why the check costs about one token.
- Say why speculative decoding keeps the big model's text for greedy choice and its odds for sampling.
- Work out tokens per big pass and the speed-up from how often guesses are kept and what the draft model costs.
- Find the break-even keep rate and the best number of guesses for a setting.
- Say what a best-case model leaves out, and keep it apart from a measurement.
**Portfolio project:** pick a big and a small open model that share a tokenizer, and a library that supports guessing ahead with a draft model. On prompts from three kinds of text, such as code, a news paragraph and free chat, record how often guesses are kept, the tokens per big pass and the time per token, with greedy choice on and the output checked against plain decoding. Plot each against this lesson's formula using the measured keep rate. Publish the script, the plots and a note on where they disagree.
## Check yourself
1. A friend says the small model's guesses make the answer worse, because the small model is writing part of it. What do you tell them?
Answer
A guess is kept only where the big model would have written the same token, and where it would not, the big model's own token is used. So the text is what the big model alone would write. A poor draft model costs time, not quality.Answer
A short pass is limited by fetching the weights, which takes 7.88 ms however few tokens it reads, up to 153 of them. The chip has arithmetic to spare, so the extra four tokens ride along free.Answer
The round is 4 x 1.212 + 7.877 = 12.725 ms. A token costs 12.725 / 3.36 = 3.79 ms, against 7.877 ms for plain decoding: 2.08 times as fast.Answer
Tokens per pass are (1 − 0.6^5) / (1 − 0.6) = 2.31. The speed-up is 2.31 x 7.877 / 12.725 = 1.43 times.Answer
Each user's check reads 5 tokens, so the pass reads 31 x 5 = 155 tokens, above the 153 where the chip stops having arithmetic to spare. From there each added token costs time, and the gain shrinks. At 80% kept it is 2.08 up to 30 users and falls below 1 at 85.