---
title: "How FlashAttention avoids storing the giant score table"
description: "Online softmax finds a list's highest score and running total in one read, so FlashAttention never stores the giant score table."
topic: "AI systems"
date: 2026-10-17
chapter: "inside-the-chip"
order: 21
minutes: { plain: 5, deep: 14 }
prerequisites: ["Python and NumPy arrays", "Floating-point overflow", "Attention as a weighted average of value vectors"]
seo_title: "How does FlashAttention save memory?"
---
# How FlashAttention avoids storing the giant score table
A language model reads text as tokens: chunks of text, often a short word or part of a longer one. To read 32,768 tokens at once it uses attention, the step where each token looks back over the others and decides which ones matter. That means comparing every token with every other token, and each comparison gives one number, a score. The scores form a table of 32,768 × 32,768 entries. At 4 bytes per number (the float32 format) that table takes 4 GiB, about 4.3 billion bytes, for one attention head, one of many side-by-side copies of this step in a model. A plain program writes the whole table into the memory of a GPU (the graphics chip that runs most AI models) and reads it back several times. Online softmax (a way to turn scores into shares, like percentages that add up to 100%) is the trick that makes the table unnecessary.
## In one minute
FlashAttention, a fast and exact way to run attention on a GPU, saves memory by never storing the full table of scores. Online softmax makes that possible: it finds the two numbers softmax needs, the highest score and a running tally of how much each score counts, in one read of the list instead of two. Writing out each share would still take a second read, but attention never writes the shares: it folds each score straight into its answer as the score arrives. Picture a talent show where each act is counted against the best act so far, the champion. When a stronger champion walks on, every earlier act counts for less next to them, all by the same factor, so you multiply your tally by that one factor instead of re-judging each act.
## Explore the numbers
[Open the widget](https://spicyshark.co/learn/online-softmax/widget.html), press "Read next score" until all eight scores are in and watch every old bar shrink when a new highest arrives, then drag the slider to 80 or more to see the old way fail.
## How it works
### Scores become shares
A function called softmax turns a list of scores into positive shares that add up to 1, so the biggest score gets the biggest share. Attention uses it in its middle step, to turn scores into weights, and it is used outside attention too. Each score is first turned into a size: one more point of score makes the size about 2.7 times bigger. A score's share is its size divided by the total of all the sizes. For the scores 1, 3, 2, 5, 4 in the figures below, the score 5 gets a share of about 64%.
### Big scores break the plain way
Sizes grow fast. A computer stores each number in a fixed amount of space, and a float32 number cannot hold a size with more than 39 digits. A score of 89 already goes past that limit. The computer then records infinity, and the share comes out as NaN (not a number), the value that spoils every sum it touches. This failure is called overflow: a number too big to store.
The standard fix is to measure every size against the highest score. The biggest size then becomes exactly 1, nothing overflows, and the shares stay the same. The price is that you must know the highest score and the total before you can write any share. So this safe way reads the whole list three times: once for the highest, once for the total, once to write the shares. Each read of the whole list is called a pass.
Passes matter because a GPU has a large memory that is slow to reach and a small memory that is fast. Arithmetic is cheap, and moving data between the two memories is what takes the time. In attention the list is the giant table, so three passes means writing it out and fetching it back again and again.
### One read and a running tally
Online softmax reads each score once and keeps two numbers: the highest score so far, and a tally, the total of all sizes so far, measured against that highest score. A score that is not a new highest adds its size to the tally. A new highest score is the interesting case. Every old size was measured against the previous highest score, so each is now too big. But each is too big by the same factor, so one multiplication fixes the whole tally. The old scores are never read again.
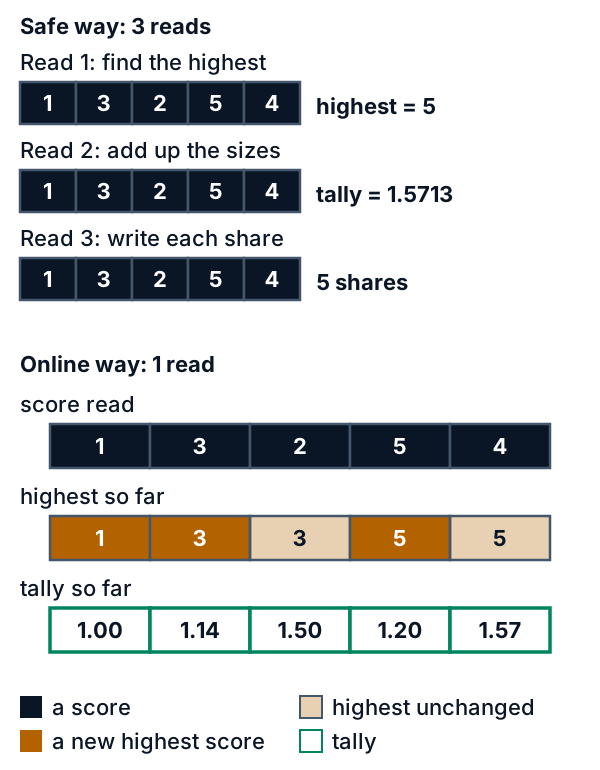
*Figure 1. The same five scores, read two ways. The safe way makes three reads. The online way makes one, and after each score it holds the highest so far and the tally. The highest changes at scores 1, 3 and 5.*
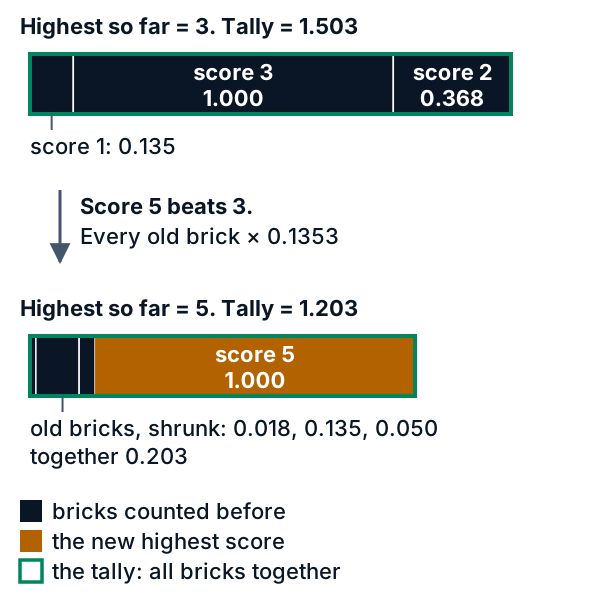
*Figure 2. A brick's length is a score's size next to the highest score so far. Top: with 3 as the highest, the scores 1, 3 and 2 have sizes 0.135, 1.000 and 0.368, a tally of 1.503. Bottom: score 5 arrives and becomes the highest. Every old brick shrinks by the same factor, 0.1353, and a new brick of 1.000 joins, so the tally is 1.203.*
After the last score, the tally equals the total the safe way finds with two reads, up to tiny rounding. Attention then blends each token's stored content (its value) into one result, and tokens with bigger shares count more. The same trick carries a running blend along and shrinks it by the same factor, so the shares are never written out. Each small block of scores is made, used once and dropped, and the giant table never exists.
## What this means when you build
- **Long inputs are cheaper than before, not free.** Without this trick the score table grows with the square of the input length: twice the tokens, four times the table. With it the table is never stored, but the arithmetic still grows with the square, and the model's saved notes on earlier tokens (the key-value cache) still grow with every token. Budget for both, and test with your longest real input.
- **You rarely write it yourself.** Serving and training libraries commonly ship FlashAttention-style code, and some let you pick it by name. In Hugging Face Transformers the setting is `attn_implementation` (`"sdpa"` or `"flash_attention_2"`), and PyTorch's `scaled_dot_product_attention` can pick a FlashAttention-style implementation on its own when the GPU and inputs allow it. Check your tool's documentation rather than assuming it is on.
- **Same answer, up to rounding.** Adding numbers in a different order changes the last digits, and that is the only difference from the slow method, so switching it on should change speed and memory, not behaviour. Rounding can occasionally tip a near-tie between two words, so a rare one-word difference in long outputs is normal; a large change points elsewhere.
- **Half precision overflows sooner.** In float16 (a 2-byte format) a size overflows at a score of about 11. Library softmax functions already subtract the highest score, so this matters if you hand-write attention in float16: subtract the highest score first. bfloat16, another 2-byte format, has about float32's range and does not.
## Go deeper
*Optional. For readers who write Python. The code is in the `code/` folder. Every number below comes from running `python3 code/online_softmax.py` or from the by-hand tables or the cited papers.*
### The naive approach, and why it fails
Softmax turns scores `x_1 ... x_n` into probabilities: `exp(x_i)` divided by the sum of all the `exp(x_j)`. The results are positive and add up to 1.
```python
def naive_softmax(x):
e = np.exp(x)
return e / e.sum()
```
This code is correct on paper and wrong on a computer. A float32 number cannot be larger than about 3.4 × 10^38, and `exp` reaches that limit early. Running `code/online_softmax.py` prints these lines:
```
float32 exp(88.7) = 3.3259769e+38 exp(88.8) = inf
float32 exp(1000) = inf
naive_softmax([1000,1001,1002]) = [nan nan nan]
```
Any score above about 88.7 overflows to `inf`. Then the code divides `inf` by `inf`, which gives `nan` ("not a number"). Float64 (8 bytes per number) has the same problem at about 709. Half precision (float16, 2 bytes) overflows far sooner: the script shows `exp(11.0)` is finite (5.987e+04) and `exp(11.1)` is `inf`.
#### The fix: subtract the maximum
Softmax gives the same result if you subtract one constant `c` from every score. The factor `exp(-c)` appears in the top and the bottom of the fraction, and it cancels:
```
exp(x_i - c) / sum_j exp(x_j - c) = exp(x_i) / sum_j exp(x_j)
```
Choose `c` equal to the largest score `m`. Now the largest exponent is `exp(0) = 1`, so nothing overflows, and the sum is at least 1, so it is never zero.
#### The cost: three passes
You must know `m` before you can compute any `exp(x_i - m)`, and the sum before you can divide any term. In code that is three loops, each one pass over the scores:
```python
def stable_softmax(row):
m = max(chunk.max() for chunk in row) # pass 1: max
total = sum(np.exp(chunk - m).sum() for chunk in row) # pass 2: sum
return np.concatenate([np.exp(c - m) / total for c in row]) # pass 3: output
```
Here `row` is a `SlowRow`, a small class in `code/online_softmax.py` that hands out the scores a block at a time and counts every score it hands out. For 1,000 scores the count after `stable_softmax` is 3,000: the statistics (`m` and the sum) need two passes, and the output needs a third.
### The idea
In the plain-words section the tally is the running sum `ℓ`, and a size is one term `exp(x - m)`.
The sum we want is `sum_j exp(x_j - m)`, where `m` is the final maximum, and we do not know it until the last score has arrived. The way around it is to keep the sum measured against the largest score **seen so far**, and to fix it when that score changes. When the max grows from `m_old` to `m_new`, every term already in the sum changes by the same factor, because
```
exp(x_j - m_new) = exp(x_j - m_old) * exp(m_old - m_new)
```
So one multiplication fixes the whole sum. Call the factor `alpha = exp(m_old - m_new)`. It is below 1 whenever the max grew. Written as a rule, with `m` the running max and `ℓ` (written `l` in code) the running sum:
```
m_new = max(m, x)
ℓ_new = ℓ * exp(m - m_new) + exp(x - m_new)
```
This update is from Milakov and Gimelshein (2018), listed at the end.
One formula covers both situations: the max moves, or it does not. If the max did not move, then `m_new = m`, `alpha` is 1, and the rule only adds a term. At the start, `m = -infinity` and `ℓ = 0`. Then `alpha = exp(-infinity) = 0`, and it multiplies an empty sum, so nothing breaks.
After every step, the state keeps one promise: `ℓ` equals the sum of `exp(x_j - m)` over the scores read so far, where `m` is the largest of those scores. When the last score has been read, `m` is the true max and `ℓ` is the true sum. We got both numbers in one pass; only floating-point rounding differs from the three-pass version.
#### From softmax to attention
Each earlier token offers a **key** vector `k_j` and a **value** vector `v_j`. The current token brings a **query** vector `q`. The score for token `j` is `s_j = q · k_j / sqrt(d)`, where `d` is the vector length. The `sqrt(d)` division keeps the typical size of a score about the same as `d` grows (for random vectors). The output is a weighted average of the values, using the softmax of the scores as weights:
```
output = sum_j softmax(s)_j * v_j
```
The textbook route makes all `n` scores first. Look at the output with the max-subtracted form instead:
```
output = ( sum_j exp(s_j - m) * v_j ) / ( sum_j exp(s_j - m) )
```
The bottom is the sum `ℓ` that we already know how to stream. The top is a vector sum whose terms carry the same factor `exp(s_j - m)`, so one `alpha` serves both. Keep a running vector `acc` and rescale it by `alpha` whenever the max grows. Like `ℓ`, `acc` keeps a promise: after each step it equals the sum of `exp(s_j - m) * v_j` over the scores read so far, where `m` is the largest of them. At the end, divide `acc` by `ℓ`.
Real GPU code runs in a **kernel**, a function that runs on the GPU, and a kernel works on a **block** of `B` keys and values at once. For each block:
```
s = K_block · q / sqrt(d) # B scores, used once
m_new = max(m, max(s))
alpha = exp(m - m_new)
p = exp(s - m_new) # B terms
ℓ = ℓ * alpha + sum(p)
acc = acc * alpha + p · V_block
m = m_new
```
After the last block, the answer is `acc / ℓ`. The state is `m`, `ℓ` and `acc`: `d + 2` numbers, no matter how long the row is.
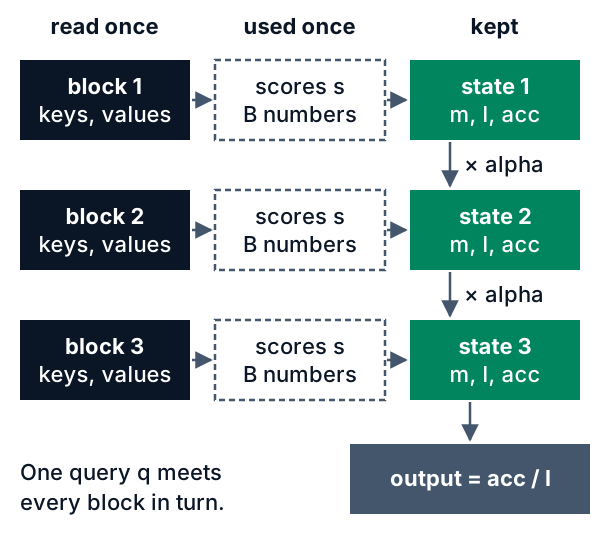
*Figure 3. Attention for one query, block by block. The scores live for one block, and the state is `d + 2` numbers.*
If two workers (separate processors, each with half of the row) stream their halves, their states can be merged. Take the larger max, rescale each side's `ℓ` and `acc` by `exp(its max - the larger max)`, and add. The test file checks this.
### A worked example by hand
Take five scores: `x = 1, 3, 2, 5, 4`. You need four constants, to five places: `exp(-1) = 0.36788`, `exp(-2) = 0.13534`, `exp(-3) = 0.04979` and `exp(-4) = 0.01832`. Compute each row from the row above and these constants only, rounding `ℓ` and `acc` to four places after each row, so you can redo every cell on a calculator. I write `=` where a result is exact and `≈` where it is rounded. The code keeps full precision, so its last digits differ a little (its last `acc` is 62.7774, the table's is 62.7776). It also prints this by-hand version.
Table 1 lists the state after each score. The "new term" column is `exp(x - m_new)`.
| step | score x | new max m | alpha = exp(m_old − m_new) | new term | running sum ℓ |
|---|---|---|---|---|---|
| 1 | 1 | 1 | 0 (empty sum) | 1.00000 | 1.0000 |
| 2 | 3 | 3 | 0.13534 | 1.00000 | 1 × 0.13534 + 1 ≈ 1.1353 |
| 3 | 2 | 3 | 1.00000 | 0.36788 | 1.1353 + 0.36788 ≈ 1.5032 |
| 4 | 5 | 5 | 0.13534 | 1.00000 | 1.5032 × 0.13534 + 1 ≈ 1.2034 |
| 5 | 4 | 5 | 1.00000 | 0.36788 | 1.2034 + 0.36788 ≈ 1.5713 |
The max grows at steps 2 and 4, so `alpha` is below 1 there. At step 4 the sum falls from 1.5032 to 1.2034, because the old terms were measured against 3 and now count against 5. Figure 4 plots the same numbers.
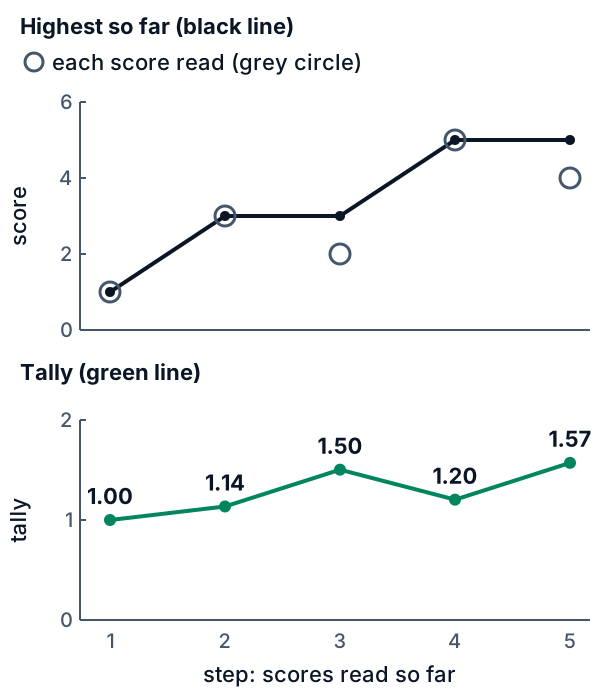
*Figure 4. The running max, `m`, only goes up. The running sum, `ℓ`, can go down, as at step 4, when a larger max forces a rescale. Grey circles are the scores read.*
Check the final sum without any streaming. With `m = 5` the five terms are `exp(-4) + exp(-2) + exp(-3) + exp(0) + exp(-1) = 0.01832 + 0.13534 + 0.04979 + 1 + 0.36788 = 1.57133 ≈ 1.5713`. It matches the last row of Table 1.
Now the probabilities. They need the final `m = 5` and `ℓ = 1.5713`, so this is the extra read that attention will avoid.
| score x | exp(x − 5) | probability = exp(x − 5) / 1.5713 |
|---|---|---|
| 1 | 0.01832 | 0.0117 |
| 3 | 0.13534 | 0.0861 |
| 2 | 0.04979 | 0.0317 |
| 5 | 1.00000 | 0.6364 |
| 4 | 0.36788 | 0.2341 |
#### Carry the values along
Give each score a scalar value (a single number): `v = 10, 20, 30, 40, 50`. A real value is a vector. One number keeps the arithmetic on paper. The new column is `acc = acc × alpha + p × v`, where `p` is the new term from Table 1.
| step | v | acc | output acc / ℓ (2 places) |
|---|---|---|---|
| 1 | 10 | 0 × 0 + 1 × 10 = 10.0000 | 10.00 |
| 2 | 20 | 10 × 0.13534 + 1 × 20 = 21.3534 | 21.3534 / 1.1353 ≈ 18.81 |
| 3 | 30 | 21.3534 × 1 + 0.36788 × 30 = 32.3898 | 32.3898 / 1.5032 ≈ 21.55 |
| 4 | 40 | 32.3898 × 0.13534 + 1 × 40 ≈ 44.3836 | 44.3836 / 1.2034 ≈ 36.88 |
| 5 | 50 | 44.3836 × 1 + 0.36788 × 50 = 62.7776 | 62.7776 / 1.5713 ≈ 39.95 |
Each output is the attention output for the scores read so far. Check step 5 against the textbook route: multiply the probabilities by the values and add, `0.0117×10 + 0.0861×20 + 0.0317×30 + 0.6364×40 + 0.2341×50 = 39.951`, which is 39.95 to two places, the same as the streamed answer.
Now use blocks of two: `(1, 3)`, `(2, 5)`, `(4)`. After block 1 the state is `m = 3`, `ℓ = 1.1353`, the same as step 2. Block 2 raises the max to 5 and gives `ℓ = 1.1353 × 0.13534 + 0.04979 + 1 ≈ 1.2034`, the same as step 4. Block size changes how often you rescale, not the answer.
### The implementation
The full file is `code/online_softmax.py`. Here is the one-pass statistics function for a row that arrives in blocks.
```python
def online_stats(row):
"""Return (m, l) in ONE pass: m = max(x), l = sum(exp(x - m))."""
m, l = -np.inf, 0.0
for chunk in row:
m_new = max(m, chunk.max())
if m_new == -np.inf: # a block that is entirely -inf adds nothing
continue
l = l * np.exp(m - m_new) + np.exp(chunk - m_new).sum()
m = m_new
return m, l
```
Attention often **masks** positions that a token may not look at, such as the tokens after it, by giving them the score `-inf`. A block is fully masked when all its scores are `-inf`. While no finite score has arrived, the `if` skips such a block, because without it `-inf - -inf` is `nan`. The attention version below has the same guard:
```python
def attention_state(q, K, V, block):
m, l = -np.inf, 0.0
acc = np.zeros(V.shape[1], dtype=V.dtype)
for i in range(0, len(K), block):
s = K[i:i + block] @ q / math.sqrt(len(q)) # scores for this block only
m_new = max(m, s.max())
if m_new == -np.inf: # fully masked so far: adds nothing
continue
alpha = np.exp(m - m_new) # 1.0 when the max did not move
p = np.exp(s - m_new)
l = l * alpha + p.sum()
acc = acc * alpha + p @ V[i:i + block] # same alpha as the sum
m = m_new
return m, l, acc
def online_attention(q, K, V, block):
_, l, acc = attention_state(q, K, V, block)
return acc / l
```
The loop body is the block recipe, line for line, plus the guard. The only new idea is the division by `l` at the end.
#### Why reading once matters
A GPU's large memory is called HBM (high-bandwidth memory) and its small, fast on-chip memory is SRAM (static random-access memory). Dao et al. (2022) argue that attention is limited by the reads and writes between these two levels, not by arithmetic. They call an algorithm that counts those reads and writes "IO-aware", where IO means input and output.
Our `SlowRow` counter shows the effect on softmax alone. For 1,000 scores:
| method | reads of the scores |
|---|---|
| safe softmax (max, sum, output) | 3,000 |
| online statistics (`m` and `ℓ` only) | 1,000 |
| online softmax with the output written | 2,000 |
Online softmax gives `m` and `ℓ` in one read. Writing each probability still needs a second read; attention avoids it by never writing probabilities.
Milakov and Gimelshein (2018) count memory accesses per element, including the write of the result: 4 for safe softmax and 3 for the online version. That is the same change (3 reads and 1 write become 2 reads and 1 write). Their benchmarks on a GPU found softmax up to 1.3 times faster, which matches the ratio 4/3 for a memory-limited kernel.
The larger gain comes with attention (this lesson gives no number for it). The textbook route writes the full score matrix to the large memory and reads it back more than once. The streaming route makes each block of scores, uses it once, and drops it. Online softmax does not reduce the arithmetic, and the rescale adds a little. It reduces memory traffic, and that is where the time goes.
### Proof it works
The tests are in `code/test_online_softmax.py`. Run them from the lesson folder with `python3 -m pytest -q code/`. Each test guards one specific failure.
| test | what it catches |
|---|---|
| naive overflows where stable and online do not | a version that forgets the max, which returns `nan` for `[1000, 1001, 1002]` in float32 |
| online stats match, one read per score | a hidden second pass, or a wrong `m` or `ℓ`, for block sizes 1 to 5,000 |
| max arrives in the last block | a missing rescale of the old sum |
| three-pass softmax reads each score three times | the baseline count (3,000 reads for 1,000 scores) drifting from the text |
| leading fully masked block, in `online_stats` | `nan` from `-inf - -inf` when the first block is all `-inf` |
| leading fully masked block, in `attention_state` | the same `nan` reaching `l` and `acc` in the attention loop |
| worked-example values | any cell of the three tables above going out of date |
| attention matches the reference for any block size | a missing rescale of `acc`, or `p` computed with the old max |
| large scores stay finite in float32 | overflow in the online path |
| merging two halves equals one pass | wrong rescaling when states are combined |
| no full row of scores is allocated | a "streaming" version that quietly builds all `n` scores |
Five deliberate bugs each make at least one test fail: dropping the rescale of `ℓ`, dropping the rescale of `acc`, computing all scores at once, computing `p` against the old max, and removing the `-inf` guard. On the demo data (seed 0) the largest difference from the reference was below 1e-15 in both runs: online softmax against `stable_softmax` over 1,000 float64 scores, and online attention against the float64 `attention_reference` (`n = 1,000`, `d = 16`, blocks of 64).
### Where this is used in practice
- **FlashAttention** (Dao et al., 2022) computes exact attention block by block, so the full `n × n` score matrix never goes to the large GPU memory. It uses the running max and running sum from this lesson, and cites Milakov and Gimelshein for the technique. For training it also recomputes scores in the backward pass instead of storing them; this lesson covers only the forward pass.
- **FlashAttention-2** (Dao, 2023) adds better work partitioning across the GPU.
- **Triton's fused attention tutorial** is a short, readable GPU kernel. (Triton is a Python-based language for GPU kernels; "fused" means the steps run together in one kernel.) Look for the line that computes `alpha` and the line that scales `acc` by it. It uses base-2 exponentials, but the idea is the same.
- **Flash-Decoding** (Dao et al., 2023) splits the keys across several workers when there is only one query to answer. It combines the partial results with the merge described under "The idea".
- **Rabe and Staats (2021)** showed attention does not need extra memory that grows with n².
- **Milakov and Gimelshein** used the online normalizer for softmax alone, and for softmax fused with top-k selection (keeping only the k largest scores).
## Skills this lesson builds
- Explain why softmax overflows, and show the failing input (`[1000, 1001, 1002]` in float32) and the subtract-the-max fix.
- Derive the running-sum update and its rescale factor, and extend it to a vector-valued running total.
- Implement block-wise attention in NumPy and test it against a plain reference for many block sizes, including fully masked blocks.
- Merge the partial results of two halves of a sequence into one answer.
- Reason about memory traffic: count reads and writes, not only arithmetic.
**Portfolio project:** write a small NumPy attention that streams keys and values in blocks. Add randomized tests against the plain formula (several block sizes, masks, float32 and float64) and a chart of the largest difference. Add a read counter, and say in the write-up that it shows memory traffic, not measured speed.
## Check yourself
1. Why does the plain way of computing shares fail on large scores, and what does the safe way do about it?
Answer
Each score becomes a size, and sizes grow fast. In float32 a score above about 88.7 gives a size too big to store (overflow), so the shares come out as "not a number". The safe way measures every size against the highest score, so the biggest size is exactly 1 and nothing overflows. The price is three reads of the list.
Answer
Every old size was measured against the old, lower highest score, so each is too big by the same factor. Multiplying the tally by that one factor fixes all of them at once, and then the new score's size (exactly 1 next to itself) is added. The old scores are never read again. In the example the tally goes from 1.50 to 1.20 at the fourth score.
Answer
Increasing order: every score after the first is a new max, so `alpha` is below 1 on steps 2, 3 and 4. In decreasing order the max never grows after step 1, so `alpha` is 1 every time. The final `m`, `ℓ` and output are the same, up to rounding.
Answer
Each term in `acc` is `exp(s_j - m) * v_j`. Each term in `ℓ` is `exp(s_j - m)`. Both carry the factor `exp(-m)`, so a change of `m` changes both by the same ratio. Rescale only `ℓ`, and `acc / ℓ` would mix numbers measured against different maxima.
Answer
Let `m = max(m_a, m_b)`. Then `ℓ = ℓ_a * exp(m_a - m) + ℓ_b * exp(m_b - m)`, and `acc` combines the same way. The output is `acc / ℓ`. This is the `merge` function in `code/online_softmax.py`.