---
title: "Why AI servers waste memory, and how paging fixes it"
description: "An AI server keeps working notes for every chat. Storing them in small equal blocks, not one big reserved stretch, lets one GPU serve far more chats."
topic: "AI systems"
date: 2026-10-17
chapter: "serving-many-chats"
order: 22
minutes: { plain: 6, deep: 14 }
prerequisites: ["Scaled dot-product attention", "Paging and page tables in operating systems", "Reading Python and NumPy"]
seo_title: "What is PagedAttention and how does vLLM save memory?"
---
# Why AI servers waste memory, and how paging fixes it
A company that runs a chatbot pays for graphics chips (GPUs), and the memory on those chips is the scarce part. Every chat needs some of it for working notes about the words so far. Kwon and colleagues (2023) measured earlier programs that run chatbots. Those programs set aside one long stretch of memory for each chat's notes. In them, only 20.4% to 38.2% of that memory held real notes (Figure 2 of their paper). The rest sat reserved and empty, or stranded in gaps too small to use. Their own program, vLLM (free software for running AI models), raised that to 96.3% by borrowing an old idea from operating systems. It handled 2 to 4 times as many requests per second, with the same delay per reply.
## In one minute
vLLM, a free program that runs AI models for many people at once, saves memory with PagedAttention: it keeps each chat's working notes in small, equal blocks handed out only when needed, not in one big stretch reserved up front. Picture two hotels: one gives each group a whole floor in case it grows, the other hands out single rooms as it grows, and fits far more groups. A chatbot writes one word at a time and keeps notes on every word so far (the KV cache). The computer running it cannot know how long a reply will be, and small blocks let it guess wrong without wasting much. Each chat keeps a short list of which blocks are its own, like a room list at the front desk.
## Explore the numbers
[Open the widget](https://spicyshark.co/learn/paged-kv-cache/widget.html). Drag the top slider down to 16 and all three chats fit the old way; drag it up to 32 and chat C is shut out. Then press "+4 tokens" on chat A and watch the new way take one small block at a time.
## How it works
### The notes pile up
A chatbot writes its reply one word at a time (more exactly, one token: a word or a piece of a word). For each new word it must look back at all the earlier ones. Redoing that from scratch every time would be slow, so the server computes notes about each earlier word once and keeps them. These notes are the KV cache ("K" and "V" stand for "key" and "value", the two kinds of note). They live in GPU memory, and they are big: for Llama 3 8B, an AI model whose design is public, they take about 130,000 bytes for each token, which is about 1 gigabyte for a conversation of 8,192 tokens. (Exactly 128 KiB and 1 GiB, where a KiB is 1,024 bytes and a GiB is 1,024 x 1,024 KiB.)
### Reserving a stretch wastes room
The server cannot know how long a reply will be. The simplest plan reserves one long stretch of memory per chat, big enough for the longest reply allowed, so the notes can grow in place. Two kinds of waste follow. Inside a stretch, whatever the chat has not used yet sits empty, and a chat that stops early leaves most of it unused. Between stretches, finished chats leave holes. A new chat needs one long stretch, and the free memory may be there in total but split into pieces too short for it.
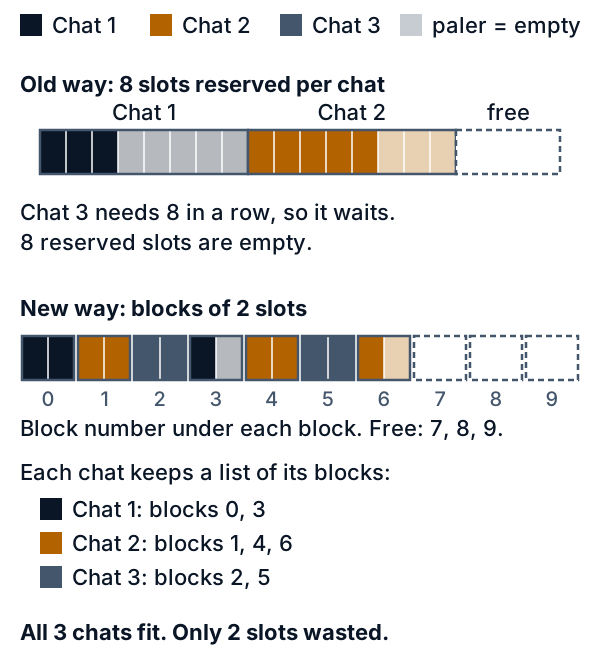
*Figure 1. A toy pool of 20 slots (one slot holds the notes for one token). Colour shows which chat owns a slot, and a paler shade is a slot that is reserved but empty. Old way: chats 1 and 2 reserve 8 slots each and use 3 and 5, so only 4 slots stay free and chat 3 must wait. Chat 3 holds 4 tokens so far and would reserve 8 the old way. New way: blocks of 2 slots, with chat 1 in blocks 0 and 3, chat 2 in 1, 4 and 6, and chat 3 in 2 and 5.*
### Small blocks fix both
The fix comes from operating systems, which met the same problem decades ago. Cut the memory into many equal small blocks. Hand a block to a chat only when it needs one. Let each chat keep a list of its own blocks (the block table), which need not sit side by side. Every block is the same size, so any free block suits any chat, and the holes problem goes away. The only waste left is the unfilled end of each chat's last block, always less than one block. In the bottom half of Figure 1, all three chats fit and only 2 slots are empty. When a chat finishes, its blocks go straight back to the unused pile.
### Sharing is cheap
Many chats begin with the same text, such as the instructions an app adds every time. With block lists, two chats can point at the same block instead of each keeping a copy. If one chat must add notes to a shared block that still has room, it first makes a private copy and writes there, and the other chat keeps the original. This is called copy-on-write.
### What it costs
Each lookup goes through the list, and the part of the model that looks back at the notes must read block by block. Block size is a trade: small blocks waste less per chat but make longer lists. The vLLM authors chose blocks of 16 slots.
## What this means when you build
- **Memory, not only speed, limits how many users one GPU serves.** Each live chat holds notes for every token so far. With Llama 3 8B, ten chats of 8,192 tokens hold 10 GiB of notes before anything else is counted.
- **Do the arithmetic before you rent a GPU.** The notes cost a fixed number of bytes per token. From the model's config file, multiply 2 (one key, one value), `num_hidden_layers`, `num_key_value_heads` (not `num_attention_heads`), the head size (`hidden_size` divided by `num_attention_heads`) and the bytes per number (2 for 16-bit). Llama 3 8B: 2 x 32 x 8 x 128 x 2 = 131,072 bytes. Multiply by tokens and chats, add the model itself (8 billion numbers at 2 bytes is about 16 GB), and compare with the GPU's memory.
- **Use a server that already pages.** If you host an open model yourself, choose software that manages its cache in blocks. vLLM is open source, and SGLang (page size is a setting) and TensorRT-LLM document paged caches too. Writing your own allocator is a project for learning, not for shipping. If you call a hosted model instead, the provider handles the cache.
- **Put the text that never changes at the start of the prompt.** Servers that share cached blocks between requests, such as vLLM with its automatic prefix caching option, can only reuse a start that is identical. Hosted APIs that offer prompt caching also reuse only an identical start. Put your fixed instructions first and the changing part last.
- **Expect waiting when the blocks run out.** With no free block, a busy server makes new chats wait and may pause a running chat and redo its notes later (vLLM calls this preemption). Both show up as delay, not as a wrong answer. In vLLM, raising `gpu_memory_utilization` or lowering `max_num_seqs` gives the cache more room.
## Go deeper
*Optional. For readers who write Python. The code is in the `code/` folder. Every number below was printed by `python3 show_numbers.py`, worked out by hand in the quiz, or comes from a cited source.*
Servers call a chat a request; this section uses that word.
### The naive approach: one big buffer per request
#### What the cache holds
Each pass that produces one new token is a decode step. At each step the newest token makes a query, compared with the key of every earlier token, and the resulting weights mix their values. An earlier token's key and value never change, so the server computes them once and reads them back at every later step.
Without the store, step `t` must rebuild the keys and values of all `t` positions. A pair is one key and its value for one position, so over `n` steps that is 1 + 2 + ... + n pairs. With the store, each step computes one new pair.
```python
def pairs_without_cache(n_steps): # 1 + 2 + ... + n
return n_steps * (n_steps + 1) // 2
def pairs_with_cache(n_steps): # one new position per step
return n_steps
```
| Steps n | Without cache (pairs) | With cache (pairs) | Ratio |
|---|---|---|---|
| 10 | 55 | 10 | 5.5 |
| 100 | 5,050 | 100 | 50.5 |
| 1,000 | 500,500 | 1,000 | 500.5 |
The toy counts only this work and ignores the rest of the layer.
`decode_both_ways` in `code/kv_sizes.py` runs one attention head both ways, counts the pairs, and gets matching outputs.
The cache sits in GPU memory, and every decode step reads all of it, so its size sets the memory traffic of each new token.
#### How big it gets
For each token, each layer stores one key vector and one value vector for each key/value head. That gives the size per token in bytes.
```python
def kv_bytes_per_token(cfg):
return 2 * cfg.n_layers * cfg.n_kv_heads * cfg.head_dim * cfg.bytes_per_elem
```
The leading 2 is one key plus one value. Take Llama 3 8B: 32 layers, 8 key/value heads (grouped-query attention lets 32 query heads share 8 of them), head size 128, and 2 bytes per number, the size of the 16-bit formats bf16 and fp16. The layer and head counts are in Table 3 of the [Llama 3 paper](https://arxiv.org/abs/2407.21783) and in the model's `config.json`: `num_hidden_layers` is 32, `num_key_value_heads` is 8, `num_attention_heads` is 32 and `hidden_size` is 4096, so the head size is 4096 / 32 = 128. Meta's [model page](https://huggingface.co/meta-llama/Meta-Llama-3-8B) asks for a login, so read the file in a [public mirror](https://huggingface.co/NousResearch/Meta-Llama-3-8B/blob/main/config.json). The 8,192-token context is `max_position_embeddings` in that file. A MiB is 1,024 KiB, and a GiB is 1,024 MiB.
| Quantity | Value |
|---|---|
| Bytes per token | 2 x 32 x 8 x 128 x 2 = 131,072 (128 KiB) |
| A 1,000-token request | 125 MiB |
| A full 8,192-token request | 1 GiB exactly |
Older models without grouped-query attention are heavier. OPT-13B (40 layers, 40 heads of size 128, fp16) needs 819,200 bytes, or 800 KiB, per token, matching the 800 KB that Kwon et al. round it to. A full 2,048-token request needs 1.5625 GiB (they round to 1.6 GB), and at a 128K-token context one request would need 16 GiB.
#### Why one big buffer wastes it
The simplest layout reserves one contiguous run of slots per request, sized for a per-request limit (8,192 tokens for the model below), so the cache can grow in place. A slot holds the keys and values of one token. Memory is wasted two ways.
- **Internal fragmentation.** Reserved slots sit empty inside a request's own buffer. A request that stops after 200 tokens still holds the reservation for 8,192.
- **External fragmentation.** Free slots sit in gaps between buffers, too short to use. A new request needs one run in a row, and no gap is long enough even when the free total is large.
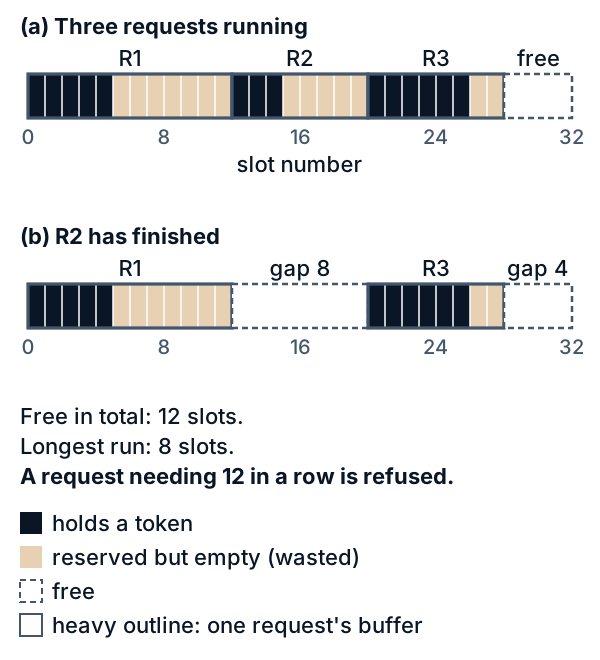
*Figure 2. A toy pool of 32 slots (a) with three requests running and (b) after R2 finishes. Black slots hold a token, pale orange slots are reserved but empty, and dashed boxes are free. R1 reserves 12 and holds 5, R2 reserves 8 and holds 3, R3 reserves 8 and holds 6.*
`ContiguousPool` in `code/contiguous.py` reproduces Figure 2. In (a), 14 reserved slots hold nothing. In (b), the 12 free slots come in runs of 8 and 4, so a request that needs 12 in a row gets `None`.
At a realistic scale, a 16 GiB cache pool for Llama 3 8B holds 131,072 token slots (16 GiB divided by 128 KiB). Reserve 8,192 slots per request and you admit 16 requests. Now suppose 500 requests arrive with lengths drawn uniformly between 100 and 2,000 tokens. This invented workload (a fixed random seed in `show_numbers.py`, every request counted at its final length) is not a measurement. The 16 admitted requests use 12.9% of the slots they reserved. The block layout of the next section, with 16 slots per block, admits 122 of the same stream, 7.6 times as many, and wastes 913 of 130,800 allocated slots (0.7%). This shows the memory effect, not a throughput benchmark.
### The idea: a block table
An operating system keeps a page table that maps a program's numbered virtual pages to physical pages, real chunks of memory that need not touch each other. Kwon et al. carry this over to keys and values: each request keeps a block table that says where its first, second and later blocks are stored.
1. At start-up, cut the cache memory into blocks of `B` token slots each. Allocate them once.
2. Keep a free list of blocks nobody uses.
3. Give each request a block table: the physical blocks that hold its tokens, in order.
4. To store a new token, write it into the request's last block if that block has a free slot. Otherwise take a block from the free list and append it to the table.
5. When a request finishes, put its blocks back on the free list.
This removes external waste, since any free block serves any request, and caps internal waste at the empty tail of a request's last block, fewer than `B` slots.
Positions start at 0. Token position `p` lives in logical block `p // B` at slot `p % B`, and the physical block is `table[p // B]`. Figure 3 shows request A with 9 tokens and `B = 4`.
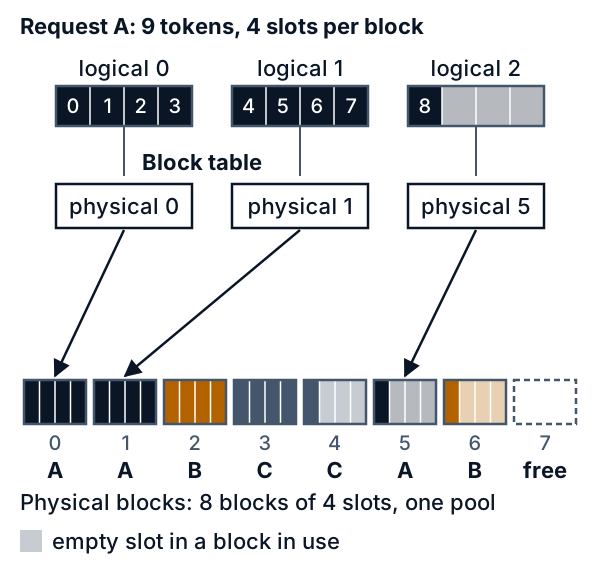
*Figure 3. Request A's block table, with `B = 4`. Token 8 sits in logical block 8 // 4 = 2, which the table sends to physical block 5. Black is A, orange is B, dark grey is C, and a paler shade is an empty slot.*
The price is one extra lookup per block, and an attention routine that reads block by block. Kwon et al. chose 16 tokens as their default block size.
### A hand-worked example
Use `B = 4` and a pool of 8 blocks (32 slots). The free list starts as 0 to 7. New blocks come from the front, and freed blocks join the back. A prompt is the text a request starts with. A request needs a new block exactly when its token count is a multiple of 4, including 0. "Wasted" is allocated slots minus stored tokens.
| Step | Event | Tokens (A, B, C) | Block tables | Free list | Wasted slots |
|---|---|---|---|---|---|
| 0 | Start | none | none | 0 1 2 3 4 5 6 7 | 0 |
| 1 | A arrives with a 6-token prompt | 6, -, - | A: [0, 1] | 2 3 4 5 6 7 | 2 |
| 2 | B arrives with 3 tokens | 6, 3, - | A: [0, 1]; B: [2] | 3 4 5 6 7 | 3 |
| 3 | C arrives with 5 tokens | 6, 3, 5 | A: [0, 1]; B: [2]; C: [3, 4] | 5 6 7 | 6 |
| 4 | A generates 2 tokens | 8, 3, 5 | unchanged | 5 6 7 | 4 |
| 5 | A generates 1 token | 9, 3, 5 | A: [0, 1, 5]; B: [2]; C: [3, 4] | 6 7 | 7 |
| 6 | B generates 2 tokens | 9, 5, 5 | A: [0, 1, 5]; B: [2, 6]; C: [3, 4] | 7 | 9 |
| 7 | B finishes | 9, -, 5 | A: [0, 1, 5]; C: [3, 4] | 7 2 6 | 6 |
| 8 | C generates 4 tokens | 9, -, 9 | A: [0, 1, 5]; C: [3, 4, 7] | 2 6 | 6 |
- **Step 1.** Tokens 0 to 3 fill block 0. Tokens 4 and 5 take block 1 and leave 2 slots empty.
- **Step 4.** Positions 6 and 7 fit in block 1's empty slots, so the free list does not change.
- **Step 5.** A has 8 tokens, a multiple of 4, so token 8 takes block 5, and A's table becomes `[0, 1, 5]`.
- **Step 6.** B's token 3 fills block 2. Its token 4 needs a new block and takes 6, leaving 7 as the only free block.
- **Step 7.** B finishes. Blocks 2 and 6 join the back of the free list, which reads 7, 2, 6. Nothing is copied or cleared. Attention reads only the slots a request's length marks as valid, so stale data in a free block is harmless.
- **Step 8.** Three of C's four new tokens fit in block 4. The fourth takes block 7 from the front, not 2.
Figure 4 shows steps 6 and 7.
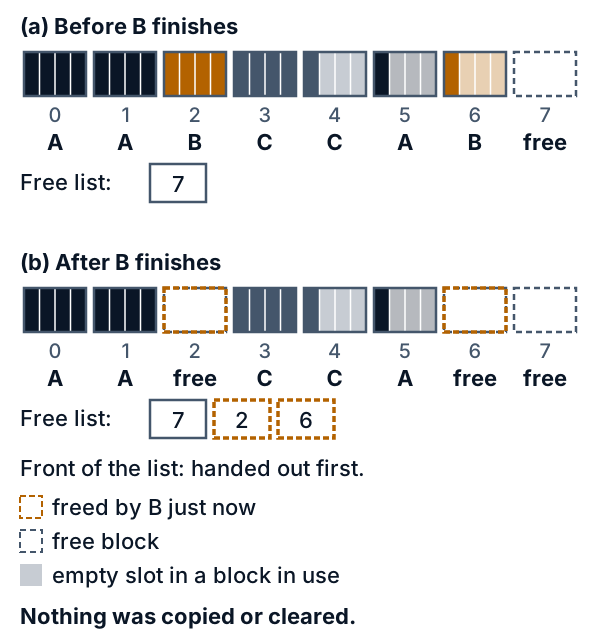
*Figure 4. The free list (a) before and (b) after B finishes. The letter under each block is its owner, and a paler shade is an empty slot. Dashed orange boxes are the blocks B freed, which join the back of the list.*
The wasted column never exceeds 9 slots; `show_numbers.py` prints it, but no test pins it. The [widget](https://spicyshark.co/learn/paged-kv-cache/widget.html) lets you replay this on a 64-slot pool, with live counts for both layouts.
### The real implementation
The full file is `code/paged_kv.py`. It handles one attention head, so the logic stays visible.
The manager owns the pool, the free list, one table per request, and a reference count per block (used when blocks are shared).
```python
class BlockManager:
def __init__(self, num_blocks, block_size, head_dim=1):
self.block_size = block_size
self.k_pool = np.zeros((num_blocks, block_size, head_dim))
self.v_pool = np.zeros((num_blocks, block_size, head_dim))
self.free_list = deque(range(num_blocks)) # take from the left, give back on the right
self.ref_count = [0] * num_blocks # how many block tables point at each block
self.tables = {} # request id -> physical block ids, in logical order
self.lengths = {} # request id -> tokens stored
```
Appending a token is the heart of it.
```python
def append(self, rid, k, v):
table, n = self.tables[rid], self.lengths[rid]
offset = n % self.block_size
last_is_full = offset == 0 # also true when the table is empty
last_is_shared = not last_is_full and self.ref_count[table[-1]] > 1
if (last_is_full or last_is_shared) and not self.free_list:
raise OutOfBlocks(rid) # nothing has changed yet
if last_is_full:
table.append(self._take_block())
elif last_is_shared: # copy-on-write: give this request its own copy
old, new = table[-1], self._take_block()
self.k_pool[new], self.v_pool[new] = self.k_pool[old], self.v_pool[old]
self.ref_count[old] -= 1
table[-1] = new
self.k_pool[table[-1], offset] = k
self.v_pool[table[-1], offset] = v
self.lengths[rid] = n + 1
```
The check for a missing block comes first: if the pool is empty, the call raises `OutOfBlocks` and changes nothing. Finishing returns a block only once no table points at it.
```python
def free(self, rid):
for block in self.tables.pop(rid):
self.ref_count[block] -= 1
if self.ref_count[block] == 0:
self.free_list.append(block)
del self.lengths[rid]
```
#### Reading through the table
Attention needs one score per earlier token. The code walks the block table: for logical block `j` it reads the first `valid` slots of physical block `table[j]`, and `valid` is less than `B` in a partly full last block.
```python
def paged_attention(q, mgr, rid):
n, size, table = mgr.lengths[rid], mgr.block_size, mgr.tables[rid]
scores = []
for j, block in enumerate(table):
valid = min(size, n - j * size) # the last block may be partly filled
scores.append(mgr.k_pool[block, :valid] @ q)
scores = np.concatenate(scores) / np.sqrt(len(q))
weights = np.exp(scores - scores.max())
weights /= weights.sum()
out = np.zeros_like(q, dtype=float)
for j, block in enumerate(table):
valid = min(size, n - j * size)
out += weights[j * size : j * size + valid] @ mgr.v_pool[block, :valid]
return out
```
The math is ordinary attention; only the addressing changes. Production systems do the same lookup inside a GPU kernel, a function that runs on the GPU.
#### Sharing a prefix with copy-on-write
Requests that start with the same text, such as a system prompt, have identical keys and values for it, so two block tables can name the same physical block. The rule: many requests may read a block, but one may write only into a block it owns alone. A reference count tracks the owners. Forking copies the parent's table and adds one to each named block's count, so no key or value moves. A request that must write into a shared block with room first copies it (copy-on-write); a full shared block is never written. Figure 5 shows a fork and the first writes.
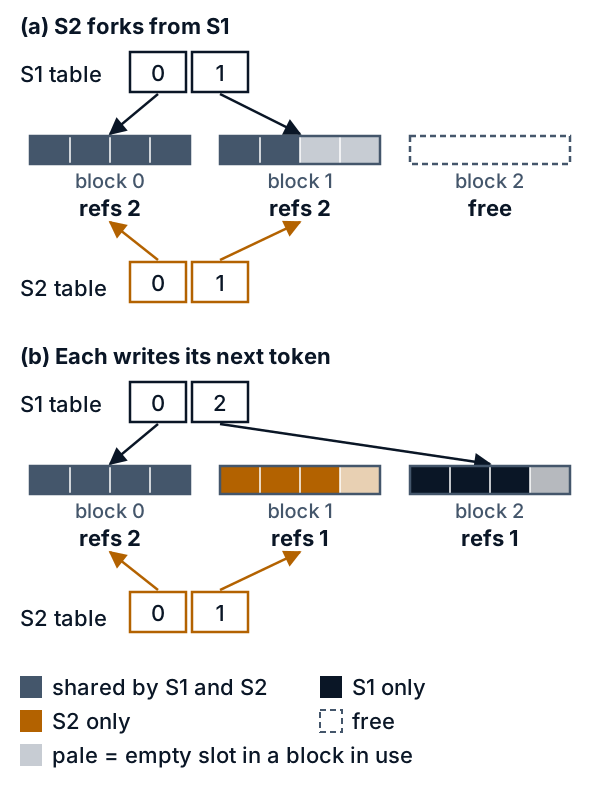
*Figure 5. Copy-on-write after a fork, with `B = 4`. Dark grey is shared by both requests, black is S1 only, orange is S2 only, and dashed is free. "refs" is the reference count, and a paler shade is an empty slot.*
Here is the run from `prefix_sharing_example` with `B = 4`, a pool of 6 blocks, and a 6-token prompt.
| Step | Block tables | References (blocks 0, 1, 2) | Free list |
|---|---|---|---|
| S1 holds the prompt | S1: [0, 1] | 1, 1, 0 | 2 3 4 5 |
| S2 forks from S1 | S1: [0, 1]; S2: [0, 1] | 2, 2, 0 | 2 3 4 5 |
| S1 writes token 6 | S1: [0, 2]; S2: [0, 1] | 2, 1, 1 | 3 4 5 |
| S2 writes token 6 | S1: [0, 2]; S2: [0, 1] | 2, 1, 1 | 3 4 5 |
The fork allocated no block. S1 wrote first: block 1 was shared and had room, so S1 copied it into block 2 and wrote token 6 there. S2 then owned block 1 alone and wrote in place. Block 0 stays shared, one block instead of two.
### Proof it works
The claim to test: scattered blocks give the same answer as one flat array. The test grows two requests in turn, so at block sizes 1 and 4 their blocks alternate in the pool, and it runs at block sizes 1, 4 and 16.
```python
@pytest.mark.parametrize("block_size", [1, 4, 16])
def test_reading_through_the_table_equals_reading_one_array(block_size):
rng = np.random.default_rng(block_size)
mgr = BlockManager(num_blocks=64, block_size=block_size, head_dim=4)
for rid in ("x", "y"):
mgr.add_request(rid)
for i in range(13):
for rid, n in (("x", 13), ("y", 7)):
if i < n:
mgr.append(rid, rng.standard_normal(4), rng.standard_normal(4))
q = rng.standard_normal(4)
for rid in ("x", "y"):
keys, values = mgr.gather(rid)
assert np.allclose(paged_attention(q, mgr, rid), attention_contiguous(q, keys, values))
```
It fails if the code maps a position to the wrong block or slot, forgets that the last block is partly full, or reads a stale slot. A randomized test runs 400 mixed operations (add, append, fork, free) for each of five seeds and checks after each that no block is lost, double-booked or listed twice, every reference count matches the tables, and every request reads back what it wrote. One test checks that a copy-on-write append that cannot get a block changes nothing. Two more pin the output to literals: the two tables above and the capacity figures (16 and 122 requests, 913 wasted slots, 12.9% used). The wasted column is not pinned by a test; `show_numbers.py` prints it.
Run everything from the `code/` folder:
```
python3 -m pytest -q .
```
The last line begins `15 passed`. The tests run NumPy on a CPU. They show the logic is right, not that it is fast.
### Where it is used
- **vLLM and the paper behind it.** Kwon et al. introduced PagedAttention and the open-source vLLM server at SOSP 2023. They report 2 to 4 times the throughput (requests served per second) of FasterTransformer and Orca, two earlier systems, at the same latency (time to answer one request). Its automatic prefix caching finds shared blocks across separate requests by hashing each block's tokens together with the tokens before it, and caches full blocks only.
- **SGLang.** RadixAttention keeps cached prefixes in a radix tree, a close relative of the prefix sharing above.
- **TensorRT-LLM.** NVIDIA's inference library documents a contiguous and a paged KV cache, with block sizes of 8 to 128 tokens for the paged one.
## Skills this lesson builds
- Compute the KV-cache size of a model from its published config (layers, key/value heads, head size, number format) and compare it with GPU memory.
- Explain internal and external fragmentation, and why fixed-size blocks remove one and cap the other.
- Write a block allocator with a free list and per-request block tables, and test that no block is lost or double-booked.
- Implement copy-on-write with reference counts, and show when a copy happens and when it does not.
- Check an optimized read path against a plain reference (here, paged attention against one flat array).
**Portfolio project:** build a small block manager in Python with a randomized test of mixed operations. Chart how many requests it admits for block sizes 1 to 16, against a contiguous baseline, on an invented length distribution that you state. Label the result as a memory effect, not a speed benchmark.
## Check yourself
1. In the old way, every chat reserves a long stretch of memory. Why does memory run out even when most of that reserved space is empty, and how much can the new way waste per chat?
Answer
Reserved space belongs to its chat even while empty, so other chats cannot use it. Finished chats also leave holes too short for a new chat that needs one long stretch. With small equal blocks, a chat takes a block only when it needs one, and the only waste left is the unfilled end of its last block: always less than one block.
Answer
Both chats' block lists name the same blocks, so the notes exist once. A chat that must add notes to a shared block that still has room first copies it into a block of its own (copy-on-write) and writes there, and the other chat keeps the original.
Answer
2 x 24 x 4 x 64 x 2 = 24,576 bytes per token (24 KiB). For 2,000 tokens that is 49,152,000 bytes, about 46.9 MiB.
Answer
Five tokens need 2 blocks. D takes 2, then 6, from the front of the free list, so D's table is [2, 6] and the free list is empty. Two blocks hold 8 slots, so 3 are empty. Position 4 is in logical block 4 // 4 = 1, at slot 4 % 4 = 0, which is physical block `table[1]`, block 6.
Answer
A copy happens only when a request must write into a block that another request also uses. Block 1 was shared and had two empty slots, so the first writer needed its own copy. Block 0 was full, so nobody writes into it, and it stays shared.