---
title: "What is prompt caching, and when does it save money?"
description: "Prompt caching reuses the work done on the start of a recent request. It saves money only when the same long start returns soon, with changing text last."
topic: "AI systems"
chapter: "use-an-ai-service"
order: 8
minutes: { plain: 6, deep: 18 }
prerequisites: ["What a token is", "Division and ratios", "Reading short Python functions"]
seo_title: "What is prompt caching and when does it save money?"
date: 2026-10-19
---
# What is prompt caching, and when does it save money?
Send a chatbot a 1,200-token report and a question, mark where the report ends, then send a second question about the same report a minute later. A token is a small piece of text, often a whole word. With this lesson's example prices of $2.00 for every million tokens read normally and $0.10 for every million reused, the second request's input, the text you send, costs $0.000160 instead of $0.002508: 94% less. Put a date line at the very top of the second request instead, and it costs 25% more than with no caching at all.
## In one minute
Prompt caching means a service reuses the work it already did on the start of a recent request, so a new request that begins with exactly the same tokens costs less and gets its first word sooner. A service keeps a start only where you mark the end of the fixed part (providers call this a breakpoint) or where a request ends. A new request reuses a kept start only if it begins with all of it: one changed word before the mark loses the whole start. Think of a bookmark in a long document: change any page before it and you must read from the top again. So put fixed parts first, mark where they end, and put changing parts last. It saves money when the same long start comes back within a few minutes. Rules differ by provider; read your provider's caching page.
## Explore the numbers
[Open the widget](https://spicyshark.co/learn/what-is-prompt-caching/widget.html) and press Date at the top, then Date at the end. The match line shows how many tokens are reused, and the cost line shows the effect on the bill. Untick the mark box and press New question to see a miss. Under More settings, set Earlier request was sent to 6 minutes ago, or shorten the Pasted document, and watch the saving shrink or vanish.
## How it works
### What the server keeps
To answer, a server reads your whole prompt. While it reads, it writes notes about every token, called the attention cache; [Why does a chatbot forget?](https://spicyshark.co/learn/why-chatbots-forget/#how-much-memory-the-cache-takes) shows how big the notes grow. Normally the server drops them after the reply. With prompt caching it keeps them for a short time, so a later request that starts with the same tokens reuses the kept notes instead of reading those tokens again. That skips work, so the first word comes sooner, and providers bill the reused part at a lower price.
### A stored start is reused whole or not at all
A service stores a start only at a mark, the point where you say the fixed part ends, or where a request ends. Nothing shorter is stored.
The server compares a new request with a stored start token by token, from the first token. The tokens they share at the start are called a prefix. The request reuses the stored start only if it begins with all of it. Everything up to its end is read from storage, and everything after is read again. If the request differs anywhere before that end, the stored start gives nothing, even when most of it matches.
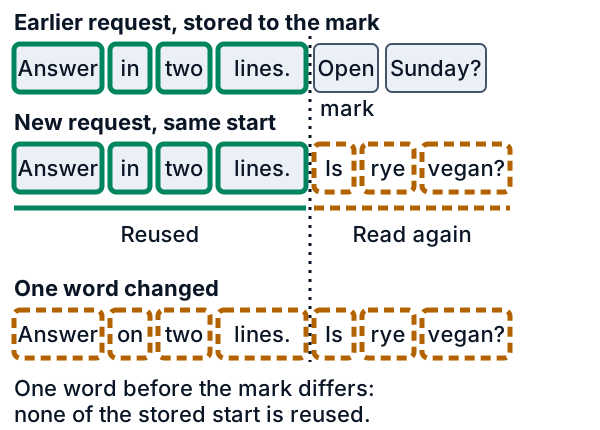
*Figure 1. A stored start ends at the mark. Green is reused, orange dashed is read again.*
### Why order matters
Say each request holds a date line, fixed instructions with a long document, and a question, and the mark sits after the document. If the date line comes first, the first token changes every time, so the stored start never matches and nothing is reused. If it comes last, the whole stored start matches. In the toy, a 1,272-token request with the date first reuses 0 tokens, and with the date last it reuses 1,236. The other 36, the question and the date, are read again.
A chat has the same shape. Each turn sends the whole chat again, so it begins with the whole previous request, stored where that request ended. In the ten-turn chat of [Why is my AI app bill higher than I expected?](https://spicyshark.co/learn/why-ai-bill-is-high/), 14,400 of the 17,300 input tokens can be reused this way.
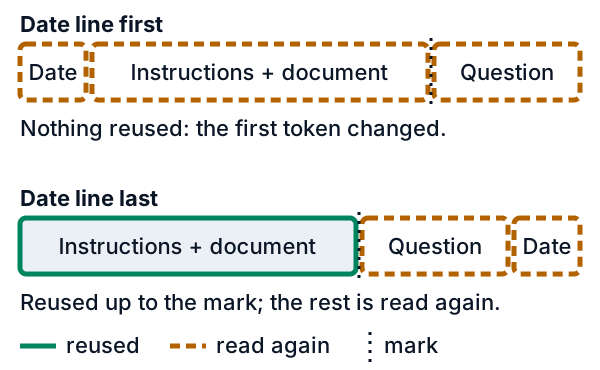
*Figure 2. The same parts in two orders, mark after the document. Green is reused, orange dashed is read again.*
### Three prices
Input is billed at one of three prices. Text read normally costs the normal price. Text the service stores for the first time often costs a little more, called a write. Text reused from storage costs far less, called a read.
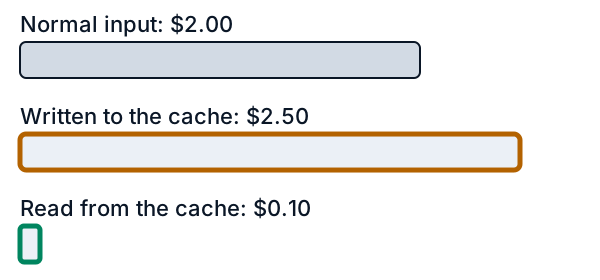
*Figure 3. The example prices used in this lesson. Providers set their own, and they change.*
The extra for a write means caching can lose. A 1,200-token start used once costs $0.003000 with caching instead of $0.002400 without. Used twice, it costs $0.003120 instead of $0.004800. With these prices, a single reuse already repays the extra.
### How long a stored start lasts
A service keeps a stored start for a set time, called its lifetime, and each use starts the clock again. In the toy's five-minute setting, a start sent every minute stays stored. After six minutes without a use it is gone, and the next request writes it again and pays the extra. Many services also skip very short starts, because each has a minimum length.
### What this toy leaves out
A busy service may drop a stored start early. Requests may reach different machines that do not share a copy. Images and tools in a prompt follow their own rules. The widget also splits text differently from a real model, and it shows input only; output is billed as usual.
## What this means when you build
- **Put fixed text first.** Instructions, examples and long documents go before anything that changes. The date, the user's name and the new question go last. In the toy, one date line first cost 25% more than no caching, because nothing matched and the write extra was still paid.
- **Mark the end of the fixed part.** With no mark, a service stores a start only where each request ends, so a new question after a shared document gets no hit. In the toy that costs 25% more than no caching.
- **Count on a return.** Caching pays when the same start comes back within its lifetime. A start used once costs more.
- **Check the minimum.** A start shorter than your provider's minimum is not stored, so a short prompt gains nothing.
- **Read the usage numbers.** Providers report how many input tokens were read from storage. If that is zero when you expected a hit, something before the mark differs.
## Go deeper
*Optional. This part is for readers who write Python. The code is in the `code/` folder next to this lesson. From inside that folder, `python3 show_numbers.py` prints every number below, and `python3 -B -m pytest -q -p no:cacheprovider` runs the tests.*
### The match in code
A prompt is a list of tokens, made with [lesson 1](https://spicyshark.co/learn/what-is-a-token/)'s tokenizer. `shared_start` counts leading tokens until the first difference, and `reuse` applies the rule of this lesson: a stored start is read whole when the new request begins with all of it, and not at all otherwise.
```python
def shared_start(old, new) -> int:
n = 0
for a, b in zip(old, new):
if a != b:
break
n += 1
return n
def reuse(stored, new) -> int:
return len(stored) if shared_start(stored, new) == len(stored) else 0
```
A rule then turns the reused count into three counts, tokens read, written and billed normally. These are the core lines of `bill_request`, comments left out. `mark` is how many leading tokens the caller asks to store, and `None` means the whole prompt, the automatic case:
```python
read = reused if reused >= rule.minimum else 0
stored = total if mark is None else min(mark, total)
written = stored - read if stored >= rule.minimum and stored > read else 0
plain = total - read - written
```
The mark decides what a later request can reuse, not only what a write costs. The cache keeps `stored` tokens, so the next question reuses the fixed part only if the mark ended it. For a 1,200-token prompt of which 1,000 tokens are fixed, `bill_request(A, 1200, 0, mark=1000)` writes 1,000 tokens and bills the other 200 normally, and a later prompt that begins with those 1,000 tokens reads them. With `mark=None` the cache keeps all 1,200, and a later prompt with a new question after the same 1,000 tokens reuses nothing.
### Four rules as parameters
Each provider rule is a few numbers: three prices per million tokens, a minimum length and a lifetime. The widget's Rule setting offers these four. The prices are in dollars per million tokens.
| Rule | Normal | Write | Read |
|---|---|---|---|
| A | 2 | 2.50 | 0.10 |
| B | 2 | 4 | 0.10 |
| C | 0.10 | 0.125 | 0.01 |
| D | 2 | 2.50 | 0.10 |
The minimum is in tokens.
| Rule | Minimum | Lifetime |
|---|---|---|
| A | 512 | 5 min |
| B | 512 | 60 min |
| C | 512 | 5 min |
| D | 1,024 | 30 min |
These are the prices for short prompts. Both providers charge more for very long ones: Haiku 5.5 above 100,000 tokens, gpt-6.1-sol above 272K.
Rules A to C come from Anthropic's pricing and caching pages, read 2026-10-19. A is Sonnet 5.5 with the default five-minute copy, B is the same model with the one-hour option, and C is Haiku 5.5 with the five-minute copy. The caching page gives 512 tokens as the minimum for both models and says a shorter prompt is processed without caching and without an error. A copy lives five minutes, renewed at no extra cost on each use. The page says a write happens only at a breakpoint: marking a block with `cache_control` writes one entry, "a hash of the prefix ending at that block", and no earlier position gets one. It then says "Cache hits require 100% identical prompt segments, including all text and images up to and including the block marked with cache control." That is the whole-start rule of this lesson. In its automatic mode the breakpoint moves to the last cacheable block of each request, which is the toy's unmarked case. The order is tools, then system prompt, then messages, and different organizations never share caches. A request may carry up to four breakpoints, and the page says the system looks back at most 20 blocks from each. Each response reports the tokens read and written.
Rule D comes from OpenAI's pricing page, the gpt-6.1-sol row, and its caching guide, read 2026-10-19. Caching is on by default, the minimum is 1,024 tokens, and "Cache reuse requires the entire rendered prefix to match." For GPT-5.6 and later, the guide's table says a copy lasts at least 30 minutes after its latest write or reuse. It lists a write at "1.25× the uncached input-token rate" and a read at "0.1× uncached input (0.05× for GPT-6.1 Sol)". For the gpt-6.1-sol row that is $2.50 to write and $0.10 to read against $2.00 for input, the same as the pricing page. The guide also describes the toy's unmarked case: when a static message is followed by a changing one, the longer cached prefix does not match, and the remedy is "an explicit breakpoint after the static content". Its example uses explicit-only mode "to avoid writing the dynamic content to cache", which is how the toy's marked case works; in implicit mode OpenAI "places a breakpoint at the end of the latest eligible message", so the dynamic content would be written too. Its own lookup tries several boundaries, among them "the first 2 and latest 50 explicit breakpoints, the implicit breakpoint, up to 20 earlier eligible message endings". It also warns that a request reuses a copy only if it reaches a machine holding a matching, unexpired entry, and it reports reuse in a `cached_tokens` field.
### The break-even
Take a start of n tokens, with a normal price p, a write price w and a read price h per token. Used again r times, it costs:
```text
without caching (1 + r) n p
with caching n w + r n h
pays off when r >= (w - p) / (p - h)
```
That gives 0.26 reads for rule A, 1.05 for B, 0.28 for C and 0.26 for D. Reads come whole, so the answer is 1, 2, 1 and 1. Anthropic's pricing page says the same: caching pays off after one read for the five-minute copy and after two for the one-hour copy. For a 1,200-token start on rule A, the total input cost after the number of requests sent in the first column is:
| Sent | Cached | Uncached |
|---|---|---|
| 1 | $0.003000 | $0.002400 |
| 2 | $0.003120 | $0.004800 |
| 3 | $0.003240 | $0.007200 |
| 5 | $0.003480 | $0.012000 |
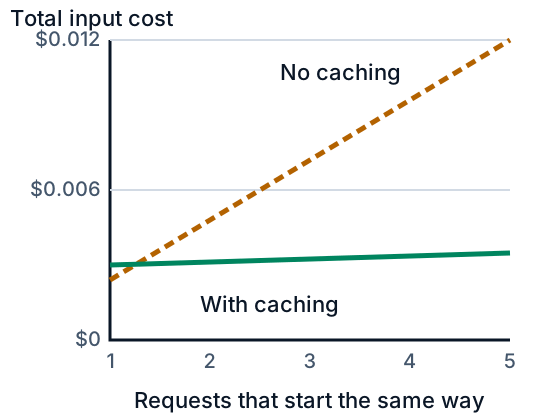
*Figure 4. Cost of one 1,200-token start used again and again, rule A. Orange dashed is no caching, green is caching.*
### A ten-turn chat
[Why is my AI app bill higher than I expected?](https://spicyshark.co/learn/why-ai-bill-is-high/) builds a chat of 10 turns with a 500-token system prompt, 60-token messages and 200-token replies, and each turn sends the whole chat again. The prompts hold 560, 820, and so on up to 2,900 tokens, 17,300 in all. Without caching the input costs $0.0346 and the output $0.02, so $0.0546.
With rule A, no mark and one turn a minute, each request is stored where it ends, so turn 1 writes its 560 tokens. Every later turn reads the whole previous prompt and writes only the 260 new tokens. That reads 14,400 tokens and writes 2,900. The prompts hold 560 + 260k tokens for k from 0 to 9, so the reads are the first nine prompts, 14,400, and the writes are 560 plus nine times 260, 2,900. The input is 14,400 x $0.10 + 2,900 x $2.50 per million: $0.00144 + $0.00725 = $0.00869, 75% less. The total, output included, is $0.02869: 47% less, because output is billed as usual.
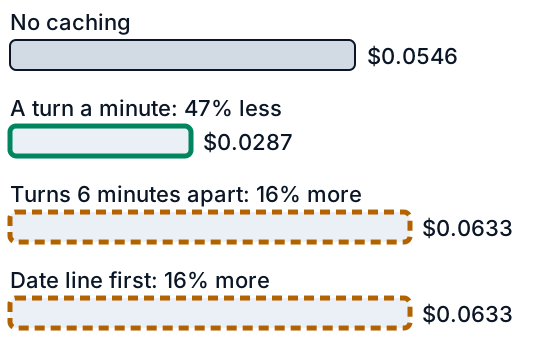
*Figure 5. The same chat under four conditions, rule A, output included.*
Space the turns six minutes apart and each copy has expired, so every turn writes its whole prompt: 17,300 tokens at $2.50 per million is $0.04325 for the input, and the total is 16% more. A date line first does the same. The table gives each rule's total against no caching, with the turns 1 minute apart and 40 minutes apart.
| Rule | 1 min | 40 min |
|---|---|---|
| A | 47% less | 16% more |
| B | 39% less | 39% less |
| C | 45% less | 16% more |
| D | 43% less | 15% more |
With a date line first, every rule loses: A 16% more, B 63% more, C 16% more, D 15% more. B pays its higher write price on every turn. D saves a little less than A because its first two prompts, 560 and 820 tokens, are under the 1,024-token minimum and are billed normally.
### Time saved
A reused start is not read again, so the first word can come sooner. Using the best-case model of [Why does an AI wait a moment before the first word?](https://spicyshark.co/learn/why-ai-waits-before-the-first-word/), a chip at its data-sheet speed with nothing measured, reading n tokens takes the larger of a math floor and a memory floor. The newest token is always read, so a fully reused prompt still costs one pass.
The table gives the tokens reused out of the prompt, then the first-word time in milliseconds before and after reuse.
| Reused | Before | After |
|---|---|---|
| 8,000 of 8,020 | 412.8 | 7.9 |
| 2,640 of 2,900 | 149.3 | 13.4 |
| 0 of 560 | 28.8 | 28.8 |
The first row is an 8,000-token document and a 20-token question. Its 20 new tokens are far under the 153-token ridge of that lesson, so the pass costs one decode step, 7.9 ms. The second row is the chat's last turn, where 260 new tokens remain. Real services add network time and waiting in line, and the provider pages read for this lesson give no latency figure, so treat these as limits of the model, not promises.
### A self-hosted server can reuse part of a start
A server running its own model is not bound by a provider's rule, and vLLM reuses part of a start. Its automatic prefix caching keeps notes in blocks of tokens and hashes each block together with all the tokens before it, so a new request finds every leading block that matches, and a block is found only if everything before it matches too. Only full blocks are cached, and the least recently used are dropped first (vLLM documentation, read 2026-10-19). None of the four rules above works this way, and the toy does not model it. [Why AI servers waste memory, and how paging fixes it](https://spicyshark.co/learn/paged-kv-cache/#sharing-a-prefix-with-copy-on-write) shows the sharing.
### How to order a prompt
Put these in this order, mark the end of the shared part (items 1 and 2), and keep that part identical, character for character. A changed space, a reordered list or a random ID counts as a difference.
1. Fixed instructions and examples.
2. Long documents that several requests share.
3. The conversation so far.
4. The new question.
5. Lines that change every time, such as the date: last, or left out.
### Checking a hit rate
After each response, compare what you expected with what the provider reports. Anthropic's responses carry `cache_read_input_tokens` and `cache_creation_input_tokens` next to `input_tokens`, and OpenAI's carry `cached_tokens`; each page says which counts include which. A hit rate is the share of input read from storage:
```python
hit_rate = read / (read + written + plain) # 14,400 / 17,300 = 83% for the chat above
```
A rate near zero when you expected a high one means the start differs earlier than you think. Log it per request, not as one daily average, so a change that adds a date line stands out.
### Proof it works
`test_prefix_cache.py` has 27 tests. The shared start is compared with Python's `os.path.commonprefix`, which would catch a count that kept going after a difference. A stored start is read whole or not at all, and a request that shares most of one reads nothing from it. Bills are checked by hand. A copy hits at minute 5 and misses at minute 6, and requests every 4 minutes keep it alive. The break-even for each rule is checked against a brute-force run of the simulation. With caching off, the chat gives [lesson 7](https://spicyshark.co/learn/why-ai-bill-is-high/)'s $0.0546, with it on, the closed form above, and each rule's chat total is pinned at 1 minute, 40 minutes and with the date first. `test_widget.py` has 9 tests. It runs the widget's JavaScript in Node against the Python for 800 combinations of settings, with the mark box ticked and unticked, and drives the page through a small stand-in for the browser. All 36 tests run in about 3 seconds.
### Where this is used in practice
Anthropic's and OpenAI's pages above are the sources for rules A to D. OpenAI's guide says caching can discount input by up to 95%; that is its figure, and a read at 0.05 times the normal price gives that number. SGLang (Zheng et al., 2023, body read 2026-10-19) keeps cached prefixes in a radix tree, described in its section 3 as RadixAttention, and its authors report up to 6.4 times the throughput on their tests, a figure for whole systems and not this lesson's bills.
## Skills this lesson builds
- Explain why a request reuses a stored start only whole, and why one changed token before the mark voids it.
- Order a prompt so the fixed part comes first, and mark where it ends.
- Work out the break-even number of reads from a write price and a read price.
- Compare a chat's bill with and without caching, including the cases where caching costs more.
- Check from a response's usage numbers how many input tokens were read from storage.
**Portfolio project:** pick one provider that offers caching. Write a script that sends a 3,000-token fixed document with ten different questions, once with a date line first and once with it last, a minute apart. Record the tokens read from storage and the cost of each request, using the provider's price page. Publish the script, a results table and a note on where the bill differs from the formula in this lesson.
## Check yourself
1. An app starts every request with "Today is" and the current time, then 2,000 tokens of fixed instructions. Caching saves nothing. Why, and what is the fix?
Answer
The first tokens change every time, and a request reuses a stored start only if it begins with all of it, so nothing is reused. Move the date line after the instructions, next to the question, and mark the end of the instructions.Answer
The first. Each gap is 4 minutes, under 5, and each use starts the clock again, so minutes 4, 8 and 12 are reads. The second has gaps of 6 minutes, so each copy expires before the next request and every request writes again.Answer
With caching: 1,200 x $2.50 per million is $0.003000 for the write, plus 2 reads of 1,200 x $0.10 per million, $0.000240, so $0.003240. Without: 3 x 1,200 x $2.00 per million is $0.007200.Answer
The formula gives (4 - 2) / (2 - 0.10) = 1.05, so 2 reads. Check per million tokens: with 1 read it is $4.10 against $4.00 without, still behind; with 2 reads it is $4.20 against $6.00.Answer
Caching changes only the input price. The output, $0.02, is billed as usual: the total falls from $0.0546 to $0.02869, while the input alone falls from $0.0346 to $0.00869.