On this page
You add up what you type and what the bot writes back, multiply by the price, and expect a small bill. Take a chat of ten turns (a turn is one message from you and its reply). Each message is 60 tokens (a token is a chunk of text, often a short word or part of one), each reply is 200 tokens, and the app sends a 500-token system prompt, the standing instructions, with every message. At example prices of $2 per million tokens sent and $10 per million written, what you typed and what came back cost $0.0212. Billed the way providers bill it, the same chat costs $0.0546, 2.6 times as much, because every message sends the whole chat again.
In one minute
Your AI bill is higher than you expect because the service charges for every token it reads and writes, and each new message makes it read the whole chat again. Picture a consultant who bills by the page and re-reads the whole file before each question: even a one-line tenth question carries every page before it. In the price rows we read, writing costs more than reading, and some models also write long hidden working-out that is billed as writing. The fixes all come down to sending less on each turn and watching the numbers.
Explore the numbers
Open the widget. Set Turns per chat to 30 and watch each turn cost more than the last as the orange re-sent history grows. Then tick “Keep last 3 turns” and watch the monthly total fall. Prices, message sizes and the retry rate sit under More settings.
The starting prices, $2 and $10 per million tokens, are example figures, not a quote; each provider publishes its own: Anthropic, OpenAI and Google (read 2026-10-19). Google’s token guide says 100 tokens are about 60 to 80 English words (read 2026-10-19), which is how the widget turns tokens into words. The starting chat costs $0.0546, and 100 such chats a day for 30 days cost $163.80.
How it works
What the bill counts
An AI service charges by the token and keeps two counts. Input tokens are everything your app sends in one call (one request to the service): your new message and everything that travels with it. Output tokens are everything the model writes back. Each has its own price per million tokens, and writing costs more: Anthropic’s pricing page lists one model at $2 per million input tokens and $10 per million output tokens, and OpenAI’s page lists a model at the same two prices (both read on 2026-10-19), five times as much for output. More in What is a token?.
Every turn sends the whole chat again
A model keeps nothing between calls, so to answer your tenth message the app sends all ten messages and nine replies. OpenAI’s conversation-state guide says that even when you chain responses, all earlier input tokens in the chain are billed as input again (read 2026-10-19).
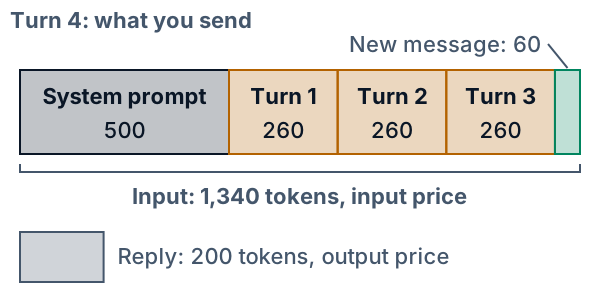
The new message is 60 tokens, yet turn 4 carries 1,340 input tokens and turn 10 carries 2,900. Of the 17,300 input tokens in the ten-turn chat, 11,700 (67.6%) are earlier chat sent again, 5,000 (28.9%) the system prompt and only 600 (3.5%) your new messages. Anthropic’s pricing page says the same system prompt, document or conversation history is processed again on each request (read 2026-10-19).
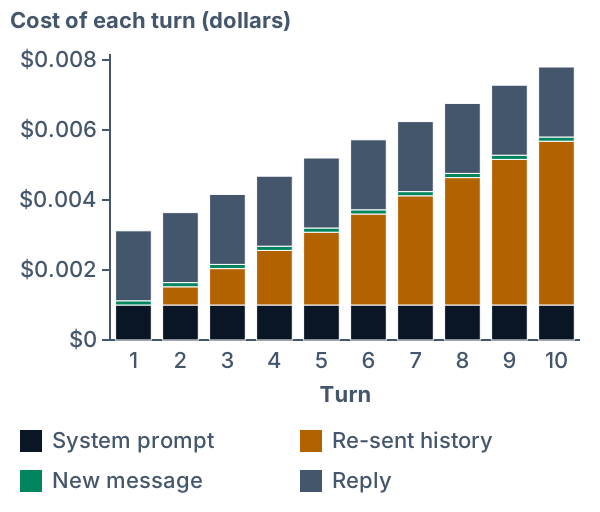
Ten turns cost $0.0546. Thirty turns cost $0.3198, nearly six times as much for three times the length.
What else rides along
Whatever your app attaches to every call is input every time: the system prompt, and any document you paste in. A 2,000-token system prompt in place of the 500-token one lifts the ten-turn chat from $0.0546 to $0.0846. Retries add more: a failed call sent again carries the same input a second time, and if one call in ten is sent twice the ten-turn chat costs $0.06006. The error pages read for this lesson do not say whether a failed call is billed.
Hidden reasoning is billed as output
Some models, called reasoning models, work out an answer in writing before they give it. You may never see that text, yet these reasoning tokens are billed as output. OpenAI’s reasoning guide says so, Anthropic’s page on steering thinking says the same of its thinking tokens, and Google’s pricing page labels its output price “including thinking tokens” (all read 2026-10-19). OpenAI’s guide adds that one reply can use from a few hundred to tens of thousands of them.
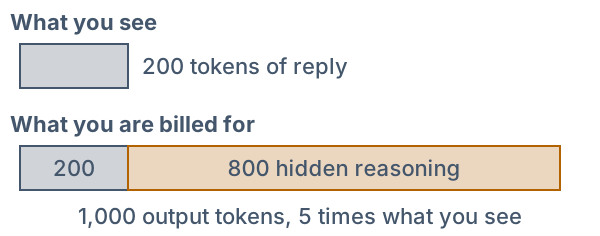
With 800 hidden tokens behind each 200-token reply, the example chat costs $0.1346 instead of $0.0546.
Cutting the history
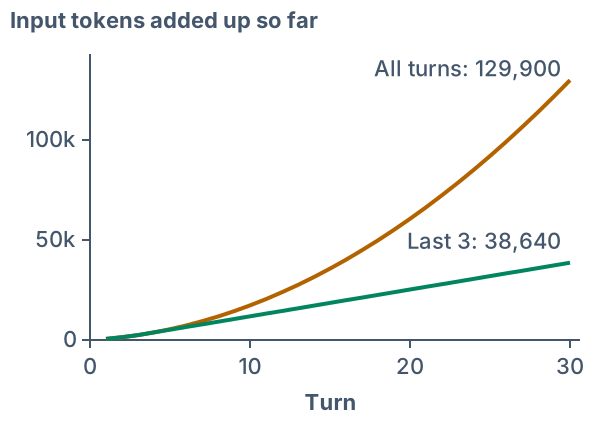
Send only the last few turns and the cost stops growing with the chat: keep the last 3 earlier turns and every call from turn 4 on carries 1,340 input tokens. The ten-turn chat then costs 20.0% less, the thirty-turn chat 57.1% less. The model no longer sees what you cut, which Why does a chatbot forget? explains.
What this means when you build
- Estimate with the whole chat, not one message. Add the system prompt and every earlier turn to each call: counting only what you type and what comes back was 2.6 times too low for ten turns and 5.0 times too low for thirty. Log the token counts each response reports.
- Send less. Keep the system prompt short, trim or summarize the history, and cap the length of replies: replies capped at 100 tokens bring the ten-turn chat from $0.0546 to $0.0356. On a reasoning model leave room in the cap: OpenAI’s guide warns you can pay for input and reasoning and get no visible reply if the cap runs out first.
- Use a smaller model for easy steps. Anthropic’s page lists $0.10 and $0.50 per million tokens for its small model, Haiku 5.5, against $2 and $10 for Sonnet 5.5, for prompts up to 100,000 tokens (read 2026-10-19): 20 times less for the example chat.
- Reuse a repeated start. Providers can store the start of a prompt that repeats and bill reading it back at a lower price: $0.10 per million tokens against $2 for ordinary input, on one Anthropic row and one OpenAI row (read 2026-10-19). What is prompt caching? explains when it pays; the linked pricing pages list each cached-input price.
- Set a spending limit or alert wherever your provider offers one, and keep the key on your own server: An API key in the browser shows how.
Optionalabout 12 min
Go deeper
Optional. This part is for readers who write Python. The code is in the code/ folder next to this lesson, and python3 show_numbers.py prints the numbers below that the code computes. Sizes are in tokens, and prices are dollars per million tokens.
The naive estimate, and why it fails
The first estimate most people write prices what they type and what comes back, once for each turn:
def naive_bill(chat, price_in, price_out):
    tokens_in = chat.turns * chat.message
    tokens_out = chat.turns * (chat.reply + chat.reasoning)
    cost_in = tokens_in * _price(price_in, "price_in")
    cost_out = tokens_out * _price(price_out, "price_out")
    return (cost_in + cost_out) / PER
(The docstring is left out here. _price turns a price into a Decimal, so cents are exact, and refuses a negative one.) It gives $0.0212 for the ten-turn example and $0.0636 for thirty turns. The real bills are $0.0546 and $0.3198, which are 2.6 and 5.0 times higher. The estimate leaves out two things that every call carries, the system prompt and the earlier turns, and it grows in a straight line with the number of turns while the real bill does not.
One turn by hand
Turn k sends k - 1 earlier turns, and each earlier turn is a message and its reply: 60 + 200 = 260 tokens. So the input of turn k is the system prompt (500 tokens), plus 260 x (k - 1), plus the new message (60 tokens). The output is the 200-token reply every turn.
| turn | input | cost |
|---|---|---|
| 1 | 560 | $0.00312 |
| 2 | 820 | $0.00364 |
| 3 | 1,080 | $0.00416 |
| 4 | 1,340 | $0.00468 |
| 10 | 2,900 | $0.0078 |
The cost of turn 4 by hand is 1,340 x 2 + 200 x 10 = 2,680 + 2,000 = 4,680 millionths of a dollar, which is $0.00468. All ten turns together send 17,300 input tokens and write 2,000, so the bill is $0.0346 for input plus $0.02 for output, $0.0546 in all. Output is 36.6% of the money while it is only 10.4% of the tokens.
Adding it up without a loop
The brute-force way walks through the turns the way a chat app does. history holds the sizes of the earlier messages, and trimming keeps the last 2 * keep of them:
def simulate(chat):
    history = []  # earlier message sizes, oldest first
    total_in = total_out = 0
    for _ in range(chat.turns):
        kept = history
        if chat.keep is not None:
            kept = history[max(0, len(history) - 2 * chat.keep):]
        total_in += chat.system + sum(kept) + chat.message
        total_out += chat.reply + chat.reasoning
        history += [chat.message, chat.reply]
    return total_in, total_out
The loop is the definition, and the tests use it as the reference. A closed form is shorter to compute and shows the shape. Turn k re-sends k - 1 earlier turns, and 0 + 1 + 2 + … + (n - 1) = n(n - 1)/2, which is 45 for n = 10. Every turn also sends the system prompt and the new message, which is the fixed line below:
def closed_form(chat):
    n = chat.turns
    t = n - 1 if chat.keep is None else min(n - 1, chat.keep)
    earlier_turns = t * (t + 1) // 2
    if chat.keep is not None:
        earlier_turns += chat.keep * (n - 1 - t)
    fixed = n * (chat.system + chat.message)
    total_in = fixed + (chat.message + chat.reply) * earlier_turns
    return total_in, n * (chat.reply + chat.reasoning)
With nothing trimmed, t is n - 1, the if adds nothing and earlier_turns is (n - 1)n/2. By hand: 10 x 560 + 260 x 45 = 5,600 + 11,700 = 17,300, the same as the loop. The n(n - 1)/2 term makes the bill grow with the square of the chat length, so a chat twice as long needs about four times the history. The longer chats show it, first in tokens:
| turns | input | output |
|---|---|---|
| 10 | 17,300 | 2,000 |
| 20 | 60,600 | 4,000 |
| 30 | 129,900 | 6,000 |
Then in dollars, next to the cost if every turn were a fresh start:
| turns | cost | fresh start |
|---|---|---|
| 10 | $0.0546 | $0.0312 |
| 20 | $0.1612 | $0.0624 |
| 30 | $0.3198 | $0.0936 |
A fresh start is a one-turn chat with the same system prompt, which costs $0.00312. Doubling the chat from 10 to 20 turns takes the input from 17,300 to 60,600 tokens, 3.5 times as many.
Trimming turns the curve into a line
With keep set to N, the first N + 1 turns re-send 0, 1, …, N earlier turns, and every later turn re-sends N. That is N(N + 1)/2 + N x (n - 1 - N) earlier turns in all, the two lines that build earlier_turns above. For N = 3 and n = 10 it is 6 + 18 = 24, so the input is 5,600 + 260 x 24 = 11,840 tokens against 17,300. From turn 4 on, every turn sends 1,340 input tokens, so the total grows in a straight line: 38,640 tokens for 30 turns against 129,900 untrimmed. Across a month of 100 chats a day (3,000 chats at 30 days), the totals are, sending all turns or only the last 3 earlier turns:
| chat | all turns | last 3 |
|---|---|---|
| 10 turns | $163.80 | $131.04 |
| 30 turns | $959.40 | $411.84 |
Reasoning and retries
The reasoning field of Chat adds reasoning tokens to the output of every turn, and to nothing else. With 800 hidden tokens per reply, the output goes from 2,000 to 10,000 tokens and the bill rises by $0.08, from $0.0546 to $0.1346. Retries live in bill, which takes the share of calls made twice as retry_rate:
    tokens_in, tokens_out = closed_form(chat)
    cost_in = tokens_in * price_in / PER
    cost_out = tokens_out * price_out / PER
    retry_cost = (cost_in + cost_out) * retry_rate
    return Bill(tokens_in, tokens_out, cost_in, cost_out, retry_cost)
(These are the last lines of bill.) The cost model counts a retry as one more full call with the same input, so one call in ten adds a tenth of the bill: $0.00546 on $0.0546, $0.06006 in all.
What the cost model leaves out
In this lesson “the cost model” is the arithmetic in bill.py, and “the model” alone is the AI model.
- Reasoning may be sent back. The cost model treats reasoning tokens as output only and leaves them out of the history. Providers differ. Anthropic’s page on steering thinking (read 2026-10-19) says that thinking blocks from earlier turns that stay in the context are billed as input, on every earlier turn for some models and on the last one for the rest. OpenAI’s guide on conversation state (read 2026-10-19) says that models with persisted reasoning can use
reasoning.context: "all_turns"to bring reasoning from earlier turns into the next request, and it does not say how that is billed. If yours does this, the history part is larger than the cost model says. - A failed call may not cost a full call. The cost model bills a failed call in full, which is an upper bound. Anthropic’s errors page says its SDK retries transient failures twice by default, with exponential backoff, and OpenAI’s error-codes guide advises backoff with jitter and a limit on retries (both read 2026-10-19). Neither page says whether a failed request is billed.
- Prices that change. The real prices below move with prompt length for some models, and the cost model uses one flat price. It also leaves out cached input, which costs less, and the 50% discount Anthropic’s page lists for its Batch API.
- Token counts depend on the tokenizer. Anthropic’s token-counting page says its newer tokenizers give about 30% more tokens for the same text and that billing follows, and that the count it returns is an estimate. Count with your provider’s own tool.
Sonnet 5.5 and Haiku 5.5 are Anthropic’s, gpt-6.1-sol and gpt-6-luna are OpenAI’s, and Gemini 3.1 Pro, here the Preview release, is Google’s. Haiku’s prices are for prompts up to 100,000 tokens, the OpenAI rows are the standard tier at short context, and Gemini’s are for prompts up to 200,000 tokens.
| model | input | output |
|---|---|---|
| Sonnet 5.5 | $2 | $10 |
| Haiku 5.5 | $0.10 | $0.50 |
| gpt-6.1-sol | $2.00 | $10.00 |
| gpt-6-luna | $0.10 | $0.50 |
| Gemini 3.1 Pro | $2.00 | $12.00 |
These are dollars per million tokens, read on 2026-10-19. Output costs five times as much as input in four rows and six times in the Gemini row. The example chat costs $0.0546 at $2 and $10 and $0.00273 at $0.10 and $0.50, which is 20 times less.
Proof it works
cd lessons/why-ai-bill-is-high/code && python3 -m pytest -q
python3 embed_widget.py --check
The tests check these claims. The closed form equals the simulation on 960 different chats, trimmed and untrimmed, with and without reasoning tokens, and the per-turn parts add up to the same totals. The example chat gives the hand-computed turns, 17,300 input and 2,000 output tokens and $0.0546. Untrimmed, each turn adds 260 tokens more to the total than the turn before, which is what makes it quadratic. Trimmed, once the window is full every turn adds the same amount, and trimming never costs more. Reasoning adds output cost only. The retry term equals the expected cost over every choice of which of six turns are retried, worked out with exact fractions, and the naive estimate misses exactly the system prompt and the history. The answers in Check yourself are pinned, and nonsense sizes and negative prices are refused. Six more tests guard the widget’s starting numbers, its markup and its cost arithmetic; none of them checks how the widget draws or words its results. For the arithmetic, one test runs the widget’s JavaScript under Node.js (so it needs Node.js installed) on 3,783 combinations of chat, prices and retry rate and requires the same tokens and dollars as the Python. Changing the trimmed sum, dropping the reasoning term or the retry term, or changing the trimmed tail makes a test fail. The embed check fails if the defaults in widget.html drift from bill.py.
Where this is used in practice
- Usage fields. OpenAI returns
output_tokens_details.reasoning_tokens, Anthropic returnsusage.output_tokens_details.thinking_tokenswithoutput_tokensas the total you are billed for, and Google’s usage object hastotal_input_tokens,total_output_tokensandtotal_thought_tokens. Log them per call. - Caps. OpenAI’s
max_output_tokensand Anthropic’smax_tokenscap the reasoning and the visible reply together. - Counting before you send. Google has
count_tokens. Anthropic’s counting endpoint is free but rate-limited. - Chained conversations. OpenAI’s
previous_response_idsaves you from re-sending the history yourself, but not from paying for it.
Skills this lesson builds
- Estimate the bill of a chat feature from message sizes and prices, with the history term included.
- Write a cost model and check its closed form against a turn-by-turn simulation.
- Read a provider’s usage fields and tell input, output and reasoning tokens apart.
- Compare fixes (trim, cap, shorten, smaller model, cached start) by the money each saves.
- Name what a cost model leaves out, such as price tiers, discounts and billed failures.
Portfolio project: write a small command-line tool that reads a log of calls (input and output token counts per call), prints the cost per chat and per turn and the share spent on earlier turns sent again, and shows the saving from trimming to the last N turns. Publish a chart of cost per turn for a chat you ran yourself.
Check yourself
-
A ten-turn chat has 60-token messages, 200-token replies and a 500-token system prompt. Your sum of what you type and what comes back says $0.0212, and the bill says $0.0546. Where did the rest come from?
Answer
The sum counted each message once. The app sends the system prompt and all the earlier turns again with every message, so the input is 17,300 tokens, not 600. That is $0.0346 for input plus $0.02 for output.
-
Why does a 30-turn chat cost nearly six times as much as a 10-turn chat, when it is only three times as long?
Answer
Each turn sends every earlier turn again, so each call carries 260 more input tokens than the call before: turn 10 sends 2,900 and turn 30 sends 8,100. Total input is 129,900 tokens against 17,300, and the cost is $0.3198 against $0.0546.
-
A chat has 4 turns, a 100-token system prompt, 10-token messages and 20-token replies. How many input tokens does it send in all, and how many if each call keeps only the last 1 earlier turn? What does the first case cost at $2 and $10 per million?
Answer
Untrimmed: 4 x 110 + 30 x (0 + 1 + 2 + 3) = 440 + 180 = 620 tokens. Keeping 1 earlier turn: 4 x 110 + 30 x (0 + 1 + 1 + 1) = 530 tokens. Output is 4 x 20 = 80 tokens. The first case costs 620 x 2 + 80 x 10 = 2,040 millionths of a dollar, $0.00204.
-
A reply shows 150 tokens, but the model spent 600 reasoning tokens first. At $10 per million output tokens, what does the reply cost, and what would it cost without the reasoning?
Answer
Reasoning tokens are billed as output, so it is 750 x 10 = 7,500 millionths of a dollar, $0.0075. Without the reasoning it would be 150 x 10 = $0.0015, five times less.
-
A chat has 8 turns, a 200-token system prompt, 30-token messages and 70-token replies, and each call keeps the last 2 earlier turns. How many input tokens does it send, against sending everything?
Answer
Each earlier turn is 100 tokens. Everything: 8 x 230 + 100 x 28 = 1,840 + 2,800 = 4,640 tokens. Trimmed, the turns re-send 0, 1, 2, 2, 2, 2, 2, 2 earlier turns, 13 in all: 1,840 + 1,300 = 3,140 tokens, which is 32.3% fewer.
Further reading
Web pages were read on 2026-10-19; providers change them.
Gentle
- Pricing (Anthropic documentation)
- Pricing (OpenAI documentation)
- Gemini API pricing (Google)
- Conversation state (OpenAI documentation)
- Reasoning models (OpenAI documentation)
- Thinking (Google)
- Understand and count tokens (Google)
Deep
- Steering thinking and cost (Anthropic documentation)
- Extended thinking (Anthropic documentation)
- Token counting (Anthropic documentation)
- Errors (Anthropic documentation)
- Error codes (OpenAI documentation)
Optional
Code
Each file runs on its own. Download it, or read it here.
Show code
"""What an AI chat bill is made of, turn by turn, and a closed form for the total.

Python standard library only. Run `python3 show_numbers.py` to print every number the
lesson quotes.

The model: every turn the app sends the provider the system prompt, the earlier turns
(unless trimmed) and the new message, and the provider bills those as input tokens. It
then bills the reply, plus any hidden reasoning tokens, as output tokens. The two kinds
of token have two prices. Sizes are in tokens; prices are dollars per million tokens.
Reasoning tokens are assumed not to be sent back as history. Some providers do send
them back (the lesson cites which), and then the history part would be larger.
"""
from dataclasses import dataclass
from decimal import Decimal
from typing import Optional

PER = Decimal(1_000_000)
DAYS_PER_MONTH = 30


@dataclass(frozen=True)
class Chat:
    system: int                  # system prompt, tool definitions and pasted documents: sent on every call
    message: int                 # tokens in each new user message
    reply: int                   # visible tokens in each reply
    turns: int                   # user messages in the chat
    reasoning: int = 0           # hidden reasoning tokens per reply, billed as output
    keep: Optional[int] = None   # send only the last `keep` earlier turns; None sends them all

    def __post_init__(self):
        if self.turns < 1 or min(self.system, self.message, self.reply, self.reasoning) < 0:
            raise ValueError("turns must be at least 1 and sizes cannot be negative")
        if self.keep is not None and self.keep < 0:
            raise ValueError("keep cannot be negative")


@dataclass(frozen=True)
class Turn:
    system: int
    history: int
    message: int
    reply: int
    reasoning: int

    @property
    def input(self):
        return self.system + self.history + self.message

    @property
    def output(self):
        return self.reply + self.reasoning


def turn_parts(chat, k):
    """The tokens of turn k (counting from 1), split the way the widget's bar splits them."""
    earlier = k - 1 if chat.keep is None else min(k - 1, chat.keep)
    return Turn(chat.system, earlier * (chat.message + chat.reply), chat.message, chat.reply, chat.reasoning)


def simulate(chat):
    """Input and output tokens of the whole chat, found by walking through every turn."""
    history = []  # earlier message sizes, oldest first
    total_in = total_out = 0
    for _ in range(chat.turns):
        kept = history
        if chat.keep is not None:
            kept = history[max(0, len(history) - 2 * chat.keep):]
        total_in += chat.system + sum(kept) + chat.message
        total_out += chat.reply + chat.reasoning
        history += [chat.message, chat.reply]
    return total_in, total_out


def closed_form(chat):
    """The same two totals without the loop.

    Untrimmed, turn k re-sends k-1 earlier turns, and 0 + 1 + ... + (n-1) = n(n-1)/2.
    Trimmed to N turns, the first N+1 turns re-send 0, 1, ..., N earlier turns and every
    later turn re-sends N.
    """
    n = chat.turns
    t = n - 1 if chat.keep is None else min(n - 1, chat.keep)
    earlier_turns = t * (t + 1) // 2
    if chat.keep is not None:
        earlier_turns += chat.keep * (n - 1 - t)
    fixed = n * (chat.system + chat.message)
    total_in = fixed + (chat.message + chat.reply) * earlier_turns
    return total_in, n * (chat.reply + chat.reasoning)


@dataclass(frozen=True)
class Bill:
    input_tokens: int
    output_tokens: int
    input_cost: Decimal
    output_cost: Decimal
    retry_cost: Decimal

    @property
    def total(self):
        return self.input_cost + self.output_cost + self.retry_cost


def _price(value, name):
    value = Decimal(str(value))
    if value < 0:
        raise ValueError(f"{name} cannot be negative")
    return value


def turn_cost(chat, k, price_in, price_out):
    """Dollars for turn k: input at the input price plus output at the output price."""
    parts = turn_parts(chat, k)
    return (parts.input * _price(price_in, "price_in") + parts.output * _price(price_out, "price_out")) / PER


def bill(chat, price_in, price_out, retry_rate=0):
    """Dollars for the whole chat. Prices are dollars per million tokens.

    retry_rate is the average number of extra full calls per call: 0.1 means one call in ten
    is made twice and both are billed. A retry sends the same input again, so it adds
    retry_rate times the whole bill.
    """
    price_in, price_out, retry_rate = _price(price_in, "price_in"), _price(price_out, "price_out"), _price(retry_rate, "retry_rate")
    tokens_in, tokens_out = closed_form(chat)
    cost_in = tokens_in * price_in / PER
    cost_out = tokens_out * price_out / PER
    retry_cost = (cost_in + cost_out) * retry_rate
    return Bill(tokens_in, tokens_out, cost_in, cost_out, retry_cost)


def naive_bill(chat, price_in, price_out):
    """The estimate most people make first: what you type, and what comes back, each billed once."""
    tokens_in = chat.turns * chat.message
    tokens_out = chat.turns * (chat.reply + chat.reasoning)
    cost_in = tokens_in * _price(price_in, "price_in")
    cost_out = tokens_out * _price(price_out, "price_out")
    return (cost_in + cost_out) / PER


# The chat the lesson and its widget start from. The prices are example figures, not a quote.
EXAMPLE = Chat(system=500, message=60, reply=200, turns=10)
EXAMPLE_PRICES = (2, 10)         # dollars per million input tokens, dollars per million output tokens
EXAMPLE_KEEP = 3                 # the "last N turns" the widget's trim box starts at
EXAMPLE_CHATS_PER_DAY = 100Show code
"""Keep the numbers inside ../widget.html equal to the ones in bill.py.

    python3 embed_widget.py          rewrite the data block in widget.html
    python3 embed_widget.py --check  exit 1 if widget.html differs (test_widget.py runs the same check)
"""
import json
import re
import sys
from pathlib import Path

from bill import DAYS_PER_MONTH, EXAMPLE, EXAMPLE_CHATS_PER_DAY, EXAMPLE_KEEP, EXAMPLE_PRICES

WIDGET = Path(__file__).resolve().parent.parent / "widget.html"
CONFIG_BLOCK = re.compile(r'(<script type="application/json" id="bil-config">)(.*?)(</script>)', re.S)
WORDS_PER_100_TOKENS = (60, 80)   # Google's tokens page: "100 tokens is equal to about 60-80 English words"


def config():
    return {"system": EXAMPLE.system, "turns": EXAMPLE.turns, "message": EXAMPLE.message, "reply": EXAMPLE.reply,
            "reasoning": EXAMPLE.reasoning, "chatsPerDay": EXAMPLE_CHATS_PER_DAY, "retryPercent": 0,
            "priceIn": EXAMPLE_PRICES[0], "priceOut": EXAMPLE_PRICES[1], "keep": EXAMPLE_KEEP,
            "daysPerMonth": DAYS_PER_MONTH, "wordsPer100Tokens": list(WORDS_PER_100_TOKENS)}


def embed(html):
    """html with the config block rewritten from bill.py."""
    block = json.dumps(config(), indent=1)
    return CONFIG_BLOCK.sub(lambda m: m.group(1) + "\n" + block + "\n" + m.group(3), html, count=1)


if __name__ == "__main__":
    current = WIDGET.read_text(encoding="utf-8")
    updated = embed(current)
    if "--check" in sys.argv:
        sys.exit(0 if updated == current else 1)
    WIDGET.write_text(updated, encoding="utf-8")
print("widget.html data block now matches bill.py")Show code
"""Print every number the lesson computes. Run it from this folder: python3 show_numbers.py"""
from dataclasses import replace
from decimal import Decimal

from bill import (DAYS_PER_MONTH, EXAMPLE, EXAMPLE_CHATS_PER_DAY, EXAMPLE_KEEP, EXAMPLE_PRICES as PRICES, bill, closed_form,
                  naive_bill, simulate, turn_cost, turn_parts)

P_IN, P_OUT = PRICES


def pct(part, whole):
    return f"{100 * Decimal(part) / Decimal(whole):.1f}%"


def money(x):
    text = f"{x.normalize():f}"
    whole, _, cents = text.partition(".")
    return f"${int(whole):,}.{cents.ljust(2, '0')}"


print(f"== The example chat: {EXAMPLE.turns} turns, system prompt {EXAMPLE.system}, each message {EXAMPLE.message}, "
      f"each reply {EXAMPLE.reply} tokens. Example prices ${P_IN} in, ${P_OUT} out per million tokens")
print("  turn | system | history | message | input | output | cost | running total")
running = Decimal(0)
for k in range(1, EXAMPLE.turns + 1):
    t, c = turn_parts(EXAMPLE, k), turn_cost(EXAMPLE, k, *PRICES)
    running += c
    print(f"  {k} | {t.system} | {t.history:,} | {t.message} | {t.input:,} | {t.output} | {money(c)} | {money(running)}")

b = bill(EXAMPLE, *PRICES)
loop, closed = simulate(EXAMPLE), closed_form(EXAMPLE)
print(f"\n== Whole chat: simulated {loop[0]:,} in / {loop[1]:,} out; closed form {closed[0]:,} in / {closed[1]:,} out")
print(f"  input {money(b.input_cost)} + output {money(b.output_cost)} = {money(b.total)}; output is {pct(b.output_cost, b.total)} of the money "
      f"and {pct(b.output_tokens, b.input_tokens + b.output_tokens)} of the tokens")
sys_tokens = EXAMPLE.turns * EXAMPLE.system
hist_tokens = sum(turn_parts(EXAMPLE, k).history for k in range(1, EXAMPLE.turns + 1))
new_tokens = EXAMPLE.turns * EXAMPLE.message
print(f"  input tokens by part: system {sys_tokens:,} ({pct(sys_tokens, b.input_tokens)}), history {hist_tokens:,} "
      f"({pct(hist_tokens, b.input_tokens)}), new messages {new_tokens:,} ({pct(new_tokens, b.input_tokens)})")
last = turn_parts(EXAMPLE, EXAMPLE.turns)
print(f"  turn {EXAMPLE.turns}: {last.input:,} input tokens to answer a {EXAMPLE.message}-token message "
      f"({last.input // EXAMPLE.message}x, rounded down)")

print("\n== Longer chats, same sizes (a 'fresh start' is a one-turn chat: system prompt + one message + one reply)")
fresh = bill(replace(EXAMPLE, turns=1), *PRICES).total
print(f"  one fresh start: {money(fresh)}")
print("  turns | input tokens | output tokens | cost | cost of that many fresh starts | ratio")
for n in (10, 20, 30):
    c = replace(EXAMPLE, turns=n)
    x = bill(c, *PRICES)
    print(f"  {n} | {x.input_tokens:,} | {x.output_tokens:,} | {money(x.total)} | {money(fresh * n)} | {x.total / (fresh * n):.2f}x")

print(f"\n== Trim to the last {EXAMPLE_KEEP} earlier turns")
for n in (10, 30):
    full, trimmed = bill(replace(EXAMPLE, turns=n), *PRICES), bill(replace(EXAMPLE, turns=n, keep=EXAMPLE_KEEP), *PRICES)
    print(f"  {n} turns: input {full.input_tokens:,} -> {trimmed.input_tokens:,}; cost {money(full.total)} -> {money(trimmed.total)} "
          f"({pct(full.total - trimmed.total, full.total)} less)")
kept = replace(EXAMPLE, turns=30, keep=EXAMPLE_KEEP)
print(f"  per-turn input tokens, trimmed 30-turn chat, turns 1-6: {[turn_parts(kept, k).input for k in range(1, 7)]}; "
      f"from turn 4 on every turn sends {turn_parts(kept, 4).input:,}")
print(f"  untrimmed turns 1-6: {[turn_parts(replace(EXAMPLE, turns=30), k).input for k in range(1, 7)]}; turn 30 sends "
      f"{turn_parts(replace(EXAMPLE, turns=30), 30).input:,}")

print("\n== Other levers, 10-turn chat, example prices")
levers = [("baseline", EXAMPLE), ("system prompt 2,000 (tools and pasted documents)", replace(EXAMPLE, system=2000)),
          ("system prompt 100", replace(EXAMPLE, system=100)), ("replies capped at 100 tokens", replace(EXAMPLE, reply=100)),
          ("hidden reasoning 800 tokens per reply", replace(EXAMPLE, reasoning=800))]
for name, c in levers:
    x = bill(c, *PRICES)
    print(f"  {name}: {x.input_tokens:,} in / {x.output_tokens:,} out = {money(x.total)} ({x.total / b.total:.2f}x baseline)")
think = bill(replace(EXAMPLE, reasoning=800), *PRICES)
print(f"  reasoning adds {money(think.total - b.total)}; billed output tokens {think.output_tokens:,} against "
      f"{EXAMPLE.turns * EXAMPLE.reply:,} visible ({think.output_tokens // (EXAMPLE.turns * EXAMPLE.reply)}x)")

print("\n== Retries: one call in ten is made twice")
r = bill(EXAMPLE, *PRICES, retry_rate="0.1")
print(f"  base {money(r.input_cost + r.output_cost)} + retries {money(r.retry_cost)} = {money(r.total)}")

print("\n== Smaller model for the easy steps (prices read 2026-10-19: Sonnet 5.5 $2 / $10, Haiku 5.5 $0.10 / $0.50 per million)")
big, small = bill(EXAMPLE, 2, 10), bill(EXAMPLE, "0.10", "0.50")
print(f"  10-turn chat: {money(big.total)} at $2 / $10 against {money(small.total)} at $0.10 / $0.50 = {big.total / small.total:.0f}x cheaper")

print("\n== The naive estimate: only what you type and what comes back, each billed once")
for turns in (10, 30):
    c = replace(EXAMPLE, turns=turns)
    naive, real = naive_bill(c, *PRICES), bill(c, *PRICES).total
    print(f"  {turns}-turn chat: naive {money(naive)}, real {money(real)}, real is {real / naive:.1f}x the estimate")

print(f"\n== A month: {EXAMPLE_CHATS_PER_DAY} chats a day, {DAYS_PER_MONTH} days")
chats = EXAMPLE_CHATS_PER_DAY * DAYS_PER_MONTH
for name, c in (("10-turn chat", EXAMPLE), (f"10-turn chat trimmed to {EXAMPLE_KEEP}", replace(EXAMPLE, keep=EXAMPLE_KEEP)),
                ("30-turn chat", replace(EXAMPLE, turns=30)), (f"30-turn chat trimmed to {EXAMPLE_KEEP}", replace(EXAMPLE, turns=30, keep=EXAMPLE_KEEP))):
print(f" {name}: {chats:,} chats x {money(bill(c, *PRICES).total)} = {money(chats * bill(c, *PRICES).total)}")Show code
"""Guards for bill.py: the closed form must equal the turn-by-turn simulation, and trimming and
the reasoning and retry terms must add exactly what the lesson says."""
import itertools
from decimal import Decimal
from fractions import Fraction

import pytest

from bill import Chat, bill, closed_form, naive_bill, simulate, turn_cost, turn_parts

EXAMPLE = Chat(system=500, message=60, reply=200, turns=10)


def grid():
    for s, m, r, n, think, keep in itertools.product(
            (0, 500), (0, 60), (0, 200), range(1, 13), (0, 300), (None, 0, 1, 3, 20)):
        yield Chat(system=s, message=m, reply=r, turns=n, reasoning=think, keep=keep)


def test_closed_form_equals_simulating_every_turn():
    """Guards the algebra: a slip in n(n-1)/2 or in the trimmed sum shows up on some small chat."""
    count = 0
    for chat in grid():
        assert closed_form(chat) == simulate(chat), chat
        count += 1
    assert count == 2 * 2 * 2 * 12 * 2 * 5


def test_the_per_turn_parts_add_up_to_the_same_totals():
    for chat in grid():
        parts = [turn_parts(chat, k) for k in range(1, chat.turns + 1)]
        assert (sum(p.input for p in parts), sum(p.output for p in parts)) == closed_form(chat), chat


def test_example_chat_by_hand():
    """10 turns: input 500+60 at turn 1, then 260 more each turn; output 200 each turn."""
    assert [turn_parts(EXAMPLE, k).input for k in (1, 2, 3, 10)] == [560, 820, 1080, 2900]
    assert closed_form(EXAMPLE) == (5600 + 260 * 45, 2000) == (17300, 2000)
    b = bill(EXAMPLE, 2, 10)
    assert (b.input_cost, b.output_cost, b.total) == (Decimal("0.0346"), Decimal("0.02"), Decimal("0.0546"))


def test_untrimmed_input_grows_with_the_square_of_the_turns():
    """The first difference rises by m+r each turn, so the second difference is constant: a parabola."""
    def total(n):
        return closed_form(Chat(500, 60, 200, n))[0]
    firsts = [total(n) - total(n - 1) for n in range(2, 30)]
    assert firsts[0] == 500 + 60 + 260
    assert {b - a for a, b in zip(firsts, firsts[1:])} == {260}


def test_trimmed_cost_grows_linearly_once_the_window_is_full():
    """Guards the claim 'trim to N turns and the bill stops growing faster': every extra turn adds
    the same S + m + N(m+r) input tokens."""
    for keep in (0, 1, 3, 8):
        def total(n):
            return closed_form(Chat(500, 60, 200, n, keep=keep))[0]
        steps = {total(n) - total(n - 1) for n in range(keep + 2, 60)}
        assert steps == {500 + 60 + keep * 260}, keep


def test_trimming_changes_nothing_until_the_window_fills_and_never_costs_more():
    for n in range(1, 10):        # a window of 8 earlier turns holds every earlier turn of a chat up to 9 turns
        assert closed_form(Chat(500, 60, 200, n, keep=8)) == closed_form(Chat(500, 60, 200, n))
    for chat in grid():
        untrimmed = Chat(chat.system, chat.message, chat.reply, chat.turns, chat.reasoning)
        assert closed_form(chat)[0] <= closed_form(untrimmed)[0]
        assert closed_form(chat)[1] == closed_form(untrimmed)[1]


def test_reasoning_tokens_add_output_cost_only():
    """Guards the lesson sentence: hidden reasoning is billed as output, once per reply, and is
    not added to the input here (the model assumes it is not re-sent)."""
    plain, thinking = Chat(500, 60, 200, 10), Chat(500, 60, 200, 10, reasoning=800)
    a, b = bill(plain, 2, 10), bill(thinking, 2, 10)
    assert b.input_tokens == a.input_tokens
    assert b.output_tokens == a.output_tokens + 10 * 800
    assert b.total - a.total == Decimal(10 * 800) * 10 / 1_000_000 == Decimal("0.08")


def test_retries_add_their_share_of_every_call_again():
    base = bill(EXAMPLE, 2, 10)
    assert base.retry_cost == 0
    assert bill(EXAMPLE, 2, 10, retry_rate="0.1").retry_cost == base.total / 10
    assert bill(EXAMPLE, 2, 10, retry_rate="0.1").total == base.total * Decimal("1.1")


def test_retry_rate_is_the_expected_extra_cost_over_every_choice_of_retried_turns():
    """Guards 'the cost of retries is the retry rate times the bill': add up every way of choosing
    which turns of a 6-turn chat are made twice, each way weighted by its probability, exactly."""
    chat, q = Chat(500, 60, 200, 6, reasoning=100), Fraction(1, 4)
    per_turn = [Fraction(turn_cost(chat, k, 2, 10)) for k in range(1, 7)]
    expected = Fraction(0)
    for picked in itertools.product((False, True), repeat=6):
        p = Fraction(1)
        for flag in picked:
            p *= q if flag else 1 - q
        expected += p * sum(c * (2 if flag else 1) for c, flag in zip(per_turn, picked))
    assert expected == sum(per_turn) * (1 + q)
    assert Decimal(expected.numerator) / Decimal(expected.denominator) == bill(chat, 2, 10, retry_rate="0.25").total


def test_the_naive_estimate_misses_exactly_the_system_prompt_and_the_history():
    """Guards the lesson's opening claim: ignoring what rides along makes the estimate 2.6 times too low."""
    assert naive_bill(EXAMPLE, 2, 10) == Decimal("0.0212")
    long = Chat(system=500, message=60, reply=200, turns=30)
    assert naive_bill(long, 2, 10) == Decimal("0.0636")
    # hidden reasoning is output, so the naive estimate counts it: 10 turns x 600 more tokens at $10 per million
    assert naive_bill(Chat(system=500, message=60, reply=200, turns=10, reasoning=600), 2, 10) == Decimal("0.0812")
    for chat in (EXAMPLE, long, Chat(system=0, message=60, reply=200, turns=1)):
        tokens_in, _ = closed_form(chat)
        missed = Decimal(tokens_in - chat.turns * chat.message) * 2 / 1_000_000
        assert bill(chat, 2, 10).total - naive_bill(chat, 2, 10) == missed
    # a one-turn chat with no system prompt has nothing riding along, so the estimate is exact
    assert naive_bill(Chat(system=0, message=60, reply=200, turns=1), 2, 10) == bill(Chat(system=0, message=60, reply=200, turns=1), 2, 10).total


def test_the_check_yourself_answers():
    """Guards the numbers printed in the lesson's questions, so an edit to either side shows up here."""
    small = Chat(system=100, message=10, reply=20, turns=4)
    assert closed_form(small) == (4 * 110 + 30 * 6, 80) == (620, 80)
    assert closed_form(Chat(system=100, message=10, reply=20, turns=4, keep=1)) == (4 * 110 + 30 * 3, 80) == (530, 80)
    assert bill(small, 2, 10).total == Decimal("0.00204")
    thinker = Chat(system=0, message=0, reply=150, turns=1, reasoning=600)
    assert bill(thinker, 2, 10).output_cost == Decimal("0.0075") == 5 * bill(Chat(system=0, message=0, reply=150, turns=1), 2, 10).output_cost
    eight = Chat(system=200, message=30, reply=70, turns=8)
    assert closed_form(eight)[0] == 4640 and closed_form(Chat(system=200, message=30, reply=70, turns=8, keep=2))[0] == 3140


@pytest.mark.parametrize("kwargs", [
    dict(system=-1, message=1, reply=1, turns=1), dict(system=0, message=-1, reply=1, turns=1),
    dict(system=0, message=1, reply=-1, turns=1), dict(system=0, message=1, reply=1, turns=0),
    dict(system=0, message=1, reply=1, turns=1, reasoning=-1), dict(system=0, message=1, reply=1, turns=1, keep=-1),
])
def test_nonsense_sizes_are_refused(kwargs):
    with pytest.raises(ValueError):
        Chat(**kwargs)


def test_negative_prices_and_retry_rates_are_refused():
    for bad in (dict(price_in=-1, price_out=1), dict(price_in=1, price_out=-1), dict(price_in=1, price_out=1, retry_rate=-1)):
        with pytest.raises(ValueError):
bill(EXAMPLE, **bad)Show code
"""Guards for ../widget.html: its data block, its size, and that its bill arithmetic is bill.py's."""
import itertools
import json
import re
import shutil
import subprocess
from pathlib import Path

import pytest

from bill import DAYS_PER_MONTH, EXAMPLE, EXAMPLE_PRICES, Chat, bill, closed_form, turn_cost, turn_parts
import embed_widget
from embed_widget import WIDGET, embed

HTML = WIDGET.read_text(encoding="utf-8")

# Reads the bill functions out of the widget between its marker comments, runs them, and compares
# with the numbers Python wrote into the fixture.
PARITY = r"""
import fs from 'node:fs';
const [fixture, widget] = process.argv.slice(2);
const fx = JSON.parse(fs.readFileSync(fixture, 'utf8'));
const html = fs.readFileSync(widget, 'utf8');
const js = html.slice(html.indexOf('/* ---------- the bill'), html.indexOf('/* ---------- state'));
const api = new Function("'use strict';" + js + '; return {turnParts, totals, turnCost, bill};')();
const bad = [];
let checks = 0;
const close = (a, b) => Math.abs(a - b) <= 1e-12 * Math.max(1, Math.abs(b));
for (const f of fx) {
  const c = f.chat, [pIn, pOut] = f.prices;
  checks++;
  const t = api.totals(c);
  if (t.input !== f.input || t.output !== f.output) bad.push(['totals', c, t]);
  for (const [k, want] of f.parts) {
    if (JSON.stringify(api.turnParts(c, k)) !== JSON.stringify(want) || !close(api.turnCost(c, k, pIn, pOut), f.turnCosts[k - 1])) bad.push(['turn', c, k]);
  }
  const b = api.bill(c, pIn, pOut, f.retry);
  if (!close(b.inputCost, f.inputCost) || !close(b.outputCost, f.outputCost) || !close(b.retryCost, f.retryCost) || !close(b.total, f.total)) bad.push(['bill', c, b]);
}
console.log(JSON.stringify({ checks, bad: bad.slice(0, 5) }));
process.exit(bad.length ? 1 : 0);
"""


def test_widget_data_block_matches_bill_py():
    """Guards a change to the example chat or prices in bill.py that was not copied into the widget (run embed_widget.py)."""
    assert embed(HTML) == HTML


def test_every_element_the_script_looks_up_exists_where_it_looks():
    """Guards a widget that never starts: a lookup of an id that is not in the markup throws in the browser."""
    root = HTML[HTML.index('<div class="bil-root">'):HTML.index("<script")]
    script = HTML[HTML.index("<script>"):]
    ids = set(re.findall(r"\$\('([\w-]+)'\)", script)) | set(re.findall(r"id: '([\w-]+)'", script)) | set(re.findall(r"hint: '([\w-]+)'", script)) | set(re.findall(r"range: '([\w-]+)'", script))
    assert ids and all(f'id="{i}"' in root for i in ids), sorted(i for i in ids if f'id="{i}"' not in root)
    assert "$('bil-config')" not in script


def test_widget_is_small_and_asks_for_nothing_online():
    """The lesson page links the pricing pages; the widget, in a sandbox that cannot open links, holds no address."""
    assert len(HTML.encode("utf-8")) < 40 * 1024
    page = embed_widget.CONFIG_BLOCK.sub("", HTML)
    for banned in ("http://", "https://", "fetch(", "XMLHttpRequest", "WebSocket", "sendBeacon", "import("):
        assert banned not in page, banned
    assert " src=" not in page and "@import" not in page


def test_widget_has_no_form_element():
    """The lesson page loads the widget in a sandbox where a form cannot submit; inputs are read on change."""
    assert "<form" not in HTML


# Calls the widget's two sentence builders the way paint() does, for three chats, and prints what they say.
NOTES = r"""
import fs from 'node:fs';
const html = fs.readFileSync(process.argv[2], 'utf8');
const js = html.slice(html.indexOf('/* ---------- the bill'), html.indexOf('/* ---------- state'));
const api = new Function("'use strict';" + js + '; return {bill, turnCost, trendNote, trimNote};')();
const out = [];
for (const [turns, keep] of [[1, null], [1, 0], [10, 1], [10, 0], [10, null]]) {
  const mk = k => ({ system: 500, message: 60, reply: 200, turns, reasoning: 0, keep: k });
  const trim = keep !== null, chat = mk(keep), whole = mk(null);
  const b = api.bill(chat, 2, 10, 0), full = api.bill(whole, 2, 10, 0);
  out.push([api.trendNote(turns, api.turnCost(chat, 1, 2, 10), api.turnCost(chat, turns, 2, 10)),
            api.trimNote(trim, keep, trim && b.input !== full.input, b.total, full.total)]);
}
console.log(JSON.stringify(out));
"""

NOTES_WANT = [
    ["A one-turn chat has no history to re-send.", "Tick “Keep last” to compare."],
    ["A one-turn chat has no history to re-send.", "Your chat has no more than 1 turn, so nothing is cut yet."],
    ["Turn 1 costs $0.00312. Turn 10 costs $0.00364, 1.2 times as much.",
     "Sending only the last earlier turn: $0.03588 per chat instead of $0.0546, 34.3% less."],
    ["Turn 1 costs $0.00312. Turn 10 costs $0.00312, 1.0 times as much.",
     "Sending no earlier turns: $0.0312 per chat instead of $0.0546, 42.9% less."],
    ["Turn 1 costs $0.00312. Turn 10 costs $0.0078, 2.5 times as much.", "Tick “Keep last” to compare."],
]


def test_widget_sentences_read_right_for_one_turn_one_kept_turn_and_the_default(tmp_path):
    """Guards the plural slips in the trend and trim sentences ("last 1 earlier turns", "1 turns") and the
    wording of the sentences under the answer: one turn, one or no kept turns with a cut, and the lesson's default."""
    if shutil.which("node") is None:
        pytest.skip("Node.js is not installed")
    (tmp_path / "notes.mjs").write_text(NOTES, encoding="utf-8")
    run = subprocess.run(["node", str(tmp_path / "notes.mjs"), str(WIDGET)], capture_output=True, text=True, timeout=60)
    assert run.returncode == 0, run.stdout + run.stderr
    assert json.loads(run.stdout) == NOTES_WANT


def test_widget_bill_arithmetic_matches_the_python_code(tmp_path):
    """Guards the widget's JavaScript drifting from bill.py: its token counts must equal bill.py's exactly
    and its dollars must agree to rounding error, for trimmed, untrimmed, reasoning and retry cases."""
    if shutil.which("node") is None:
        pytest.skip("Node.js is not installed")
    chats = [Chat(s, m, r, n, think, keep) for s, m, r, n, think, keep in
             itertools.product((0, 500, 2000), (0, 60, 900), (0, 200), (1, 2, 3, 4, 10, 30, 60), (0, 800), (None, 0, 1, 3, 59))]
    chats.append(EXAMPLE)
    fixture = []
    for chat in chats:
        for prices, retry in (((2, 10), "0"), ((0.1, 0.5), "0.25"), ((10, 50), "1")):
            b = bill(chat, *prices, retry_rate=retry)
            fixture.append({
                "chat": {"system": chat.system, "message": chat.message, "reply": chat.reply, "turns": chat.turns,
                         "reasoning": chat.reasoning, "keep": chat.keep},
                "prices": list(prices), "retry": float(retry), "input": closed_form(chat)[0], "output": closed_form(chat)[1],
                "inputCost": float(b.input_cost), "outputCost": float(b.output_cost), "retryCost": float(b.retry_cost),
                "total": float(b.total),
                "parts": [[k, {"system": p.system, "history": p.history, "message": p.message, "reply": p.reply, "reasoning": p.reasoning}]
                          for k in {1, chat.turns, (chat.turns + 1) // 2} for p in [turn_parts(chat, k)]],
                "turnCosts": [float(turn_cost(chat, k, *prices)) for k in range(1, chat.turns + 1)],
            })
    (tmp_path / "fixture.json").write_text(json.dumps(fixture), encoding="utf-8")
    (tmp_path / "parity.mjs").write_text(PARITY, encoding="utf-8")
    run = subprocess.run(["node", str(tmp_path / "parity.mjs"), str(tmp_path / "fixture.json"), str(WIDGET)],
                         capture_output=True, text=True, timeout=120)
    assert run.returncode == 0, run.stdout + run.stderr
    assert json.loads(run.stdout)["checks"] == len(fixture) >= 1000


def test_widget_starts_from_the_lesson_example():
    """Guards the lesson text and the widget starting from different chats: the config is the lesson's example."""
    cfg = embed_widget.config()
    assert (cfg["system"], cfg["message"], cfg["reply"], cfg["turns"]) == (500, 60, 200, 10)
    assert (cfg["priceIn"], cfg["priceOut"]) == EXAMPLE_PRICES == (2, 10) and cfg["daysPerMonth"] == DAYS_PER_MONTH == 30