On this page
Ask a person how many r’s are in “strawberry” and they look at the letters and say 3. A typical chatbot is given chunk numbers, not those letters. In the small toy version built for this lesson, the word is cut into 7 chunks, and 2 of the 3 r’s sit inside chunks that hold other letters too.
In one minute
An AI model has trouble counting the letters in a word because it usually does not read letters. A program called a tokenizer first cuts your text into chunks called tokens, and the model is given one number for each chunk. Picture being handed numbered cards instead of a word, with the letters printed on the back of each card, where you cannot see them. To count the r’s you would have to remember what is on the back of every card. A model learns many of those spellings from its training text, but it has to recall them rather than look. Writing the word out letter by letter first puts one letter in each chunk, and a tool that runs code can count exactly.
Explore the numbers
Open the widget. It starts on strawberry and the letter r. The top row shows the letters you see. The row beneath shows the chunks the tokenizer cuts, and the row under that shows how many r’s are inside each chunk. Orange marks the letter you chose. Tick “Spell it out” and watch every letter become a chunk of its own, then try words of your own. The widget uses this lesson’s toy tokenizer, built the way What is a token? builds one, and it runs in your browser with no network. Real tokenizers cut words in other places, as the list below shows.
How it works
What the model is given
Each chunk the tokenizer cuts is a token, and each token has a token id, a plain number such as 263. The model is given the ids, not the text. In the toy, strawberry has 10 letters and becomes 7 chunks: st, r, a, w, b, er and ry, with the ids 292, 114, 97, 119, 98, 263 and 587.
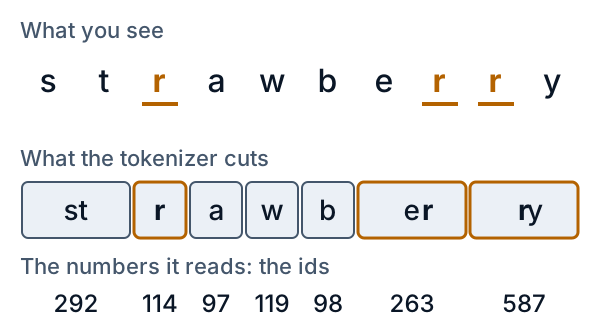
Count the r’s by looking for the id of a lone r, 114, and you find one. The real answer is 3, because two of the r’s are inside er and ry.
The number does not spell its chunk
An id is a label. The tokenizer keeps a table that says 263 stands for er, but the model is given only the 263, and nothing in that number holds an e or an r.
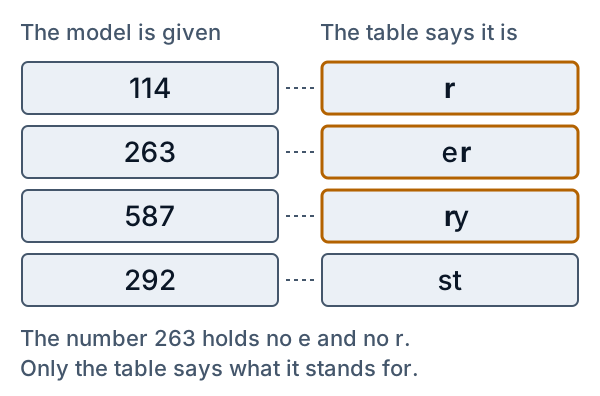
What each id stands for is learned in training. A 2024 test of character skills, CUTE, found that most models it tried seem to know how their tokens are spelled, yet do not use that well to change a text (read 2026-10-19). A second 2024 paper found that most models it tested could not reliably do simple letter tasks that people find easy (read 2026-10-19). Both studied the models of their time.
Real tokenizers cut elsewhere
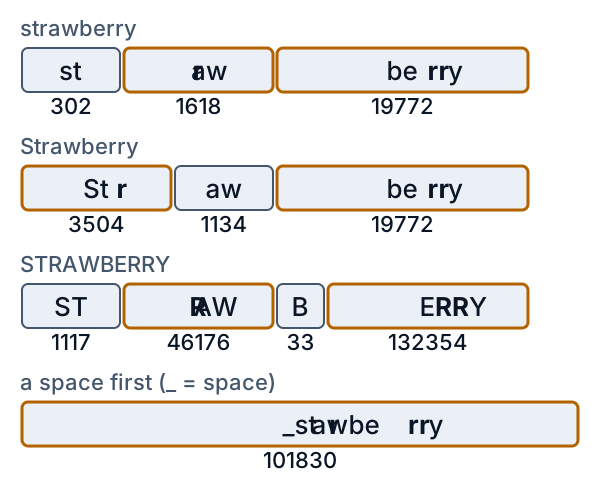
Real tokenizers have far bigger tables than the toy, about 100,000 and 200,000 ids for the two below, called cl100k_base and o200k_base, which come with tiktoken, a free code library from OpenAI. These lines show where each one cuts a word, run with tiktoken 0.14.0 on 2026-10-19. A dot marks each cut.
- strawberry: str · aw · berry in cl100k_base; st · raw · berry in o200k_base.
- Strawberry: Str · aw · berry in both.
- STRAWBERRY: ST · RAW · B · ERRY in both.
- banana: one chunk in both.
- Mississippi: Miss · issippi in both.
- tokenizer: one chunk in cl100k_base; token · izer in o200k_base.
- unbelievable: un · belie · vable in cl100k_base; un · bel · ievable in o200k_base.
Banana is one chunk in both, so its three a’s are inside a single id. Capitals change the cut, and so does a space before the word.
Why spelling it out helps
Write the word as s-t-r-a-w-b-e-r-r-y and both tokenizers cut it between the letters. Each chunk then holds one letter, most with a hyphen, and the three r chunks have the same id: 6335 in o200k_base.
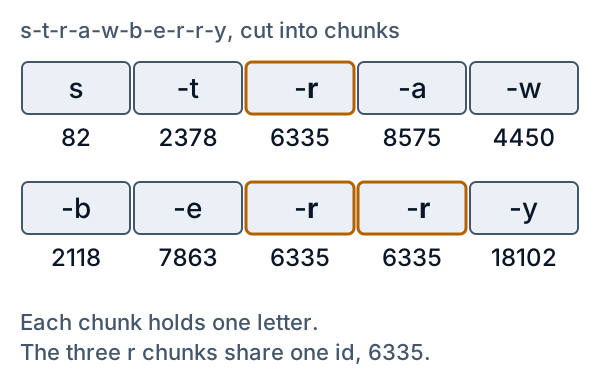
Now counting r’s means counting repeats of one id. A model that writes a word out this way as its first step gives itself that spelled-out text to read. How well that works depends on the model, so test yours.
A tool that runs code avoids the problem. The code is given the text as letters, so the count is exact for the text the code is given. Providers document such tools: OpenAI’s Code Interpreter and Anthropic’s code execution tool both let a model write and run Python code in a sandbox, a sealed space that cannot reach your other files (read 2026-10-19).
What this means when you build
- Use code for exact letter work. Counting letters, checking length, reversing text and finding the third character are exact jobs on a string of letters. Do them in your own code, not in the model’s head.
- Give the model a code tool when users ask for such answers. Both providers named above document one.
- Otherwise ask for the word spelled out first. Then test it on your model and your words, because behaviour changes between versions and one correct answer proves little.
- Test variants. Capitals, a space before a word and hyphens change the chunks, so a word that works once may not work in another writing.
- Expect limits and prices in tokens, not letters. Why is my AI app bill higher than I expected? shows what that does to a bill.
Optionalabout 12 min
Go deeper
Optional. This part is for readers who write Python. The code is in the code/ folder next to this lesson. python3 show_numbers.py prints the toy numbers below, and python3 compare_tiktoken.py prints the real-tokenizer numbers when the tiktoken package is installed.
What a model receives
Everything the model is given about a word is a list of integers. For strawberry the toy gives [292, 114, 97, 119, 98, 263, 587] and o200k_base gives [302, 1618, 19772]. In the toy, the ids 0 to 255 are single bytes, so 114 is the letter r, and each id from 256 up is a merge: id 256 + k is the pair that merge k joins. What is a token? builds the merges. A real table differs in size, not in kind: tiktoken 0.14.0 reports 100,277 ids for cl100k_base and 200,019 for o200k_base.
The same ten letters give different lists under different writings. This is the output of compare_tiktoken.py:
strawberry: 496, 675, 15717 incl100k_base; 302, 1618, 19772 ino200k_base.Strawberry: 2645, 675, 15717 incl100k_base; 3504, 1134, 19772 ino200k_base.STRAWBERRY: 790, 22275, 33, 73995 incl100k_base; 1117, 46176, 33, 132354 ino200k_base.- a space, then
strawberry: 73700 incl100k_base; 101830 ino200k_base.
In cl100k_base the lowercase and capitalised words share the ids of aw and berry and differ only in the first chunk, 496 against 2645. A model has to learn that these lists name nearly the same letters.
Why the count is not in the ids
The tokenizer’s table maps an id to bytes, and a token model is not given the bytes. Two functions in letters.py count the same chunks in two ways. One looks inside each chunk. The other treats ids as letters and counts those equal to the letter’s own id, since ids 0 to 255 are the single bytes:
def count_from_chunks(text, letter, merges):
    return sum(count_inside(spelling, letter) for _, spelling in chunks(text, merges))

def count_ids_that_are_the_letter(text, letter, merges):
    wanted = {ord(letter.lower()), ord(letter.upper())}
    return sum(1 for i, _ in chunks(text, merges) if i in wanted)
For strawberry and r the first returns 3 and the second 1. The second is what you get by reading ids as letters, and it misses every letter inside a bigger chunk. What an id means beyond that is learned, so a model must pick up the spelling of each chunk from training text. This is the kind of gap CUTE measures.
How often does a letter sit in a bigger chunk? On the toy’s own training text, 2,231 words with 9,227 letters become 5,264 chunks, 1.75 letters per chunk, and 72.7% of all letters sit in a chunk of two or more letters. That is a property of this toy, 512 merges learned from 15,793 bytes of text. A production tokenizer has its own figure.
A worked example by hand
Take a tiny table of three merges, applied in the order learned: id 256 is e then r, id 257 is r then y, and id 258 is s then t. Start from the ten bytes of strawberry and apply each merge to every place it fits:
| after | ids | chunks |
|---|---|---|
| bytes | 115 116 114 97 119 98 101 114 114 121 | 10 |
| merge 0 | 115 116 114 97 119 98 256 114 121 | 9 |
| merge 1 | 115 116 114 97 119 98 256 257 | 8 |
| merge 2 | 258 114 97 119 98 256 257 | 7 |
The model is given 258, 114, 97, 119, 98, 256, 257, the same seven chunks the toy makes. Counting ids equal to 114 finds 1 r. Looking inside, the chunks st, r, a, w, b, er and ry hold 0, 1, 0, 0, 0, 1 and 1 r’s: 3 in all. The test test_worked_example_by_hand checks each row of the table and the counts in this paragraph.
Spelled out, in the toy and in tiktoken
spelled_out("strawberry") puts a hyphen between the letters. The toy’s splitting pattern makes a hyphen a piece of its own, so the toy cuts s-t-r-a-w-b-e-r-r-y into 19 chunks: ten letters and nine hyphens. Both tiktoken encodings give 10 chunks, because the hyphen joins the letter after it, as in -r. A space between the letters does the same: r. In both, the most letters in a chunk is 1, for the five words of the widget’s list and both separators, and compare_tiktoken.py prints the check. In o200k_base the three r chunks are all id 6335. After spelling, counting a letter is counting the ids that name that letter.
Models that read characters or bytes
If the chunks cause the trouble, a model could skip them. Several public papers try this, and each has to deal with a longer input: strawberry is 10 bytes and 3 o200k_base chunks.
- ByT5 (Xue et al.) takes text as its byte values, not pieces of a fixed vocabulary.
- CANINE (Clark et al.) reads text one character at a time, with no separate tokenization step.
- Charformer (Tay et al.) starts from characters and learns its own grouping into subword blocks during training.
- MEGABYTE (Yu et al.) groups a byte sequence into patches, with one component for the detail inside a patch and another for how patches relate.
- The Byte Latent Transformer (Pagnoni et al.) also groups bytes into patches, and sets the patch length by how predictable the next byte is. Its authors report that it matches models built on tokens at the scale they tested.
Zhang, Cao and You (2024), a preprint, note that models built for counting often use character-level tokens, while general language models use byte-level byte pair encoding, and report that results vary a great deal with how the input is tokenized. They also note that earlier work found writing out steps can help with counting. This lesson does not say how often any named model counts letters correctly today; it shows the input the model gets.
Proof it works
cd lessons/why-ai-cant-count-letters/code && python3 -m pytest -q
python3 embed_widget.py --check
The tests check these claims. The hand example gives the ids above and counts 1 by ids against 3 by chunks. The lesson’s own numbers are pinned: the seven chunks and ids of strawberry, the 2,231 words and the 72.7%. For the widget’s five example words, counting inside the chunks equals str.count. For 300 random ASCII strings, the chunk spellings join back into the text and the count from chunks equals str.count. Spelled out with a hyphen or a space, no chunk holds two letters, in 200 random words each. Text that is not ASCII is refused rather than counted wrong, and more merges never give more chunks. The widget tests run the widget’s JavaScript under Node.js (so they need it installed) on the ids and spellings of 506 strings at 0, 100 and 512 merges and require the same as the Python, and pin the sentences the widget writes. One more test pins every cut and id of the two published tokenizers printed above, and skips itself when tiktoken is not installed. The embed check fails if the merges or the starting word in widget.html drift from the code.
Where this is used in practice
- tiktoken is an open-source tokenizer library under the MIT licence.
tiktoken.get_encoding("o200k_base")returns an object whoseencodeanddecodegive the ids and the text back, whichcompare_tiktoken.pyuses. - Code tools. Providers run model-written Python in a sandbox, which is how a model can count letters by running
str.countinstead of recalling spellings.
Skills this lesson builds
- Explain why a model is given token ids and not letters, and what that does to letter tasks.
- Cut a word into chunks by hand from a small merge table.
- Compare two tokenizers on the same words with a library and report where they differ.
- Choose between asking the model, asking it to spell first, and giving it a code tool, then test the choice on your words.
- Tell a measured claim about a model from a guess, by its date and its source.
Portfolio project: write a command-line tool that reads a list of words, prints their chunks and ids under two tokenizers, and flags each word where a given letter sits inside a chunk of two or more letters. Publish the table for 50 words of your own.
Check yourself
-
In the toy, strawberry reaches the model as the ids 292, 114, 97, 119, 98, 263 and 587. How many r’s can you find by looking for 114, and why is that not the answer?
Answer
One. The id 114 is a lone r, but two more r’s are inside er (263) and ry (587), and nothing in those ids shows it. The true count is 3.
-
Why does writing a word out as s-t-r-a-w-b-e-r-r-y help a model that must count its letters?
Answer
Both tiktoken encodings then cut it into one chunk per letter, most with a hyphen, so no letter hides in a bigger chunk. In o200k_base every r chunk has the same id, 6335. How well a given model uses this is for you to test.
-
With the tiny table of 256 = e r, 257 = r y and 258 = s t, what ids does
berryget, how many r’s do you find by looking for 114, and how many are there?Answer
The bytes 98 101 114 114 121 become 98 256 114 121 after merge 0 (e r) and 98 256 257 after merge 1 (r y); merge 2 does not apply. Looking for 114 finds none, and
berryhas two r’s, one inside er and one inside ry. -
In
cl100k_base, strawberry is 496, 675, 15717 and Strawberry is 2645, 675, 15717. Which chunks do the two writings share, and what does that say about ids?Answer
They share
aw(675) andberry(15717) and differ only in the first chunk,stragainstStr. An id names a chunk including its capitals, so one capital letter gives a different number for that chunk, and the model must learn that both name nearly the same letters. -
The toy cuts s-t-r-a-w-b-e-r-r-y into 19 chunks, but tiktoken cuts it into 10. Why?
Answer
The toy’s splitting pattern makes each hyphen a piece of its own: 10 letters and 9 hyphens make 19 chunks. In tiktoken, the hyphen joins the letter after it, as in
-r, so each letter and its hyphen are one chunk and there are 10.
Further reading
Web pages were read on 2026-10-19; providers change them.
Gentle
- tiktoken (OpenAI, source code and README)
- Code Interpreter (OpenAI documentation)
- Code execution tool (Anthropic documentation)
Deep
- CUTE: Measuring LLMs’ Understanding of Their Tokens (Edman, Schmid and Fraser, EMNLP 2024)
- Large Language Models Lack Understanding of Character Composition of Words (Shin and Kaneko, 2024)
- Counting Ability of Large Language Models and Impact of Tokenization (Zhang, Cao and You, 2024, preprint)
- ByT5: Towards a token-free future with pre-trained byte-to-byte models (Xue et al., TACL 2022)
- CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation (Clark et al., TACL 2022)
- Charformer: Fast Character Transformers via Gradient-based Subword Tokenization (Tay et al., ICLR 2022)
- MEGABYTE: Predicting Million-byte Sequences with Multiscale Transformers (Yu et al., 2023)
- Byte Latent Transformer: Patches Scale Better Than Tokens (Pagnoni et al., 2024, preprint)
Optional
Code
Each file runs on its own. Download it, or read it here.
Show code
"""Byte-level byte pair encoding (BPE), small enough to read in one sitting.

Ids 0 to 255 are the 256 possible bytes. Training adds one new id per merge: merge number k
(counting from 0) makes id 256 + k out of a pair of existing ids. Encoding then applies the
same merges to new text, so any string can be written as ids and read back exactly.

This file is lesson 1's bpe.py, copied so that this lesson stands alone. The widget in ../widget.html
carries the merges learned here and runs encode() in JavaScript. Two things must stay identical in
both: the splitting pattern PIECE and the merge order that encode() follows.
"""
import re
from collections import Counter
from pathlib import Path

# Split text into pieces first, so a merge never joins across a word and the punctuation after it.
# Letters, digits, punctuation and whitespace each form their own runs; a single leading space
# stays with the word that follows, so " the" and "the" are different pieces. Any character
# outside ASCII counts as a letter. The six alternatives cover every character exactly once.
PIECE = re.compile(
    r" ?[A-Za-z\u0080-\U0010ffff]+"
    r"| ?[0-9]+"
    r"| ?[!-/:-@\[-`{-~]+"
    r"|[ \t\r\n]+(?![^ \t\r\n])"
    r"|[ \t\r\n]+"
    r"|[\x00-\x1f\x7f]"
)

MIN_COUNT = 2  # a pair seen only once is not worth a vocabulary slot
NUM_MERGES = 512  # the lesson's vocabulary: 256 bytes + 512 merges = 768 ids
CORPUS_PATH = Path(__file__).with_name("corpus.txt")


def load_corpus():
    """The training text: written for this lesson, about 15 KB of prose, code, numbers and Korean."""
    return CORPUS_PATH.read_text(encoding="utf-8")


def pieces(text):
    """Split text into the pieces that BPE works inside. Joined back together they equal the text."""
    return PIECE.findall(text)


def train_counted(text, num_merges=NUM_MERGES, min_count=MIN_COUNT):
    """Learn up to num_merges merges. Returns a list of ((left_id, right_id), count) in order.

    Each round counts every adjacent pair of ids inside every piece and merges the most frequent
    one. A tie goes to the smaller (left_id, right_id), so training is deterministic. Training
    stops early when the best pair appears fewer than min_count times.
    """
    words = Counter(tuple(p.encode("utf-8")) for p in pieces(text))
    learned = []
    for _ in range(num_merges):
        pairs = Counter()
        for word, freq in words.items():
            for pair in zip(word, word[1:]):
                pairs[pair] += freq
        if not pairs:
            break
        best = min(pairs, key=lambda pair: (-pairs[pair], pair))
        if pairs[best] < min_count:
            break
        learned.append((best, pairs[best]))
        words = _merge_words(words, best, 255 + len(learned))
    return learned


def train(text, num_merges=NUM_MERGES, min_count=MIN_COUNT):
    """Like train_counted, keeping only the pairs."""
    return [pair for pair, _ in train_counted(text, num_merges, min_count)]


def _apply(word, pair, new_id):
    """Replace every left-to-right occurrence of pair in a tuple of ids with new_id."""
    out = []
    i = 0
    while i < len(word):
        if i + 1 < len(word) and (word[i], word[i + 1]) == pair:
            out.append(new_id)
            i += 2
        else:
            out.append(word[i])
            i += 1
    return tuple(out)


def _merge_words(words, pair, new_id):
    merged = Counter()
    for word, freq in words.items():
        merged[_apply(word, pair, new_id)] += freq
    return merged


def vocab_bytes(merges):
    """The bytes each id stands for: 256 single bytes, then one entry per merge."""
    table = [bytes([b]) for b in range(256)]
    for left, right in merges:
        table.append(table[left] + table[right])
    return table


def encode(text, merges):
    """Turn text into ids. Within a piece, always apply the earliest-learned merge that is present."""
    rank = {pair: k for k, pair in enumerate(merges)}
    cache = {}
    ids = []
    for piece in pieces(text):
        if piece not in cache:
            word = list(piece.encode("utf-8"))
            while len(word) > 1:
                best = min(zip(word, word[1:]), key=lambda pair: rank.get(pair, len(rank)))
                if best not in rank:
                    break
                word = list(_apply(word, best, 256 + rank[best]))
            cache[piece] = word
        ids.extend(cache[piece])
    return ids


def decode(ids, merges):
    """Turn ids back into text. Bytes that are not valid UTF-8 become the replacement character."""
    table = vocab_bytes(merges)
return b"".join(table[i] for i in ids).decode("utf-8", errors="replace")Show code
"""Cut the lesson's words into chunks with two published tokenizers, and with the toy for comparison.

Needs the tiktoken package (pip install tiktoken). The first run of each encoding downloads its
vocabulary file, so it needs network access once; later runs use the cache. Run it from this folder:
python3 compare_tiktoken.py
"""
import sys
from importlib.metadata import version

from letters import DEFAULT_WORD, EXAMPLES, SEPARATOR, chunks, toy_merges

try:
    import tiktoken
except ImportError:
    print("tiktoken is not installed: pip install tiktoken, then run this again.")
    sys.exit(0)

ENCODINGS = ("cl100k_base", "o200k_base")
VARIANTS = (DEFAULT_WORD, " " + DEFAULT_WORD, DEFAULT_WORD.capitalize(), DEFAULT_WORD.upper())

published = {}
for name in ENCODINGS:
    try:
        published[name] = tiktoken.get_encoding(name)
    except Exception as err:  # first use downloads the vocabulary; no network means no encoding
        print(f"skipped {name}: {type(err).__name__}")
if not published:
    sys.exit(0)


def pieces(enc, text):
    """The chunks of text as (id, spelling) pairs. Every text here is ASCII, so each chunk decodes alone."""
    return [(i, enc.decode([i])) for i in enc.encode(text)]


def shown(spelling):
    return spelling.replace(" ", "_")


print(f"tiktoken {version('tiktoken')}; " + ", ".join(f"{n} has {e.n_vocab:,} ids" for n, e in published.items()))

print("\n== Chunks of each word (_ is a space; one line per tokenizer, with its ids)")
for text in dict.fromkeys(tuple(EXAMPLES) + VARIANTS):
    print(f"  {text!r}  ({len(text)} characters)")
    for name, enc in published.items():
        got = pieces(enc, text)
        assert "".join(s for _, s in got) == text and enc.decode(enc.encode(text)) == text
        print(f"    {name:12}{len(got):>3} chunk{'' if len(got) == 1 else 's'}  {' | '.join(shown(s) for _, s in got)}   ids {[i for i, _ in got]}")

print("\n== Spelled out: most letters in one chunk, and the number of chunks")
for text in EXAMPLES:
    for sep in (SEPARATOR, " "):
        spelled = sep.join(text)
        row = []
        for name, enc in published.items():
            got = pieces(enc, spelled)
            row.append(f"{name} {len(got)} chunks, at most {max(sum(c.isalpha() for c in s) for _, s in got)} letter per chunk")
        print(f"  {spelled!r:32}" + "   ".join(row))

print("\n== The toy for comparison")
print(f" {DEFAULT_WORD!r}: " + " | ".join(shown(s) for _, s in chunks(DEFAULT_WORD, toy_merges())))Show code
The harbour town had one bakery, one bridge and one clock that was always five minutes slow. Every morning the baker opened the shutters before the first ferry arrived, and the smell of warm bread drifted down the hill to the water. People who lived there said that you could tell the season by the loaves in the window: dark rye in the winter, seeded rolls in the spring, and flat bread with olives when the tourists came.

A small team can build a useful product when it keeps the work simple. Start with the problem that a real person has today, write down what they need to finish, and build only the part that gets them there. Then measure what happens. If the numbers are good, add the next feature. If the numbers are bad, find out why before writing more code. Most of the time, the answer is boring: a button was hard to find, a page was slow, or a message did not say what to do next.

The library on the hill closes at six in the evening, but the reading room stays open for another hour. Students sit at the long tables with their laptops and their notebooks, and the librarian walks past every ten minutes to turn down the lights near the windows. In the corner there is a shelf of maps, and on the top shelf there is a globe that nobody is allowed to spin.

When you read a recipe, check the time before you check the ingredients. A stew that needs three hours is not a dinner for a Tuesday. Chop the onions, the carrots and the celery into pieces of the same size so that they cook at the same speed. Add the salt early, add the herbs late, and taste the pot before you serve it. If the sauce is too thin, let it simmer with the lid off. If it is too thick, add a little water and stir.

Computers do not read letters. They read numbers, and a program that works with text must first decide how to turn the text into numbers. The simplest choice is to give every character its own number. That works, but it makes the sequences long, and long sequences cost time and memory. A better choice is to give common groups of characters their own numbers, so that a word like the or and takes one step instead of three. These groups are called tokens, and the list of all of them is called the vocabulary.

The tokenizer is a separate program from the model. It is built before the model is trained, from a large pile of text, and then it is frozen. After that, the model only ever sees the numbers that the tokenizer produces. If a word is common in the pile, it gets a token of its own. If a word is rare, it is cut into smaller pieces that the tokenizer already knows. Because the smallest pieces are single bytes, any text at all can be written down, even a word that nobody has used before.

The trade is easy to state. A bigger vocabulary means shorter sequences, but every token needs a row in the tables that the model keeps, and rare tokens are seen so seldom that the model learns little about them. A smaller vocabulary means longer sequences, which cost more at every step. Teams pick a size between the two, test it, and keep it for the whole life of the model.

Engineers measure a tokenizer with a few simple ratios. How many tokens does a page of English need? How many does a page of code need? How many does a page of numbers need? The answers differ, and they differ for a reason: the tokenizer saw some kinds of text far more often than others, and those kinds got the longest and most useful pieces. Text that looks different from the training pile is cut into more and smaller pieces, and the same idea costs more tokens.

Weather in the mountains changes faster than weather on the coast. In the morning the valley is clear, by noon a cloud sits on the ridge, and by evening the wind turns and brings rain from the west. Hikers who start early can finish before the rain, and hikers who start late should carry a coat. The hut at the top has a stove, a kettle and twelve beds, and the keeper writes the temperature on a board by the door.

Please read the notes below before you run the script. The first line sets the name of the project. The second line sets the folder where the files will be written. If the folder does not exist, the script creates it. If the folder already has files in it, the script stops and asks you what to do, because it never deletes anything without being told to.

Rivers carry stones from the mountains to the sea. A stone that starts the size of a fist is the size of a coin when it reaches the delta, and it is the size of a grain of sand by the time the tide takes it. Nothing is lost along the way. The stone is only cut into smaller and smaller pieces, and each piece goes where the water takes it.

Every spring the village holds a market on the square, and every spring it rains for the first hour. The farmers put up their canvas roofs, the children run between the stalls, and the old man who sells honey tells anyone who will listen that the rain is good for the flowers. By noon the sun comes out, the roofs are folded away, and the square fills with people who have walked in from the hills.

Good notes are short. Write the date, write what you decided, and write why you decided it. A month later you will not remember the reason, and the reason is the part you will need. If you wrote down only the decision, you will have to guess, and you might guess wrong. If you wrote down the reason, you can check whether it is still true and change the decision when it is not.

The train to the coast leaves from the third platform, and it is usually on time. It stops at every small station, so the journey takes almost two hours, but nobody minds because the window seats look out over the fields. A woman with a basket of apples sits across from a student with a thick book, and neither of them says a word until the conductor comes by to check the tickets.

Before you change a program, read it. Find the function that does the work, find the tests that cover it, and run the tests to see that they pass. Then make one small change and run the tests again. If a test fails, the change is the first thing to suspect, because the code was working a minute ago. Small steps make mistakes easy to find, and large steps hide them.

Our neighbour keeps bees on the roof of the garage. In summer the air above the garden hums, and in winter the hives are wrapped in old blankets and left alone. He sells the honey to the corner shop, and he gives a jar to anyone who helps him carry the boxes in the autumn. Last year he gave away forty jars and kept six for himself.

A cache is a place where you keep something you will need again, so that you do not have to go and fetch it a second time. A cook keeps salt next to the stove. A programmer keeps the result of a slow calculation in memory. A library keeps the most popular books near the door. The idea is always the same: pay the cost of the first trip once, and make the later trips cheap.

The price of a service usually follows the cost of providing it. A shop pays for its shelves and its staff, so it charges for the goods. A railway pays for its tracks and its engines, so it charges for the distance. A web service pays for its machines and its power, so it charges for the work the machines do. When the work can be counted, the bill can be counted too, and a bill that can be counted can be checked.

On the last night of the festival the whole town walks down to the river with paper lanterns. Each lantern has a name written on it, and the names are of people who are far away or no longer here. The lanterns float slowly toward the bridge, and the crowd goes quiet. Then someone starts to sing, and one by one the others join in, until the song fills the valley.

If you cannot explain an idea in plain words, you probably do not understand it yet. Try it on a friend who has never heard of the subject. Watch where their face changes, because that is where you skipped a step. Go back, add the step, and try again. After three or four rounds the explanation is shorter than the first draft, and you understand the idea better than you did when you started.

Language models read and write tokens. A request to a model is cut into tokens, the model reads all of them, and then it writes its answer one token at a time. Each new token depends on everything that came before it, so the answer cannot be written in parallel. This is why a long answer takes longer than a short one, and why a service that charges by the amount of work charges more for the tokens it writes than for the tokens it reads.

The engineer who counts tokens before shipping a product is the engineer who is not surprised by the bill. Count the tokens in the longest prompt, count the tokens in a typical answer, and multiply by the number of requests you expect. Then change one thing at a time. Shorten the instructions, keep the beginning of the prompt the same on every request, and ask for the answer in the form that needs the fewest words.

def count_words(text):
    counts = {}
    for word in text.split():
        word = word.lower().strip(".,;:!?")
        if word:
            counts[word] = counts.get(word, 0) + 1
    return counts


def top_words(text, limit=10):
    counts = count_words(text)
    ranked = sorted(counts.items(), key=lambda item: (-item[1], item[0]))
    return ranked[:limit]


class Counter:
    def __init__(self, start=0):
        self.value = start

    def increment(self, amount=1):
        self.value += amount
        return self.value

    def reset(self):
        self.value = 0


def read_lines(path):
    with open(path, "r", encoding="utf-8") as handle:
        for line in handle:
            line = line.rstrip("\n")
            if line:
                yield line


def parse_row(line):
    parts = line.split(",")
    if len(parts) != 3:
        raise ValueError("expected three fields, got " + str(len(parts)))
    name, count, price = parts
    return {"name": name, "count": int(count), "price": float(price)}


def total(rows):
    result = 0.0
    for row in rows:
        result += row["count"] * row["price"]
    return result


if __name__ == "__main__":
    rows = [parse_row(line) for line in read_lines("orders.csv")]
    print("total:", total(rows))

function sumPrices(items) {
  let total = 0;
  for (const item of items) {
    if (typeof item.price === "number") {
      total += item.price * item.count;
    }
  }
  return total;
}

const items = [
  { name: "tea", price: 3.5, count: 2 },
  { name: "bread", price: 2.25, count: 4 },
];
console.log(sumPrices(items));

async function loadJson(url) {
  const response = await fetch(url);
  if (!response.ok) {
    throw new Error("request failed: " + response.status);
  }
  return response.json();
}

SELECT name, count(*) AS orders, sum(price) AS revenue
FROM orders
WHERE created_at >= '2026-01-01'
GROUP BY name
HAVING count(*) > 10
ORDER BY revenue DESC
LIMIT 20;

{"name": "tea", "price": 3.5, "tags": ["drink", "hot"], "stock": 120}
{"name": "bread", "price": 2.25, "tags": ["food", "fresh"], "stock": 48}
{"name": "jam", "price": 4.0, "tags": ["food", "sweet"], "stock": 0}

for file in *.txt; do
  echo "$file: $(wc -l < "$file") lines"
done

if (value == null) {
    return defaultValue;
}
for (int i = 0; i < length; i++) {
    sum += values[i];
}

def moving_average(values, window):
    if window <= 0:
        raise ValueError("window must be positive")
    result = []
    for i in range(len(values)):
        start = max(0, i - window + 1)
        chunk = values[start:i + 1]
        result.append(sum(chunk) / len(chunk))
    return result


def merge_dicts(first, second):
    merged = dict(first)
    for key, value in second.items():
        if key in merged and isinstance(merged[key], dict) and isinstance(value, dict):
            merged[key] = merge_dicts(merged[key], value)
        else:
            merged[key] = value
    return merged


try:
    value = int(text)
except ValueError:
    value = None
else:
    print("parsed", value)

import json
import os
from pathlib import Path

data = json.loads(Path("config.json").read_text())
print(data["name"], os.getcwd())


Order 1001 shipped on 2026-03-04 with 12 items for a total of 148.50 dollars.
Order 1002 shipped on 2026-03-05 with 3 items for a total of 27.90 dollars.
Order 1003 shipped on 2026-03-05 with 40 items for a total of 512.00 dollars.
Order 1004 shipped on 2026-03-06 with 7 items for a total of 63.25 dollars.

id   year   value      share
101  2019   12345.67   0.125
102  2020   23456.78   0.250
103  2021   34567.89   0.375
104  2022   45678.90   0.500
105  2023   56789.01   0.625
106  2024   67890.12   0.750
107  2025   78901.23   0.875
108  2026   89012.34   1.000

3.14159 2.71828 1.41421 1.61803 0.57721 6.02214 1.38065 9.80665
1000 2000 3000 4000 5000 6000 7000 8000 9000 10000 20000 50000 100000
0 1 1 2 3 5 8 13 21 34 55 89 144 233 377 610 987 1597 2584 4181
1 2 4 8 16 32 64 128 256 512 1024 2048 4096 8192 16384 32768 65536
2026-01-15 2026-02-03 2026-03-21 2026-04-09 2026-05-30 2026-06-18
0x00 0x01 0x0f 0x10 0x7f 0x80 0xff 0x1000 0xffff
Total: 1,234,567 units, 98.6 percent complete, 45 minutes left.
Temperatures this week: 12, 14, 9, 7, 15, 18, 21 degrees.
Distances: 0.5 km, 1.2 km, 3.8 km, 12.4 km, 42.195 km.
Version 1.2.3, version 2.0.1, version 10.4.17, build 20260315.

Item 7001 costs 19.99, item 7002 costs 24.50, item 7003 costs 5.00, item 7004 costs 105.75.
Latency: 12 ms, 15 ms, 11 ms, 230 ms, 14 ms, 13 ms, 12 ms, 16 ms (median 13.5 ms).
Counts per day: 120 135 128 142 150 98 77 131 140 146 152 160 101 80.
Prices: 0.15 0.30 0.60 1.25 2.50 5.00 10.00 15.00 per million.
Phone-free sample ids: A100 B200 C300 D400 E500 F600 G700 H800 J900.

한국의 가을은 맑고 시원합니다. 아침에는 공기가 차갑지만 낮에는 햇살이 따뜻해서 산책하기에 좋습니다.
저는 매일 아침 일곱 시에 일어나서 따뜻한 차를 마시고 신문을 읽습니다.
도서관은 오후 여섯 시에 문을 닫지만 열람실은 한 시간 더 열려 있습니다.
학생들은 긴 책상에 앉아서 공부를 하고 사서는 십 분마다 한 번씩 책상 사이를 걸어 다닙니다.
오늘은 친구와 함께 시장에 가서 신선한 채소와 과일을 샀습니다.
빵집 주인은 매일 아침 첫 배가 도착하기 전에 문을 열고 따뜻한 빵을 구웠습니다.
기차는 오 분 늦게 도착했지만 승객들은 아무도 불평하지 않았습니다.
컴퓨터는 글자를 읽지 못하고 숫자만 읽을 수 있기 때문에 글을 숫자로 바꾸는 방법이 필요합니다.
토큰은 글을 잘게 나눈 조각이고 어휘는 그 조각들의 목록입니다.
자주 쓰는 단어는 하나의 조각으로 처리하고 드문 단어는 여러 개의 작은 조각으로 나눕니다.
이 프로그램은 파일을 읽어서 단어의 수를 세고 가장 많이 나온 단어를 보여 줍니다.
비가 오는 날에는 우산을 가지고 가고 집에 돌아오면 젖은 옷을 말립니다.
저녁에는 가족과 함께 밥을 먹고 오늘 있었던 일에 대해서 이야기를 나눕니다.
내일은 일찍 일어나서 강가를 따라 달리고 돌아와서 아침을 먹을 생각입니다.
겨울이 오면 산 위에는 눈이 쌓이고 마을에는 조용한 아침이 찾아옵니다.
시장에서 산 사과는 달고 아삭아삭해서 아이들이 아주 좋아했습니다.
선생님은 칠판에 오늘 배울 내용을 쓰고 학생들에게 차례대로 질문을 했습니다.
버스를 타고 한 시간쯤 가면 바다가 보이는 작은 마을에 도착합니다.
좋은 프로그램은 짧고 읽기 쉬우며 실수가 생기면 금방 찾을 수 있어야 합니다.
모델은 글을 한 번에 읽지만 답은 한 조각씩 차례로 씁니다.Show code
"""Keep the merges and the starting word inside ../widget.html equal to the ones here.

    python3 embed_widget.py          rewrite the two data blocks in widget.html
    python3 embed_widget.py --check  exit 1 if widget.html differs (test_widget.py runs the same check)
"""
import json
import re
import sys
from pathlib import Path

from letters import DEFAULT_LETTER, DEFAULT_WORD, EXAMPLES, MAX_WORD, SEPARATOR, toy_merges

WIDGET = Path(__file__).resolve().parent.parent / "widget.html"
CONFIG_BLOCK = re.compile(r'(<script type="application/json" id="ltr-config">)(.*?)(</script>)', re.S)
MERGES_BLOCK = re.compile(r'(<script type="application/json" id="ltr-merges">)(.*?)(</script>)', re.S)


def config():
    return {"word": DEFAULT_WORD, "letter": DEFAULT_LETTER, "maxWord": MAX_WORD, "separator": SEPARATOR,
            "examples": [[word, letter] for word, letter in EXAMPLES.items()]}


def embed(html):
    """html with both data blocks rewritten: the starting state, and the merges the toy tokenizer learns."""
    merges = json.dumps([list(pair) for pair in toy_merges()], separators=(",", ":"))
    html = CONFIG_BLOCK.sub(lambda m: m.group(1) + "\n" + json.dumps(config(), indent=1) + "\n" + m.group(3), html, count=1)
    return MERGES_BLOCK.sub(lambda m: m.group(1) + "\n" + merges + "\n" + m.group(3), html, count=1)


if __name__ == "__main__":
    current = WIDGET.read_text(encoding="utf-8")
    updated = embed(current)
    if "--check" in sys.argv:
        sys.exit(0 if updated == current else 1)
    WIDGET.write_text(updated, encoding="utf-8")
print("widget.html data blocks now match letters.py and the merges of bpe.py")Show code
"""What a model receives for a word, and what counting its letters would need.

A word goes in as a few chunks, and each chunk is one id, a plain number. chunks() shows both sides:
the id the model receives and the spelling that id stands for. Counting a letter means looking inside
the chunks, and the ids alone do not say what is inside them. Words here are ASCII, so one byte is
one letter and a chunk's spelling is always readable.

The tokenizer is the toy of lesson 1 (bpe.py, trained on corpus.txt). The widget in ../widget.html
runs the same merges in JavaScript.
"""
from bpe import encode, load_corpus, train, vocab_bytes

DEFAULT_WORD = "strawberry"
DEFAULT_LETTER = "r"
EXAMPLES = {"strawberry": "r", "banana": "a", "Mississippi": "s", "tokenizer": "e", "unbelievable": "e"}   # word: the letter to count
MAX_WORD = 12        # letters the widget accepts; spelled out, 12 letters take 23 columns on screen
SEPARATOR = "-"      # what "spell it out" puts between the letters


def toy_merges():
    """The merges lesson 1 learns from corpus.txt: 512 of them, so ids 0 to 767."""
    return train(load_corpus())


def chunks(text, merges):
    """text as the model receives it: a list of (id, spelling), one pair per chunk. ASCII text only."""
    if not text.isascii():
        raise ValueError("chunks() reads ASCII text, so that one byte is one letter")
    spelling = vocab_bytes(merges)
    return [(i, spelling[i].decode("ascii")) for i in encode(text, merges)]


def count_inside(spelling, letter):
    """How many times the letter is in the spelling, capital or small."""
    return spelling.lower().count(letter.lower())


def count_from_chunks(text, letter, merges):
    """The count you get by looking inside every chunk and adding up. Doing this is what a model must
    learn: the chunk's spelling lives in the vocabulary table, not in its id."""
    return sum(count_inside(spelling, letter) for _, spelling in chunks(text, merges))


def count_ids_that_are_the_letter(text, letter, merges):
    """The count you get by reading only the ids and counting those that are the letter on its own
    (ids 0 to 255 are single bytes, so 114 is r). Letters inside bigger chunks are missed."""
    wanted = {ord(letter.lower()), ord(letter.upper())}
    return sum(1 for i, _ in chunks(text, merges) if i in wanted)


def spelled_out(word):
    """The word with a hyphen between its letters, the way a person spells it out."""
    return SEPARATOR.join(word)


def share_in_longer_chunks(words, merges):
    """The share of all letters of the words that sit in a chunk of two or more letters."""
    letters = hidden = 0
    for word in words:
        letters += len(word)
        hidden += sum(len(spelling) for _, spelling in chunks(word, merges) if len(spelling) > 1)
return hidden / lettersShow code
"""Print the numbers that lesson.md quotes from the toy tokenizer. Run it from this folder:
python3 show_numbers.py
"""
import re

from bpe import NUM_MERGES, load_corpus
from letters import (DEFAULT_LETTER, DEFAULT_WORD, EXAMPLES, chunks, count_from_chunks, count_ids_that_are_the_letter,
                     count_inside, share_in_longer_chunks, spelled_out, toy_merges)

merges = toy_merges()
print(f"== The toy: 256 bytes + {len(merges)} merges = {256 + len(merges)} ids (NUM_MERGES = {NUM_MERGES})")

print("\n== Examples: letters, chunks, ids")
for word in EXAMPLES:
    got = chunks(word, merges)
    print(f"  {word:14}{len(word):>3} letters {len(got):>3} chunks  {' | '.join(s for _, s in got)}   ids {[i for i, _ in got]}")

word, letter = DEFAULT_WORD, DEFAULT_LETTER
got = chunks(word, merges)
holding = [s for _, s in got if count_inside(s, letter) and len(s) > 1]
print(f"\n== {word!r} and the letter {letter!r}")
print(f"  true count {count_inside(word, letter)}, adding up the chunks' spellings {count_from_chunks(word, letter, merges)},")
print(f"  counting ids that are the letter itself {count_ids_that_are_the_letter(word, letter, merges)}; chunks holding it with other letters: {holding}")

print("\n== Same letters, other writing")
for text in (word, word.capitalize(), word.upper(), " " + word):
    got = chunks(text, merges)
    print(f"  {text!r:16}{len(got):>3} chunks  {' | '.join(s.replace(' ', '_') for _, s in got)}   ids {[i for i, _ in got]}")

print("\n== Spelled out with hyphens")
text = spelled_out(word)
got = chunks(text, merges)
print(f"  {text!r}: {len(got)} chunks, most letters in one chunk {max(sum(c.isalpha() for c in s) for _, s in got)}")
print(f"  ids {[i for i, _ in got]}")

print("\n== Letters in chunks of two or more letters, on the toy's own training text")
words = re.findall(r"[A-Za-z]+", load_corpus())
n_chunks = sum(len(chunks(w, merges)) for w in words)
letters = sum(len(w) for w in words)
print(f"  {len(words):,} words, {letters:,} letters, {n_chunks:,} chunks: {letters / n_chunks:.2f} letters per chunk,"
f" {100 * share_in_longer_chunks(words, merges):.1f}% of letters in a chunk of 2 or more")Show code
import random
import re
import string

import pytest

from bpe import NUM_MERGES, load_corpus, pieces
from letters import (DEFAULT_LETTER, DEFAULT_WORD, EXAMPLES, MAX_WORD, SEPARATOR, chunks, count_from_chunks,
                     count_ids_that_are_the_letter, count_inside, share_in_longer_chunks, spelled_out, toy_merges)

MERGES = toy_merges()
CORPUS = load_corpus()

# The lesson's hand example: three merges, in the order they were learned. er is id 256, ry is 257, st is 258.
TINY = [(101, 114), (114, 121), (115, 116)]


def test_worked_example_by_hand():
    """The Go-deeper walk-through. e+r is the first merge, so it fires first; r+y is next (the r of 'er' is
    already gone, so only the last r can join the y); s+t is last. The ids end as [258, 114, 97, 119, 98, 256, 257].
    Counting ids equal to 114 finds one r; adding up the spellings finds three."""
    rows = [[115, 116, 114, 97, 119, 98, 101, 114, 114, 121], [115, 116, 114, 97, 119, 98, 256, 114, 121],
            [115, 116, 114, 97, 119, 98, 256, 257], [258, 114, 97, 119, 98, 256, 257]]
    assert [[i for i, _ in chunks("strawberry", TINY[:k])] for k in range(4)] == rows
    assert [i for i, _ in chunks("strawberry", TINY)] == [258, 114, 97, 119, 98, 256, 257]
    assert [s for _, s in chunks("strawberry", TINY)] == ["st", "r", "a", "w", "b", "er", "ry"]
    assert count_ids_that_are_the_letter("strawberry", "r", TINY) == 1
    assert count_from_chunks("strawberry", "r", TINY) == 3


def test_check_yourself_berry_example():
    """Quiz 3: with the tiny table, berry is [98, 256, 257] (merge 2, s+t, does not apply); looking for 114 finds
    none, and the chunks er and ry hold two r's."""
    assert [i for i, _ in chunks("berry", TINY)] == [98, 256, 257]
    assert count_ids_that_are_the_letter("berry", "r", TINY) == 0
    assert count_from_chunks("berry", "r", TINY) == 2


def test_lesson_numbers():
    """Guards the figures the lesson quotes. A change to bpe.py, corpus.txt or the word list moves them, and the
    lesson text, figures and widget would then disagree with this code."""
    assert (DEFAULT_WORD, DEFAULT_LETTER) == ("strawberry", "r")
    assert len(MERGES) == NUM_MERGES == 512
    got = chunks("strawberry", MERGES)
    assert [i for i, _ in got] == [292, 114, 97, 119, 98, 263, 587]
    assert [s for _, s in got] == ["st", "r", "a", "w", "b", "er", "ry"]
    assert count_from_chunks("strawberry", "r", MERGES) == 3
    assert count_ids_that_are_the_letter("strawberry", "r", MERGES) == 1
    words = re.findall(r"[A-Za-z]+", CORPUS)
    assert len(words) == 2231 and sum(map(len, words)) == 9227
    assert round(100 * share_in_longer_chunks(words, MERGES), 1) == 72.7


@pytest.mark.parametrize("word,letter", EXAMPLES.items())
def test_every_widget_example_counts_the_same_both_ways(word, letter):
    """Guards an example whose chunk spellings and plain str.count disagree (a chunk dropped or split wrong)."""
    assert count_from_chunks(word, letter, MERGES) == word.lower().count(letter.lower())


def test_chunks_partition_the_text_for_random_ascii():
    """Guards a tokenizer that loses or repeats a character: the spellings of the chunks, joined, must be the text
    (spaces, hyphens and capitals included), and the letter count from chunks must equal str.count."""
    rng = random.Random(7)
    alphabet = string.ascii_letters + " -"
    for _ in range(300):
        text = "".join(rng.choice(alphabet) for _ in range(rng.randint(1, 14)))
        got = chunks(text, MERGES)
        assert "".join(s for _, s in got) == text
        letter = rng.choice(string.ascii_lowercase)
        assert count_from_chunks(text, letter, MERGES) == text.lower().count(letter)


def test_ids_alone_miss_letters_inside_longer_chunks():
    """The lesson's point: reading ids as letters undercounts whenever a letter sits in a bigger chunk."""
    assert count_ids_that_are_the_letter("strawberry", "r", MERGES) < count_from_chunks("strawberry", "r", MERGES)
    assert count_ids_that_are_the_letter("banana", "a", MERGES) == 1 and count_from_chunks("banana", "a", MERGES) == 3


@pytest.mark.parametrize("separator", [SEPARATOR, " "])
def test_spelled_out_words_have_one_letter_per_chunk(separator):
    """Guards the claim 'spell it out and every letter becomes a chunk of its own': in the toy, no chunk of a
    hyphen- or space-separated word holds two letters."""
    rng = random.Random(11)
    for _ in range(200):
        word = "".join(rng.choice(string.ascii_lowercase) for _ in range(rng.randint(1, MAX_WORD)))
        spelled = separator.join(word)
        assert max(sum(c.isalpha() for c in s) for _, s in chunks(spelled, MERGES)) == 1
    assert spelled_out("abc") == "a-b-c"


def test_non_ascii_text_is_refused():
    """Guards a silent wrong answer: a multi-byte character splits into bytes whose spellings cannot be shown."""
    with pytest.raises(ValueError):
        chunks("café", MERGES)


def test_more_merges_never_make_more_chunks():
    """The widget's 'merges used' slider: each extra merge can only join pieces, so the chunk count never rises
    and at zero merges every character is a chunk."""
    word = "unbelievable"
    sizes = [len(chunks(word, MERGES[:k])) for k in (0, 1, 10, 100, 300, 512)]
    assert sizes == sorted(sizes, reverse=True) and sizes[0] == len(word)


def test_capitals_and_a_leading_space_change_the_ids():
    """Guards the lesson's note that the same letters can reach the model as different ids."""
    plain = [i for i, _ in chunks("strawberry", MERGES)]
    assert [i for i, _ in chunks(" strawberry", MERGES)] != plain
    assert [i for i, _ in chunks("STRAWBERRY", MERGES)] != plain
    assert len(chunks("STRAWBERRY", MERGES)) == 10


def test_count_inside_ignores_case():
    assert count_inside("Err", "r") == 2 and count_inside("er", "R") == 1


def test_pieces_are_what_the_tokenizer_cuts_first():
    """The widget runs PIECE as a JavaScript regex; a hyphen is its own piece, so a spelled-out word never merges."""
    assert pieces("s-t") == ["s", "-", "t"]


# Cuts and ids the lesson prints for the published tokenizers (tiktoken 0.14.0, run 2026-10-19). "|" marks a cut.
CUTS = {
    "strawberry": ("str|aw|berry", "st|raw|berry"),
    "Strawberry": ("Str|aw|berry", "Str|aw|berry"),
    "STRAWBERRY": ("ST|RAW|B|ERRY", "ST|RAW|B|ERRY"),
    " strawberry": (" strawberry", " strawberry"),
    "banana": ("banana", "banana"),
    "Mississippi": ("Miss|issippi", "Miss|issippi"),
    "tokenizer": ("tokenizer", "token|izer"),
    "unbelievable": ("un|belie|vable", "un|bel|ievable"),
}
IDS = {
    "strawberry": ([496, 675, 15717], [302, 1618, 19772]),
    "Strawberry": ([2645, 675, 15717], [3504, 1134, 19772]),
    "STRAWBERRY": ([790, 22275, 33, 73995], [1117, 46176, 33, 132354]),
    " strawberry": ([73700], [101830]),
}


def test_published_tokenizer_numbers_in_the_lesson():
    """Guards the lesson's table, figures and quiz against a library or vocabulary that moves: every cut and id the
    lesson prints for cl100k_base and o200k_base, and the id shared by the three r chunks of the spelled-out word.
    Skipped when tiktoken or its vocabulary files are not available."""
    tiktoken = pytest.importorskip("tiktoken")
    try:
        encs = [tiktoken.get_encoding(name) for name in ("cl100k_base", "o200k_base")]
    except Exception as err:  # the first use downloads the vocabulary
        pytest.skip(f"vocabulary not available: {type(err).__name__}")
    assert [(e.name, e.n_vocab) for e in encs] == [("cl100k_base", 100277), ("o200k_base", 200019)]
    for text, want in CUTS.items():
        for enc, cut in zip(encs, want):
            assert "|".join(enc.decode([i]) for i in enc.encode(text)) == cut, (text, enc.name)
    for text, want in IDS.items():
        for enc, ids in zip(encs, want):
            assert enc.encode(text) == ids, (text, enc.name)
    for enc, r_id in zip(encs, (3880, 6335)):
        spelled = enc.encode(SEPARATOR.join("strawberry"))
        assert len(spelled) == 10 and [i for i in spelled if i == r_id] == [r_id] * 3
assert [enc.decode([i]) for i in spelled][2] == "-r"Show code
"""Guards for ../widget.html: its data blocks, its size, its wording, and that its tokenizer is bpe.py's."""
import json
import random
import re
import shutil
import string
import subprocess

import pytest

import embed_widget
from embed_widget import WIDGET, embed
from letters import MAX_WORD, SEPARATOR, chunks, toy_merges

HTML = WIDGET.read_text(encoding="utf-8")
MERGES = toy_merges()

# Reads the tokenizer out of the widget between its marker comments (everything above "state" needs the page),
# runs it, and compares with the ids, spellings and start offsets Python wrote into the fixture.
PARITY = r"""
import fs from 'node:fs';
const [fixture, widget] = process.argv.slice(2);
const fx = JSON.parse(fs.readFileSync(fixture, 'utf8'));
const html = fs.readFileSync(widget, 'utf8');
const merges = JSON.parse(html.match(/id="ltr-merges">\s*([\s\S]*?)\s*<\/script>/)[1]);
const js = html.slice(html.indexOf('/* ---------- the tokenizer'), html.indexOf('/* ---------- state'));
const api = new Function("'use strict'; var merges = arguments[0];" + js + '; return {chunks};')(merges);
const bad = [];
for (const f of fx) {
  const got = api.chunks(f.text, f.k).map(c => [c.id, c.text, c.start]);
  if (JSON.stringify(got) !== JSON.stringify(f.want)) bad.push([f.text, f.k, got, f.want]);
}
console.log(JSON.stringify({ checks: fx.length, bad: bad.slice(0, 5) }));
process.exit(bad.length ? 1 : 0);
"""

# Calls describe() the way paint() does and prints the sentences it builds.
SENTENCES = r"""
import fs from 'node:fs';
const html = fs.readFileSync(process.argv[2], 'utf8');
const merges = JSON.parse(html.match(/id="ltr-merges">\s*([\s\S]*?)\s*<\/script>/)[1]);
const js = html.slice(html.indexOf('/* ---------- the tokenizer'), html.indexOf('/* ---------- state'));
const api = new Function("'use strict'; var merges = arguments[0];" + js + '; return {chunks, describe};')(merges);
const out = [];
for (const [word, text, letter, k] of [['strawberry', 'strawberry', 'r', 512], ['strawberry', 'strawberry', 'e', 512],
    ['strawberry', 'strawberry', 'z', 512], ['strawberry', 'strawberry', 'r', 0], ['strawberry', 's-t-r-a-w-b-e-r-r-y', 'r', 512],
    ['a', 'a', 'a', 512], ['the', 'the', 'h', 512], ['Strawberry', 'Strawberry', 'S', 512]]) {
  const d = api.describe(word, text, letter, api.chunks(text, k));
  out.push([d.n, d.headline, d.cut, d.ids, d.verdict]);
}
console.log(JSON.stringify(out));
"""

SENTENCES_WANT = [
    [3, "The letter r is in “strawberry” 3 times.", "The toy cuts “strawberry” into 7 chunks: st | r | a | w | b | er | ry.",
     "The model is given these numbers: 292, 114, 97, 119, 98, 263, 587.",
     "The r hides inside 2 chunks that hold other letters too: er (263), ry (587). The numbers alone do not say which letters are inside."],
    [1, "The letter e is in “strawberry” once.", "The toy cuts “strawberry” into 7 chunks: st | r | a | w | b | er | ry.",
     "The model is given these numbers: 292, 114, 97, 119, 98, 263, 587.",
     "The e hides inside 1 chunk that holds other letters too: er (263). The number alone does not say which letters are inside."],
    [0, "The letter z is not in “strawberry”.", "The toy cuts “strawberry” into 7 chunks: st | r | a | w | b | er | ry.",
     "The model is given these numbers: 292, 114, 97, 119, 98, 263, 587.", "No chunk holds the letter z."],
    [3, "The letter r is in “strawberry” 3 times.", "The toy cuts “strawberry” into 10 chunks: s | t | r | a | w | b | e | r | r | y.",
     "The model is given these numbers: 115, 116, 114, 97, 119, 98, 101, 114, 114, 121.", "Every r is a chunk of its own, the easy case."],
    [3, "The letter r is in “strawberry” 3 times.",
     "The toy cuts “s-t-r-a-w-b-e-r-r-y” into 19 chunks: s | - | t | - | r | - | a | - | w | - | b | - | e | - | r | - | r | - | y.",
     "The model is given these numbers: 115, 45, 116, 45, 114, 45, 97, 45, 119, 45, 98, 45, 101, 45, 114, 45, 114, 45, 121.",
     "Every r is a chunk of its own, the easy case."],
    [1, "The letter a is in “a” once.", "The toy keeps “a” whole, as 1 chunk.", "The model is given this number: 97.",
     "Every a is a chunk of its own, the easy case."],
    [1, "The letter h is in “the” once.", "The toy cuts “the” into 2 chunks: t | he.", "The model is given these numbers: 116, 257.",
     "The h hides inside 1 chunk that holds other letters too: he (257). The number alone does not say which letters are inside."],
    [1, "The letter S is in “Strawberry” once.", "The toy cuts “Strawberry” into 8 chunks: S | t | r | a | w | b | er | ry.",
     "The model is given these numbers: 83, 116, 114, 97, 119, 98, 263, 587.", "Every S is a chunk of its own, the easy case."],
]


def with_offsets(pairs):
    """[id, spelling, start] for each (id, spelling): where the chunk begins in the text, as the widget's grid needs."""
    start, out = 0, []
    for i, s in pairs:
        out.append([i, s, start])
        start += len(s)
    return out


def run_node(tmp_path, name, script, *args):
    (tmp_path / name).write_text(script, encoding="utf-8")
    return subprocess.run(["node", str(tmp_path / name), *args], capture_output=True, text=True, timeout=120)


def test_widget_data_blocks_match_the_python_code():
    """Guards a change to the merges, the starting word or the examples in the code that was not copied into the
    widget (run embed_widget.py)."""
    assert embed(HTML) == HTML


def test_every_element_the_script_looks_up_exists_where_it_looks():
    """Guards a widget that never starts: a lookup of an id that is not in the markup throws in the browser, and
    two elements with one id (the range and the merges data block once shared ltr-merges) make a lookup return the wrong one."""
    root = HTML[HTML.index('<div class="ltr-root">'):HTML.index("<script")]
    script = HTML[HTML.index("<script>"):]
    listed = script[script.index("['ltr-word'"):script.index("].forEach")]
    ids = set(re.findall(r"\$\('([\w-]+)'\)", script)) | set(re.findall(r"'(ltr-[\w-]+)'", listed))
    assert ids and all(f'id="{i}"' in root for i in ids), sorted(i for i in ids if f'id="{i}"' not in root)
    assert "$('ltr-config')" not in script and "$('ltr-merges')" not in script
    every_id = re.findall(r'\sid="([\w-]+)"', HTML)
    assert len(every_id) == len(set(every_id)), sorted(i for i in set(every_id) if every_id.count(i) > 1)


def test_widget_is_small_and_asks_for_nothing_online():
    """The widget runs in a sandbox that cannot open links, and says it uses no network: it holds no address."""
    assert len(HTML.encode("utf-8")) < 40 * 1024
    page = embed_widget.MERGES_BLOCK.sub("", embed_widget.CONFIG_BLOCK.sub("", HTML))
    for banned in ("http://", "https://", "fetch(", "XMLHttpRequest", "WebSocket", "sendBeacon", "import("):
        assert banned not in page, banned
    assert " src=" not in page and "@import" not in page


def test_widget_has_no_form_element():
    """The lesson page loads the widget in a sandbox where a form cannot submit; inputs are read on change."""
    assert "<form" not in HTML


def test_widget_shows_four_controls_and_keeps_the_rest_under_more_settings():
    """Guards the brief's limit on visible controls: the word, the letter, the example list and the spell-out box
    sit in the open, and the merge slider is inside a closed details element."""
    open_part, _, more = HTML[HTML.index('<div class="ltr-ctl">'):HTML.index("</details>")].partition('<details class="ltr-more">')
    assert len(re.findall(r"<(?:input|select)\b", open_part)) == 4
    assert "<summary>More settings</summary>" in more and 'type="range"' in more and "<details open" not in HTML


def test_widget_sentences_read_right(tmp_path):
    """Guards the plural slips ('1 chunks', 'these numbers' for one id), the wording of the verdict for a hidden letter,
    an easy letter, a missing letter, a one-chunk word and a capital letter, and the lesson's starting word."""
    if shutil.which("node") is None:
        pytest.skip("Node.js is not installed")
    run = run_node(tmp_path, "sentences.mjs", SENTENCES, str(WIDGET))
    assert run.returncode == 0, run.stdout + run.stderr
    assert json.loads(run.stdout) == SENTENCES_WANT


def test_widget_tokenizer_matches_the_python_code(tmp_path):
    """Guards the widget's JavaScript drifting from bpe.py: for random ASCII text (capitals, spaces, hyphens, digits,
    punctuation) and for the lesson's words, with 0, 100 and all merges, ids, spellings and start offsets must be equal."""
    if shutil.which("node") is None:
        pytest.skip("Node.js is not installed")
    rng = random.Random(3)
    alphabet = string.ascii_letters * 3 + string.digits + " -.,'\n\t"
    texts = ["strawberry", " strawberry", "Strawberry", "STRAWBERRY", SEPARATOR.join("strawberry"), " ".join("banana")]
    texts += ["".join(rng.choice(alphabet) for _ in range(rng.randint(1, 24))) for _ in range(250)]
    texts += ["".join(rng.choice(string.ascii_lowercase) for _ in range(rng.randint(1, MAX_WORD))) for _ in range(250)]
    fixture = [{"text": t, "k": k, "want": with_offsets(chunks(t, MERGES[:k]))} for t in texts for k in (0, 100, len(MERGES))]
    (tmp_path / "fixture.json").write_text(json.dumps(fixture), encoding="utf-8")
    run = run_node(tmp_path, "parity.mjs", PARITY, str(tmp_path / "fixture.json"), str(WIDGET))
    assert run.returncode == 0, run.stdout + run.stderr
    assert json.loads(run.stdout)["checks"] == len(fixture) >= 1500


def test_widget_starts_from_the_lesson_example():
    """Guards the lesson text and the widget starting from different words: the config is strawberry and r."""
    cfg = embed_widget.config()
    assert (cfg["word"], cfg["letter"], cfg["maxWord"], cfg["separator"]) == ("strawberry", "r", MAX_WORD, "-")
    assert ["strawberry", "r"] in cfg["examples"]